
DeepSeek-VL 7B
deepseek-vl-7bDeepSeek-VL 7B chat model. Vision-language model with hybrid vision encoder and strong real-world visual question answering performance.
- Çmim
- ≈ 0,0086 US$/ekz
- Kontekst
- 4096 token
- Dalja maks.
- 2048 token
- Hyrje → Dalje
- Tekst + Imazh → Tekst
- Zhvillues
- DeepSeek
- Përditësuar
- 23 shtator 2026
Loja e lojërave
Provo DeepSeek-VL 7B
Nuk ka formë hyrjeje
Nuk ka ende formë hyrjeje për këtë model
Hyrjet e tij nuk janë dokumentuar ende. Në mënyrë që asnjë ekzekutim të mos dështojë në një hyrje të gabuar, nuk ofrojmë një formë këtu. Zgjidh një model të krahasueshëm në vend të tij.
Examples
 Input
Prompt
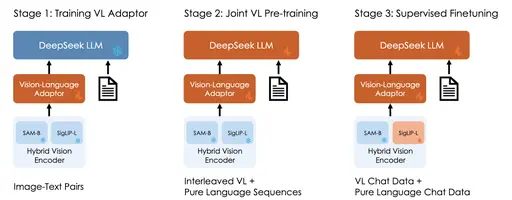
Describe each stage of this image
Response
The image depicts a three-stage process for training a vision-language model. 1. Stage 1: Training VL Adapter: In this stage, a vision-language adapter is trained using supervised fine-tuning. The adapter is trained on image-text pairs and pure language sequences. 2. Stage 2: Joint VL Pre-training: In this stage, a joint vision-language model is pre-trained using self-supervised learning. The model is trained on image-text pairs and pure language sequences. 3. Stage 3: Supervised Fine-tuning: In this stage, the model is fine-tuned on supervised tasks using image-text pairs and pure language sequences. The model is trained using a hybrid vision-language adapter, which combines a vision-language adapter with a language model. The model is trained on a variety of tasks, including image captioning, visual question answering, and visual reasoning. The model is able to understand the visual content of an image and generate a natural language description or answer.
 Input
Prompt
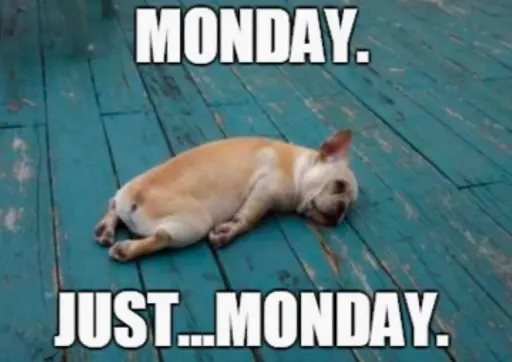
Describe this image
Response
The image you've provided is a meme featuring a French Bulldog lying on its side on a blue wooden floor. The dog's head is resting on its paws, and it appears to be sleeping. The meme has a text overlay that reads "MONDAY. JUST...MONDAY." This suggests that the meme is making a humorous comment about the start of the work week. The dog's relaxed posture and the text overlay together create a light-hearted and relatable message.
Rreth DeepSeek-VL 7B
DeepSeek-VL 7B është një model i DeepSeek në kategorinë Multimodal. Në Railwail, DeepSeek-VL 7B kushton ≈ 0,0086 US$ për ekzekutim. Dritarja e kontekstit përmban 4096 token, dhe një përgjigje mund të jetë deri në 2048 token e gjatë.
Çmimet
| Ekzekutim tipik (≈ 7 s në L40S) | 0,0086 US$ për ekzekutim |
|---|---|
| Koha GPU (L40S) | 0,00117 US$ për sekondë GPU |
- Faturohet sipas kohës GPU që ekzekutimi në të vërtetë merr. Kur ekzekutimi fillon, 3× çmimi tipik rezervohet nga bilanci yt dhe zgjidhet më pas.
- 1 kredi = 0,01 US$
Kalkulator i kostos
Kalkulator çmimesh
Tipike sipas ofruesi: rreth 7,3 s
Gjithsej
0,86 US$
86 kredite
Për ekzekutim
0,0086 US$ · 0,86 kredite
Faturohet koha aktuale e GPU; kjo është një vlerësim.
API
Nuk ka shembull API të verifikuar
API publike kalon një format hyrjeje të ndryshëm nga ai që ky model ka nevojë. Përdor lojërat më lart.
Specifikacione
- ID i modelit
deepseek-vl-7b- Zhvilluesi
- DeepSeek
- Kategoria
- Multimodal
- Hyrja
- Tekst, Imazh
- Dalja
- Tekst
- Dritarja e kontekstit
- 4096 token
- Dalja maks.
- 2048 token
- Faturimi
- Sipas përdorimit (token ose kohë GPU)
- Katalogu i përditësuar
- 23 shtator 2026
Etiketat
- replicate
- multimodal
- vision-understanding
- deepseek
- open-weights
Pyetje të shpeshta
Çfarë është DeepSeek-VL 7B?
DeepSeek-VL 7B është një model nga DeepSeek në kategorinë Multimodal.
Sa kushton DeepSeek-VL 7B në Railwail?
Në Railwail, DeepSeek-VL 7B kushton ≈ 0,0086 US$ për ekzekutim. Të tarifohesh për atë që çdo kërkesë në fakt përdor. Përdorimi paguhet nga kredite të parapaguar; 1 kredit barazon 0,01 US$.
Cila është dritarja e kontekstit të DeepSeek-VL 7B?
Dritarja e kontekstit të DeepSeek-VL 7B përmban 4096 token. Një përgjigje mund të jetë deri në 2048 token e gjatë.
Sa i shpejtë është DeepSeek-VL 7B?
Nuk ka ende mjaft ekzekutime të matura të DeepSeek-VL 7B në Railwail për të deklaruar një kohë ekzekutimi. Varet nga hyrja, cilësimet dhe ngarkesa në ofruesin e shërbimit.
A është DeepSeek-VL 7B më i mirë se BLIP?
Varet nga detyra. DeepSeek-VL 7B (DeepSeek) dhe BLIP (Salesforce) janë të dy modele në kategorinë Multimodal. Faqja e krahasimit tregon çmimet dhe specifikacimet e tyre krah për krah.
Krahaso DeepSeek-VL 7B dhe BLIPA mund të përpunojë DeepSeek-VL 7B imazhe?
Po. DeepSeek-VL 7B pranon imazhe si hyrje përveç tekstit.
Modele të krahasueshme
Të gjitha në këtë kategori- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
Të gjitha modelet përmes një API
Një çelës API për çdo model në Railwail. Përdorimi ngarkohet nga kreditet e parapaguar, 1 kredit = 0,01 US$.