
LLaVA 1.6 Vicuna 13B
llava-1-6-vicuna-13bLLaVA 1.6 (LLaVA-NeXT) with a Vicuna-13B language backbone. Open vision-language chat model that describes images, answers questions, reads charts and reasons about scenes. Version 1.6 adds higher input resolution and better OCR and reasoning than LLaVA 1.5.
- Preis
- ca. $ 0,1021/Lauf
- Kontext
- 4 096 Token
- Max. Ausgabe
- 1 024 Token
- Eingabe → Ausgabe
- Text + Bild → Text
- Entwickler
- Community
- Aktualisiert
- 23. September 2026
Playground
LLaVA 1.6 Vicuna 13B ausprobieren
Eingabe & Ergebnis
Dieser Lauf
ca. $ 0,1021 · 10,21 Credits
Beim Start werden $ 0,3061 (30,61 Credits) vorgemerkt, abgerechnet wird die tatsächliche GPU-Zeit.
Für Konten ohne bisherigen Kauf: Läufe über 2 Credits brauchen eine Aufladung.
Neu hier?
10 Gratis-Credits ($ 0,10) bei Anmeldung mit Google
Nutzbar 24 Stunden nach der Anmeldung, bis zu 5 Läufe pro Tag und höchstens 2 Credits je Lauf. Andere Anmeldearten starten ohne Guthaben.
Beispiele
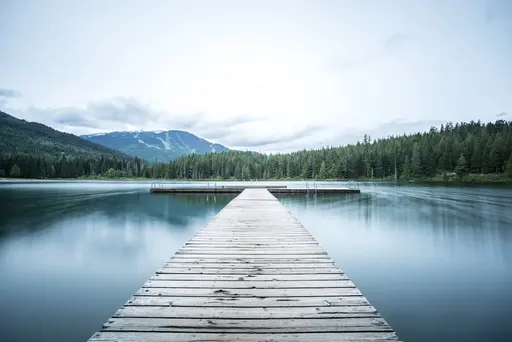 Eingabe
Prompt
What should I take into account when visiting this place?
Antwort
When visiting a place like the one shown in the image, which appears to be a serene lake with a dock and surrounded by mountains and forests, you should consider the following: 1. **Weather Conditions**: Be prepared for the local weather. It can change rapidly, especially in mountainous areas, so check the forecast and dress in layers. 2. **Safety**: If you plan to go on the water, make sure you have a life jacket and know how to swim. If you're not a strong swimmer, consider wearing a life jacket even if you're just walking along the shore. 3. **Wildlife**: Be aware of the local wildlife and maintain a safe distance. Do not feed the animals, as this can disrupt their natural behavior and diet. 4. **Leave No Trace**: Respect the environment by not littering and by staying on designated paths or trails. 5. **Emergency Preparedness**: Have a first aid kit and know basic first aid. It's also a good idea to have a way to contact emergency services if needed. 6. **Navigation**: If you're going into the woods or on the water, have a map or GPS device and know how to use it. 7. **Hydration and Nutrition**: Bring enough water and food for your visit, especially if you'll be active. 8. **Clothing and Gear**: Wear appropriate clothing for the weather and activities you plan to do. Bring sturdy footwear if you plan to hike or walk on uneven terrain. 9. **Local Regulations**: Follow any posted rules or regulations, which might include fishing regulations, fire restrictions, or…
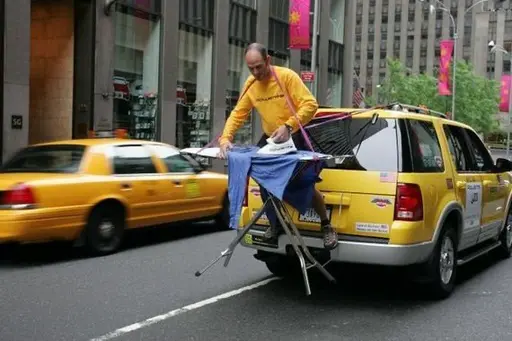 Eingabe
Prompt
What is unusual about this image?
Antwort
The image shows a person ironing clothes on the back of a moving vehicle, which is an unusual and potentially dangerous activity. Ironing clothes while a vehicle is in motion can be hazardous for the person doing the ironing as well as for other road users. The person is at risk of losing balance and falling off the vehicle, which could result in serious injury. Additionally, the iron could potentially cause a fire or damage to the vehicle or its surroundings if it overheats or malfunctions. This scene is not a safe or typical way to iron clothes and is likely staged for comedic or dramatic effect.
Über LLaVA 1.6 Vicuna 13B
LLaVA 1.6 Vicuna 13B ist ein Modell von Community aus der Kategorie Multimodal. Über Railwail kostet LLaVA 1.6 Vicuna 13B ca. $ 0,1021 pro Lauf. Das Kontextfenster umfasst 4 096 Token, eine Antwort bis zu 1 024 Token.
Preise
| Typischer Lauf (ca. 87 s auf L40S) | $ 0,1021 pro Lauf |
|---|---|
| GPU-Zeit (L40S) | $ 0,00117 pro GPU-Sekunde |
- Abgerechnet wird die GPU-Zeit, die der Lauf tatsächlich braucht. Beim Start wird das 3-Fache des typischen Preises vom Guthaben vorgemerkt und danach verrechnet.
- 1 Credit = $ 0,01
Kostenrechner
Preisrechner
Typisch laut Anbieter: ca. 87,2 s
Gesamt
$ 10,21
1 021 Credits
Je Lauf
$ 0,1021 · 10,21 Credits
Abgerechnet wird die tatsächliche GPU-Zeit; der Wert ist eine Schätzung.
API
Kein geprüftes API-Beispiel
Die öffentliche API übergibt ein anderes Eingabeformat, als dieses Modell braucht. Nutze den Playground oben.
Spezifikationen
- Modell-ID
llava-1-6-vicuna-13b- Entwickler
- Community
- Kategorie
- Multimodal
- Eingabe
- Text, Bild
- Ausgabe
- Text
- Kontextfenster
- 4 096 Token
- Max. Ausgabe
- 1 024 Token
- Abrechnung
- Nach Verbrauch (Token bzw. GPU-Zeit)
- Katalogeintrag aktualisiert
- 23. September 2026
Eingabeparameter
Eingaben und Einstellungen laut Eingabeschema des Modells. Welche davon die API annimmt, zeigt das Beispiel im Abschnitt API.
imagePflichtImage to analyze
Typ: TextStandard: –Erlaubte Werte: –promptPflichtQuestion or instruction about the image
Typ: TextStandard:Describe this image in detail.Erlaubte Werte: bis 4 000 Zeichentop_pTyp: ZahlStandard:1Erlaubte Werte: 0 bis 1max_tokensTyp: GanzzahlStandard:512Erlaubte Werte: 1 bis 1 024temperatureTyp: ZahlStandard:0.2Erlaubte Werte: 0 bis 2
Schlagwörter
- replicate
- llava
- captioning
- vqa
- vision-understanding
- open-weights
- image
Häufige Fragen
Was ist LLaVA 1.6 Vicuna 13B?
LLaVA 1.6 Vicuna 13B ist ein Modell von Community aus der Kategorie Multimodal.
Was kostet LLaVA 1.6 Vicuna 13B bei Railwail?
Über Railwail kostet LLaVA 1.6 Vicuna 13B ca. $ 0,1021 pro Lauf. Abgerechnet wird, was jede Anfrage tatsächlich verbraucht. Bezahlt wird mit vorab gekauften Credits; 1 Credit entspricht $ 0,01.
Wie groß ist das Kontextfenster von LLaVA 1.6 Vicuna 13B?
Das Kontextfenster von LLaVA 1.6 Vicuna 13B umfasst 4 096 Token. Eine Antwort kann bis zu 1 024 Token lang sein.
Wie schnell ist LLaVA 1.6 Vicuna 13B?
Für LLaVA 1.6 Vicuna 13B gibt es bei Railwail noch zu wenige gemessene Läufe, um eine Laufzeit anzugeben. Sie hängt von der Eingabe, den Einstellungen und der Auslastung beim Anbieter ab.
Ist LLaVA 1.6 Vicuna 13B besser als BLIP?
Das hängt von der Aufgabe ab. LLaVA 1.6 Vicuna 13B (Community) und BLIP (Salesforce) sind beide Modelle aus der Kategorie Multimodal. Die Vergleichsseite zeigt Preise und Spezifikationen nebeneinander.
LLaVA 1.6 Vicuna 13B und BLIP vergleichenKann LLaVA 1.6 Vicuna 13B Bilder verarbeiten?
Ja. LLaVA 1.6 Vicuna 13B nimmt neben Text auch Bilder als Eingabe an.
Vergleichbare Modelle
Alle dieser Kategorie- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
Alle Modelle über eine API
Ein API-Schlüssel für alle Modelle auf Railwail. Abgerechnet wird über vorab gekaufte Credits, 1 Credit = $ 0,01.