
LLaVA 1.6 Vicuna 13B
llava-1-6-vicuna-13bLLaVA 1.6 (LLaVA-NeXT) with a Vicuna-13B language backbone. Open vision-language chat model that describes images, answers questions, reads charts and reasons about scenes. Version 1.6 adds higher input resolution and better OCR and reasoning than LLaVA 1.5.
- Prix
- ≈ 0,1021 $US/exécution
- Contexte
- 4 096 tokens
- Max. sortie
- 1 024 tokens
- Entrée → Sortie
- Texte + Image → Texte
- Développeur
- Community
- Mis à jour
- 23 septembre 2026
Playground
Essayer LLaVA 1.6 Vicuna 13B
Entrée et résultat
Cette exécution
environ 0,1021 $US · 10,21 crédits
0,3061 $US (30,61 crédits) sont réservés au démarrage ; le temps GPU réel est facturé.
Pour les comptes sans achat antérieur : les exécutions au-delà de 2 crédits nécessitent un rechargement.
Nouveau par ici ?
10 crédits gratuits (0,10 $US) à l'inscription avec Google
Utilisable 24 heures après l'inscription, jusqu'à 5 exécutions par jour et au maximum 2 crédits par exécution. Les autres méthodes de connexion commencent sans crédits.
Examples
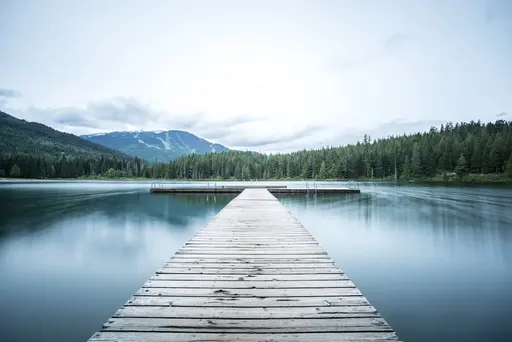 Input
Prompt
What should I take into account when visiting this place?
Response
When visiting a place like the one shown in the image, which appears to be a serene lake with a dock and surrounded by mountains and forests, you should consider the following: 1. **Weather Conditions**: Be prepared for the local weather. It can change rapidly, especially in mountainous areas, so check the forecast and dress in layers. 2. **Safety**: If you plan to go on the water, make sure you have a life jacket and know how to swim. If you're not a strong swimmer, consider wearing a life jacket even if you're just walking along the shore. 3. **Wildlife**: Be aware of the local wildlife and maintain a safe distance. Do not feed the animals, as this can disrupt their natural behavior and diet. 4. **Leave No Trace**: Respect the environment by not littering and by staying on designated paths or trails. 5. **Emergency Preparedness**: Have a first aid kit and know basic first aid. It's also a good idea to have a way to contact emergency services if needed. 6. **Navigation**: If you're going into the woods or on the water, have a map or GPS device and know how to use it. 7. **Hydration and Nutrition**: Bring enough water and food for your visit, especially if you'll be active. 8. **Clothing and Gear**: Wear appropriate clothing for the weather and activities you plan to do. Bring sturdy footwear if you plan to hike or walk on uneven terrain. 9. **Local Regulations**: Follow any posted rules or regulations, which might include fishing regulations, fire restrictions, or…
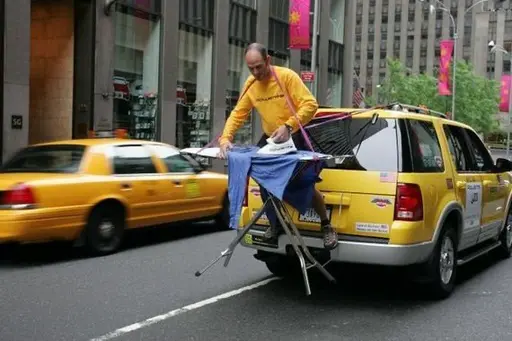 Input
Prompt
What is unusual about this image?
Response
The image shows a person ironing clothes on the back of a moving vehicle, which is an unusual and potentially dangerous activity. Ironing clothes while a vehicle is in motion can be hazardous for the person doing the ironing as well as for other road users. The person is at risk of losing balance and falling off the vehicle, which could result in serious injury. Additionally, the iron could potentially cause a fire or damage to the vehicle or its surroundings if it overheats or malfunctions. This scene is not a safe or typical way to iron clothes and is likely staged for comedic or dramatic effect.
À propos de LLaVA 1.6 Vicuna 13B
LLaVA 1.6 Vicuna 13B est un modèle de Community dans la catégorie Multimodal. Sur Railwail, LLaVA 1.6 Vicuna 13B coûte ≈ 0,1021 $US par exécution. La fenêtre de contexte contient 4 096 tokens, et une réponse peut faire jusqu'à 1 024 tokens.
Tarification
| Exécution typique (≈ 87 s sur L40S) | 0,1021 $US par exécution |
|---|---|
| Temps GPU (L40S) | 0,00117 $US par seconde GPU |
- Facturée selon le temps GPU que l'exécution prend réellement. Au démarrage, 3× le prix typique est réservé de votre solde et régularisé ensuite.
- 1 crédit = 0,01 $US
Calculatrice de coûts
Calculatrice de prix
Typique selon le fournisseur : environ 87,2 s
Total
10,21 $US
1 021 crédits
Par exécution
0,1021 $US · 10,21 crédits
Facturé selon le temps GPU réel ; ceci est une estimation.
API
Aucun exemple API vérifié
L'API publique transmet un format d'entrée différent de celui dont ce modèle a besoin. Utilisez le playground ci-dessus.
Spécifications
- ID du modèle
llava-1-6-vicuna-13b- Développeur
- Community
- Catégorie
- Multimodal
- Entrée
- Texte, Image
- Sortie
- Texte
- Fenêtre de contexte
- 4 096 tokens
- Sortie max.
- 1 024 tokens
- Facturation
- À l'usage (tokens ou temps GPU)
- Entrée du catalogue mise à jour
- 23 septembre 2026
Paramètres d'entrée
Entrées et paramètres du schéma d'entrée du modèle. L'exemple dans la section API montre lesquels l'API accepte.
imageObligatoireImage to analyze
Type: TextePar défaut: –Valeurs autorisées: –promptObligatoireQuestion or instruction about the image
Type: TextePar défaut:Describe this image in detail.Valeurs autorisées: Jusqu'à 4 000 caractèrestop_pType: NombrePar défaut:1Valeurs autorisées: 0 à 1max_tokensType: Nombre entierPar défaut:512Valeurs autorisées: 1 à 1 024temperatureType: NombrePar défaut:0.2Valeurs autorisées: 0 à 2
Étiquettes
- replicate
- llava
- captioning
- vqa
- vision-understanding
- open-weights
- image
Questions fréquemment posées
Qu'est-ce que LLaVA 1.6 Vicuna 13B ?
LLaVA 1.6 Vicuna 13B est un modèle de Community dans la catégorie Multimodal.
Combien coûte LLaVA 1.6 Vicuna 13B sur Railwail ?
Sur Railwail, LLaVA 1.6 Vicuna 13B coûte ≈ 0,1021 $US par exécution. Vous êtes facturé pour ce que chaque requête utilise réellement. L'utilisation est payée à partir de crédits prépayés ; 1 crédit équivaut à 0,01 $US.
Quelle est la fenêtre de contexte de LLaVA 1.6 Vicuna 13B ?
La fenêtre de contexte de LLaVA 1.6 Vicuna 13B contient 4 096 tokens. Une réponse peut faire jusqu'à 1 024 tokens.
Quelle est la vitesse de LLaVA 1.6 Vicuna 13B ?
Il n'y a pas encore assez d'exécutions mesurées de LLaVA 1.6 Vicuna 13B sur Railwail pour indiquer un temps d'exécution. Cela dépend de l'entrée, des paramètres et de la charge chez le fournisseur.
LLaVA 1.6 Vicuna 13B est-il meilleur que BLIP ?
Cela dépend de la tâche. LLaVA 1.6 Vicuna 13B (Community) et BLIP (Salesforce) sont tous deux des modèles de la catégorie Multimodal. La page de comparaison affiche leurs prix et spécifications côte à côte.
Comparer LLaVA 1.6 Vicuna 13B et BLIPLLaVA 1.6 Vicuna 13B peut-il traiter des images ?
Oui. LLaVA 1.6 Vicuna 13B accepte les images en entrée en plus du texte.
Modèles comparables
Tous dans cette catégorie- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
Tous les modèles via une API
Une clé API pour tous les modèles sur Railwail. L'utilisation est facturée à partir de crédits prépayés, 1 crédit = 0,01 $US.