Pour les comptes sans achat antérieur : les exécutions au-delà de 2 crédits nécessitent un rechargement.
Nouveau par ici ?
10 crédits gratuits (0,10 $US) à l'inscription avec Google
Utilisable 24 heures après l'inscription, jusqu'à 5 exécutions par jour et au maximum 2 crédits par exécution. Les autres méthodes de connexion commencent sans crédits.
02
Examples
Real outputs from the public examples of this model on Replicate, with the prompt and settings that produced them. They were not generated live on this page.
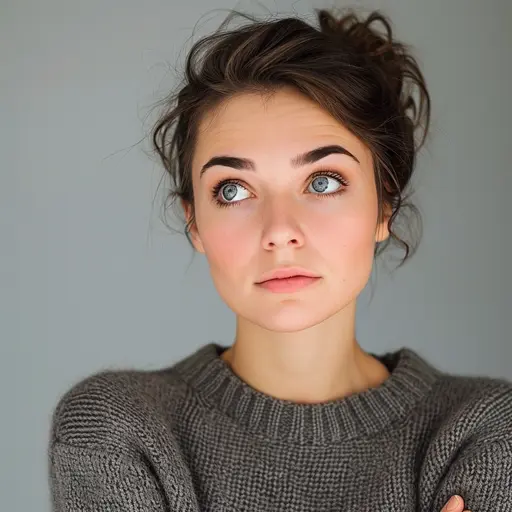
Input
Prompt
the woman is giving an interview for a podcast, wearing a pink top with the logo, it also neatly says "Veo 3.1", she is in a midcentury modern studio with pink lighting, she talks about using Veo 3.1 with reference images to put things into videos you're making, the logo is also in a framed picture against black behind her
Durée : 0:08
Settings
aspect_ratio
16:9
resolution
1080p
duration
8
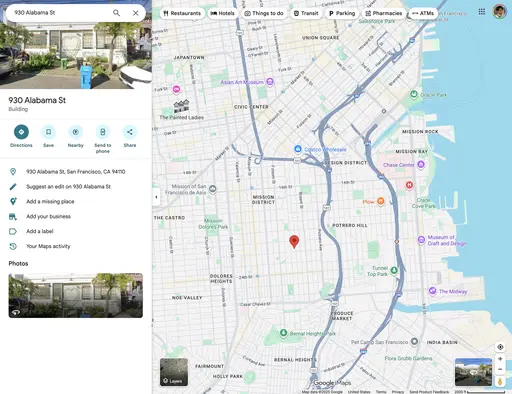
Input
Prompt
show what happens in this location
Durée : 0:08
Settings
aspect_ratio
16:9
resolution
1080p
duration
8
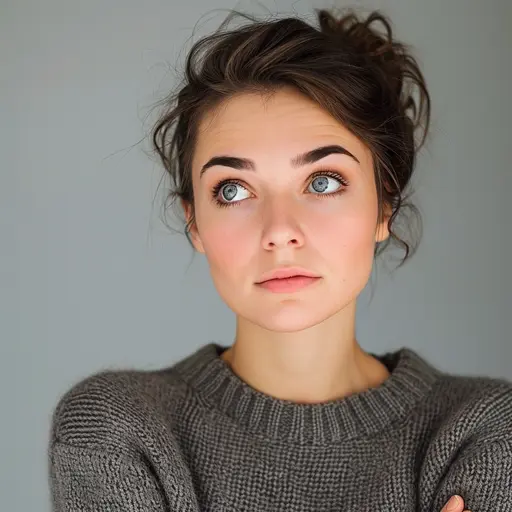
Input
Prompt
the woman are having a conversation in a coffee shop, with the logo in the background. They talk about using Veo 3.1 with reference images to put things into videos
Durée : 0:08
Settings
aspect_ratio
16:9
resolution
720p
duration
8
Prompts d'exemple
Exemples du catalogue Railwail. Ils n'ont pas été générés en direct sur cette page.
Aerial
Durée : 0:08
Sweeping aerial view of coastal city at golden hour
03
À propos de Google Veo 3.1
RésuméAu 23 septembre 2026
Google Veo 3.1 est un modèle de Google DeepMind dans la catégorie Génération de vidéos. Sur Railwail, Google Veo 3.1 coûte 0,48 $US par seconde de vidéo. Selon les paramètres, le prix varie de 0,24 $US/s à 0,48 $US/s. Une exécution standard de 4 secondes coûte 1,92 $US. Formats d'image supportés : 16:9 et 9:16. Durées possibles : 4, 6 ou 8 s.
Arrière-plan
À propos de Google DeepMind
Fondée 2010 · London, United Kingdom
Google DeepMind, formed in 2023 from the merger of Google Brain and DeepMind under Demis Hassabis, runs the Veo video-generation programme. After the headline launch of Veo 3 (May 2025, Google I/O) with native audio, the team shipped Veo 3.1 in late 2025 as an incremental quality and capability upgrade. Veo 3.1 improves prompt adherence, motion physics, character consistency across extended sequences and audio fidelity (including richer ambient soundscapes and more controllable dialogue). The model is exposed via Vertex AI, the Gemini API, Google Labs (VideoFX, Whisk) and the Flow filmmaking surface aimed at professional creators.
Latent video diffusion / DiT with joint audio-video diffusion and reference-frame conditioning
Veo 3.1 retains the joint audio-video diffusion architecture introduced in Veo 3: video is encoded into a spatio-temporal latent space via a 3D causal VAE and denoised by a transformer-based diffusion model, while a coupled audio diffusion module generates synchronized music, ambient sound and dialogue. Improvements in 3.1 are reported across motion physics (water, fabric, crowds), audio quality and the ability to stay consistent across extended sequences via reference-frame and subject-reference conditioning. Native clips run up to 8 seconds at 1080p with extensions for longer sequences and a separate cascaded super-resolution stage for 4K. Text conditioning uses Gemini-family encoders; image and reference-frame conditioning add identity and layout control. Training expands on the Veo 3 corpus with additional curated multilingual audio-video data and refined recaptioning.
Paramètres
Undisclosed
Capacités
All Veo 3 features plus improved physics, audio fidelity and consistency
Up to 8-second 1080p clips natively, 4K via cascaded super-resolution
Reference-frame and subject-reference conditioning
Joint audio-video diffusion with music, ambient sound and dialogue lip-sync
Rich cinematographic prompt vocabulary
Multilingual prompts via Gemini text encoders
Available via Vertex AI, Gemini API, VideoFX, Whisk and Flow
SynthID audio + visual watermarking
Best for: high-end commercial creative, longer sequences, branded campaigns with sound.
Entraînement et licence
Expanded curated multilingual audio-video corpus including licensed footage, public web video (including YouTube under Google's terms) and synthetic data, with multi-granularity captions from Gemini vision-language models.
Licence: Proprietary commercial licence via Google Cloud / Vertex AI and Gemini API; commercial use under Google's generative-AI terms; mandatory SynthID watermarking.
Tests de sécurité: Google Responsible AI framework with safety filters, public-figure filters, child-safety classifiers and provenance via SynthID; ongoing red-team programme.
Limitations connues
8-second native clip limit
Audio short-form and English-leaning
Strict moderation on people, brands and political content
Closed model with no peer-reviewed paper
Per-clip cost higher than Veo 3 Fast or Veo 3.1 Fast tiers
curl https://railwail.com/api/v1/videos/generations \
  -H "Authorization: Bearer $RAILWAIL_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "veo-3-1",
    "prompt": "A slow drone shot over a misty pine forest at sunrise"
  }'

# Response: {"job_id": "...", "status": "queued", ...}
# Poll until status is completed, failed or cancelled:
curl https://railwail.com/api/v1/jobs/JOB_ID \
  -H "Authorization: Bearer $RAILWAIL_API_KEY"
import os
import time
import requests

API = "https://railwail.com/api/v1"
headers = {"Authorization": f"Bearer {os.environ['RAILWAIL_API_KEY']}"}

job = requests.post(
    f"{API}/videos/generations",
    headers=headers,
    json={
        "model": "veo-3-1",
        "prompt": "A slow drone shot over a misty pine forest at sunrise",
    },
).json()

while True:
    status = requests.get(f"{API}/jobs/{job['job_id']}", headers=headers).json()
    if status["status"] in ("completed", "failed", "cancelled"):
        break
    time.sleep(5)

print(status["status"], status.get("output_url"))
const API = "https://railwail.com/api/v1";
const headers = {
  Authorization: `Bearer ${process.env.RAILWAIL_API_KEY}`,
  "Content-Type": "application/json",
};

const job = await fetch(`${API}/videos/generations`, {
  method: "POST",
  headers,
  body: JSON.stringify({
    model: "veo-3-1",
    prompt: "A slow drone shot over a misty pine forest at sunrise"
  }),
}).then((r) => r.json());

let status;
do {
  await new Promise((r) => setTimeout(r, 5000));
  status = await fetch(`${API}/jobs/${job.job_id}`, { headers }).then((r) => r.json());
} while (!["completed", "failed", "cancelled"].includes(status.status));

console.log(status.status, status.output_url);
Les vidéos s'exécutent de manière asynchrone : le premier appel retourne un job_id ; interrogez /api/v1/jobs/JOB_ID jusqu'à ce que le statut soit completed.
Proprietary commercial licence via Google Cloud / Vertex AI and Gemini API; commercial use under Google's generative-AI terms; mandatory SynthID watermarking.
Entrée du catalogue mise à jour
23 septembre 2026
Paramètres d'entrée
Entrées et paramètres du schéma d'entrée du modèle. L'exemple dans la section API montre lesquels l'API accepte.
Google Veo 3.1 est un modèle de Google DeepMind dans la catégorie Génération de vidéos. Sur Railwail, vous pouvez l'appeler avec une clé API via l'API Railwail.
Combien coûte Google Veo 3.1 sur Railwail ?
Sur Railwail, Google Veo 3.1 coûte 0,48 $US par seconde de vidéo. Selon les paramètres, le prix varie de 0,24 $US/s à 0,48 $US/s. Une exécution standard de 4 secondes coûte 1,92 $US. Le prix est connu avant le démarrage de l'exécution. L'utilisation est payée à partir de crédits prépayés ; 1 crédit équivaut à 0,01 $US.
Quels paramètres Google Veo 3.1 supporte-t-il ?
Selon son schéma d'entrée, Google Veo 3.1 connaît ces paramètres : prompt, duration (4, 6 ou 8), start_image et aspect_ratio (16:9 ou 9:16).
Quelle est la vitesse de Google Veo 3.1 ?
Il n'y a pas encore assez d'exécutions mesurées de Google Veo 3.1 sur Railwail pour indiquer un temps d'exécution. Cela dépend de l'entrée, des paramètres et de la charge chez le fournisseur.
Google Veo 3.1 est-il meilleur que HunyuanVideo ?
Cela dépend de la tâche. Google Veo 3.1 (Google DeepMind) et HunyuanVideo (Tencent) sont tous deux des modèles de la catégorie Génération de vidéos. La page de comparaison affiche leurs prix et spécifications côte à côte.
Google Veo 3.1 peut-il utiliser une image comme modèle ?
Oui. Envoyez l'image dans le paramètre start_image.
Comment utiliser Google Veo 3.1 via l'API ?
Créez une clé API Railwail et envoyez votre requête avec l'ID de modèle veo-3-1. Des exemples de code pour curl, Python et JavaScript se trouvent dans la section API de cette page.
Kuaishou's Kling v2.1, generating 5 and 10 second videos at 720p or 1080p from text or an image. Known for cinematic camera work and realistic physical motion, available on Replicate via the official KwaiVGI account.