
Llama 3.2 Vision 11B (Ollama)
llama-3-2-vision-11b-ollamaMeta Llama 3.2 11B Vision served via Ollama on Replicate. Open-weights multimodal model for image captioning, document and chart reading, and visual question answering.
- Preis
- ca. 0,0039 $/Lauf
- Eingabe → Ausgabe
- Text + Bild → Text
- Entwickler
- Community
- Aktualisiert
- 23. September 2026
Playground
Llama 3.2 Vision 11B (Ollama) ausprobieren
Eingabe & Ergebnis
Dieser Lauf
ca. 0,0039 $ · 0,39 Credits
Beim Start werden 0,0116 $ (1,16 Credits) vorgemerkt, abgerechnet wird die tatsächliche GPU-Zeit.
Neu hier?
10 Gratis-Credits (0,10 $) bei Anmeldung mit Google
Nutzbar 24 Stunden nach der Anmeldung, bis zu 5 Läufe pro Tag und höchstens 2 Credits je Lauf. Andere Anmeldearten starten ohne Guthaben. Reicht für 8 Läufe dieses Modells.
Beispiele
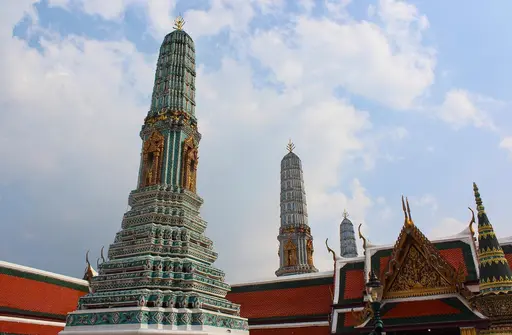 Eingabe
Prompt
Where to find this monument? Can you give me other recommendations around the area?
Antwort
**Wat Phra Kaew (Temple of the Emerald Buddha)** in Bangkok, Thailand. Located within the Grand Palace complex, Wat Phra Kaew is a highly revered and sacred site that houses the iconic Emerald Buddha image. The temple's design incorporates traditional Thai architecture with intricate details and ornate decorations, featuring an imposing spire topped by a golden finial adorned with images of mythical creatures. **Recommendations for Your Visit:** * **Grand Palace**: Explore the sprawling palace grounds, which include several other notable temples and buildings. * **Wat Arun (Temple of Dawn)**: A nearby temple famous for its distinctive spire covered in colorful ceramics and glints of gold. * **Chao Phraya River Cruise**: Take a boat ride along the river to admire the city's skyline and learn about its history. * **Jim Thompson House Museum**: Visit this museum dedicated to Thai art and culture, featuring traditional architecture and beautiful gardens. Wat Phra Kaew is an absolute must-visit attraction when in Bangkok. With these recommendations, you'll have a well-rounded experience of the city's rich cultural heritage.
 Eingabe
Prompt
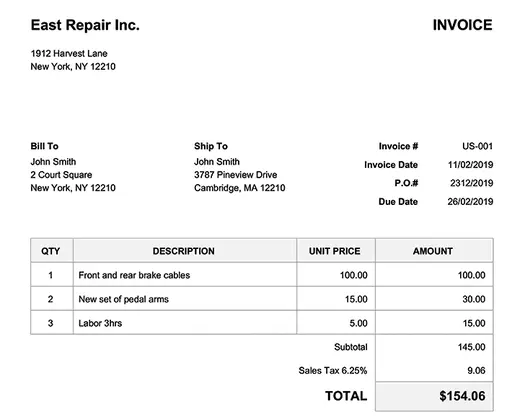
How long does it take from invoice date to due date? Be short and concise.
Antwort
From the invoice date of 11/02/2019 to the due date of 26/02/2019, there is a difference of **15 days**. This calculation was performed by subtracting the invoice date from the due date: 26/02/2019 - 11/02/2019 = 15
 Eingabe
Prompt
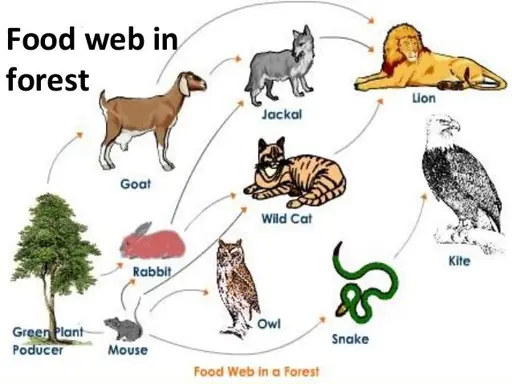
What happens when you take out white cat from this chain?
Antwort
The white cat is not present in the food web. The correct term for a wild animal would be "wildcat." If we were to remove a wildcat from the ecosystem, it would no longer be able to hunt or prey on other animals. This could have cascading effects throughout the entire ecosystem. *Answer*: Wildcat will lose its source of food and nutrients
Über Llama 3.2 Vision 11B (Ollama)
Llama 3.2 Vision 11B (Ollama) ist ein Modell von Community aus der Kategorie Multimodal. Über Railwail kostet Llama 3.2 Vision 11B (Ollama) ca. 0,0039 $ pro Lauf.
Preise
| Typischer Lauf (ca. 3 s auf L40S) | 0,0039 $ pro Lauf |
|---|---|
| GPU-Zeit (L40S) | 0,00117 $ pro GPU-Sekunde |
- Abgerechnet wird die GPU-Zeit, die der Lauf tatsächlich braucht. Beim Start wird das 3-Fache des typischen Preises vom Guthaben vorgemerkt und danach verrechnet.
- 1 Credit = 0,01 $
Kostenrechner
Preisrechner
Typisch laut Anbieter: ca. 3,3 s
Gesamt
0,39 $
39 Credits
Je Lauf
0,0039 $ · 0,39 Credits
Abgerechnet wird die tatsächliche GPU-Zeit; der Wert ist eine Schätzung.
API
Kein geprüftes API-Beispiel
Die öffentliche API übergibt ein anderes Eingabeformat, als dieses Modell braucht. Nutze den Playground oben.
Spezifikationen
- Modell-ID
llama-3-2-vision-11b-ollama- Entwickler
- Community
- Kategorie
- Multimodal
- Eingabe
- Text, Bild
- Ausgabe
- Text
- Abrechnung
- Nach Verbrauch (Token bzw. GPU-Zeit)
- Katalogeintrag aktualisiert
- 23. September 2026
Eingabeparameter
Eingaben und Einstellungen laut Eingabeschema des Modells. Welche davon die API annimmt, zeigt das Beispiel im Abschnitt API.
promptPflichtQuestion about the image
Typ: TextStandard: –Erlaubte Werte: bis 16.000 Zeichenimage_urlImage URL to analyze
Typ: TextStandard: –Erlaubte Werte: –max_tokensTyp: GanzzahlStandard:1024Erlaubte Werte: 1 bis 4.096temperatureTyp: ZahlStandard:0.7Erlaubte Werte: 0 bis 2
Schlagwörter
- replicate
- meta
- llama
- vision-understanding
- open-weights
- ollama
Häufige Fragen
Was ist Llama 3.2 Vision 11B (Ollama)?
Llama 3.2 Vision 11B (Ollama) ist ein Modell von Community aus der Kategorie Multimodal.
Was kostet Llama 3.2 Vision 11B (Ollama) bei Railwail?
Über Railwail kostet Llama 3.2 Vision 11B (Ollama) ca. 0,0039 $ pro Lauf. Abgerechnet wird, was jede Anfrage tatsächlich verbraucht. Bezahlt wird mit vorab gekauften Credits; 1 Credit entspricht 0,01 $.
Welche Einstellungen unterstützt Llama 3.2 Vision 11B (Ollama)?
Laut Eingabeschema kennt Llama 3.2 Vision 11B (Ollama) diese Parameter: prompt (bis 16.000 Zeichen), image_url, max_tokens (1 bis 4.096) und temperature (0 bis 2).
Wie schnell ist Llama 3.2 Vision 11B (Ollama)?
Für Llama 3.2 Vision 11B (Ollama) gibt es bei Railwail noch zu wenige gemessene Läufe, um eine Laufzeit anzugeben. Sie hängt von der Eingabe, den Einstellungen und der Auslastung beim Anbieter ab.
Ist Llama 3.2 Vision 11B (Ollama) besser als BLIP?
Das hängt von der Aufgabe ab. Llama 3.2 Vision 11B (Ollama) (Community) und BLIP (Salesforce) sind beide Modelle aus der Kategorie Multimodal. Die Vergleichsseite zeigt Preise und Spezifikationen nebeneinander.
Llama 3.2 Vision 11B (Ollama) und BLIP vergleichenKann Llama 3.2 Vision 11B (Ollama) Bilder verarbeiten?
Ja. Llama 3.2 Vision 11B (Ollama) nimmt neben Text auch Bilder als Eingabe an.
Vergleichbare Modelle
Alle dieser Kategorie- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
ca. 0,0457 $/Lauf
1.072 % teurer je Einheit
Llama 3.2 Vision 11B (Ollama) und CLIP Interrogator vergleichen - Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
ca. 0,0050 $/Lauf
28 % teurer je Einheit
Llama 3.2 Vision 11B (Ollama) und Depth Anything v2 vergleichen
Alle Modelle über eine API
Ein API-Schlüssel für alle Modelle auf Railwail. Abgerechnet wird über vorab gekaufte Credits, 1 Credit = 0,01 $.