
Florence-2 Segmentation
florence-2-segmentationMicrosoft Florence-2 unified vision model with referring expression segmentation. Text-prompted region and mask generation in one model.
- Pris
- ≈ 0,0012 US$/kørsel
- Input → output
- Tekst + Billede → Tekst
- Udvikler
- Community
- Opdateret
- 23. september 2026
Playground
Prøv Florence-2 Segmentation
Ingen inputmaske
Ingen inputmaske til denne model endnu
Dens inputs er endnu ikke dokumenteret. For at ingen kørsel mislykkes på grund af forkert input tilbyder vi ikke en formular her. Vælg i stedet en sammenlignelig model.
Examples
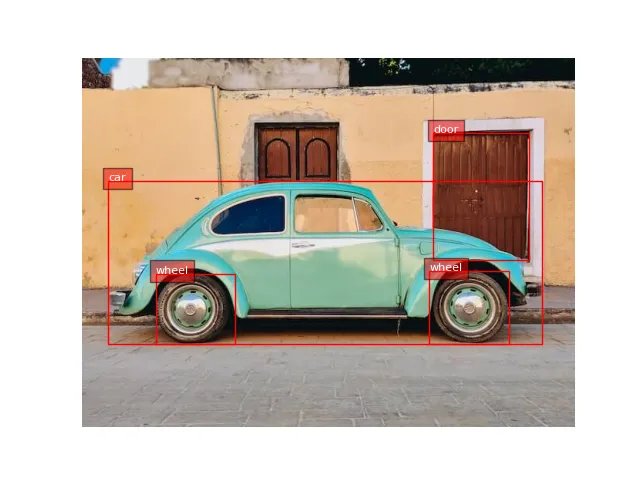 Open full size
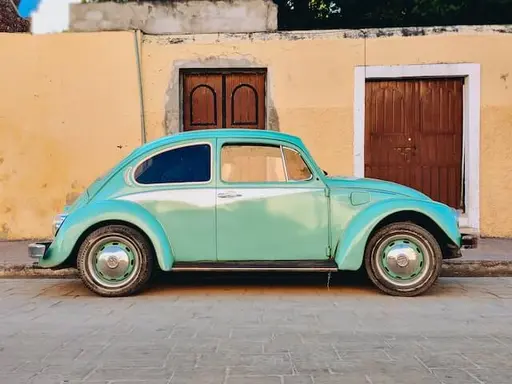 Input
No text prompt: the model only takes the input shown.
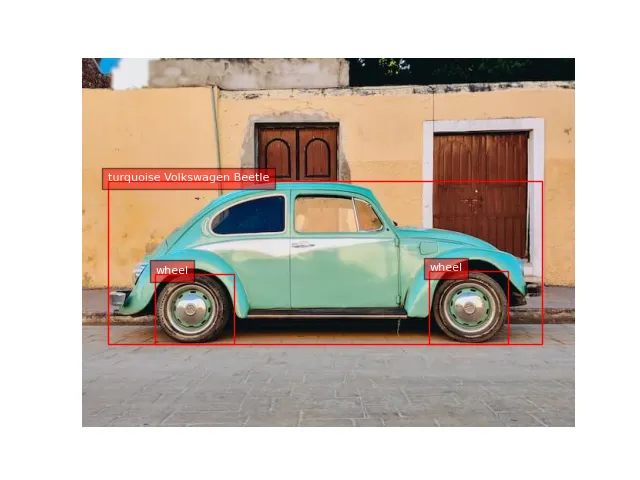 Open full size
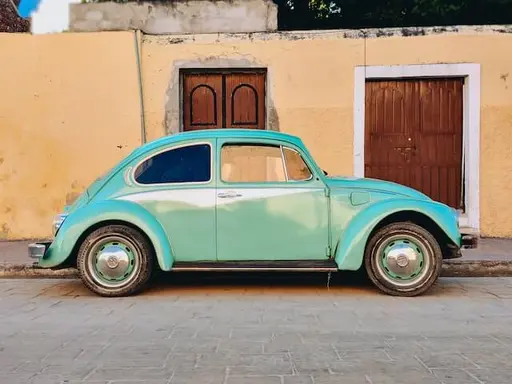 Input
No text prompt: the model only takes the input shown.
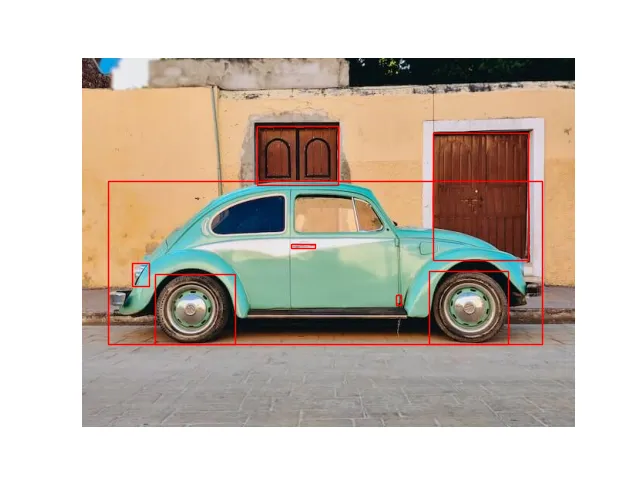 Open full size
 Input
No text prompt: the model only takes the input shown.
Om Florence-2 Segmentation
Florence-2 Segmentation er en model af Community i kategorien Multimodal. På Railwail koster Florence-2 Segmentation ≈ 0,0012 US$ pr. kørsel.
Priser
| Typisk kørsel (≈ 1 s på L40S) | 0,0012 US$ pr. kørsel |
|---|---|
| GPU-tid (L40S) | 0,00117 US$ pr. GPU-sekund |
- Faktureres efter den GPU-tid, som kørslen faktisk tager. Når kørslen starter, reserveres 3× den typiske pris fra din saldo og afregnes efterfølgende.
- 1 kredit = 0,01 US$
Omkostningsberegner
Prisberegner
Typisk ifølge udbyderen: ca. 1 s
I alt
0,12 US$
12 credits
Pr. kørsel
0,0012 US$ · 0,12 credits
Fakturering efter faktisk GPU-tid; dette er et estimat.
API
Intet bekræftet API-eksempel
Den offentlige API sender et andet inputformat end det, som denne model har brug for. Brug playground ovenfor.
Specifikationer
- Model-ID
florence-2-segmentation- Udvikler
- Community
- Kategori
- Multimodal
- Input
- Tekst, Billede
- Output
- Tekst
- Fakturering
- Efter forbrug (tokens eller GPU-tid)
- Katalogelement opdateret
- 23. september 2026
Tags
- replicate
- segmentation
- vision-understanding
- microsoft
- open-weights
Ofte stillede spørgsmål
Hvad er Florence-2 Segmentation?
Florence-2 Segmentation er en model fra Community i kategorien Multimodal.
Hvad koster Florence-2 Segmentation på Railwail?
På Railwail koster Florence-2 Segmentation ≈ 0,0012 US$ pr. kørsel. Du betaler for det, som hver anmodning faktisk bruger. Forbrug betales fra forudbetalte credits; 1 credit svarer til 0,01 US$.
Hvor hurtig er Florence-2 Segmentation?
Der er endnu ikke nok målte kørsler af Florence-2 Segmentation på Railwail til at angive en udførelsestid. Det afhænger af inputtet, indstillingerne og belastningen hos provideren.
Er Florence-2 Segmentation bedre end BLIP?
Det afhænger af opgaven. Florence-2 Segmentation (Community) og BLIP (Salesforce) er begge modeller i kategorien Multimodal. Sammenligningssiden viser deres priser og specifikationer side om side.
Sammenlign Florence-2 Segmentation og BLIPKan Florence-2 Segmentation behandle billeder?
Ja. Florence-2 Segmentation accepterer billeder som input ud over tekst.
Sammenlignelige modeller
Alle i denne kategori- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
Alle modeller via én API
En API-nøgle til alle modeller på Railwail. Forbrug debiteres fra forudbetalte credits, 1 credit = 0,01 US$.