
LLaVA 1.6 Vicuna 13B
llava-1-6-vicuna-13bLLaVA 1.6 (LLaVA-NeXT) with a Vicuna-13B language backbone. Open vision-language chat model that describes images, answers questions, reads charts and reasons about scenes. Version 1.6 adds higher input resolution and better OCR and reasoning than LLaVA 1.5.
- Pris
- ≈ 0,1021 US$/kørsel
- Kontekst
- 4.096 tokens
- Maks. output
- 1.024 tokens
- Input → output
- Tekst + Billede → Tekst
- Udvikler
- Community
- Opdateret
- 23. september 2026
Playground
Prøv LLaVA 1.6 Vicuna 13B
Input & resultat
Denne kørsel
ca. 0,1021 US$ · 10,21 credits
0,3061 US$ (30,61 credits) reserveres ved start; den faktiske GPU-tid faktureres.
For konti uden tidligere køb: kørsler over 2 credits kræver en opladning.
Ny her?
10 gratis credits (0,10 US$) når du tilmelder dig med Google
Kan bruges 24 timer efter tilmelding, op til 5 kørsler pr. dag og højst 2 credits pr. kørsel. Andre login-metoder starter uden credits.
Examples
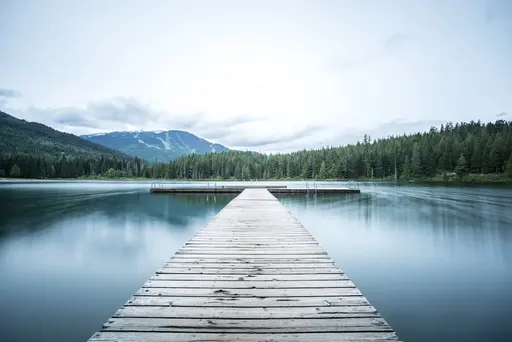 Input
Prompt
What should I take into account when visiting this place?
Response
When visiting a place like the one shown in the image, which appears to be a serene lake with a dock and surrounded by mountains and forests, you should consider the following: 1. **Weather Conditions**: Be prepared for the local weather. It can change rapidly, especially in mountainous areas, so check the forecast and dress in layers. 2. **Safety**: If you plan to go on the water, make sure you have a life jacket and know how to swim. If you're not a strong swimmer, consider wearing a life jacket even if you're just walking along the shore. 3. **Wildlife**: Be aware of the local wildlife and maintain a safe distance. Do not feed the animals, as this can disrupt their natural behavior and diet. 4. **Leave No Trace**: Respect the environment by not littering and by staying on designated paths or trails. 5. **Emergency Preparedness**: Have a first aid kit and know basic first aid. It's also a good idea to have a way to contact emergency services if needed. 6. **Navigation**: If you're going into the woods or on the water, have a map or GPS device and know how to use it. 7. **Hydration and Nutrition**: Bring enough water and food for your visit, especially if you'll be active. 8. **Clothing and Gear**: Wear appropriate clothing for the weather and activities you plan to do. Bring sturdy footwear if you plan to hike or walk on uneven terrain. 9. **Local Regulations**: Follow any posted rules or regulations, which might include fishing regulations, fire restrictions, or…
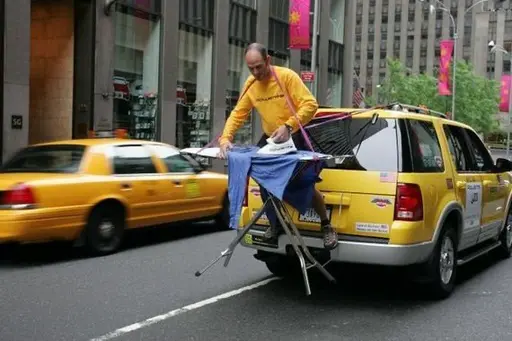 Input
Prompt
What is unusual about this image?
Response
The image shows a person ironing clothes on the back of a moving vehicle, which is an unusual and potentially dangerous activity. Ironing clothes while a vehicle is in motion can be hazardous for the person doing the ironing as well as for other road users. The person is at risk of losing balance and falling off the vehicle, which could result in serious injury. Additionally, the iron could potentially cause a fire or damage to the vehicle or its surroundings if it overheats or malfunctions. This scene is not a safe or typical way to iron clothes and is likely staged for comedic or dramatic effect.
Om LLaVA 1.6 Vicuna 13B
LLaVA 1.6 Vicuna 13B er en model af Community i kategorien Multimodal. På Railwail koster LLaVA 1.6 Vicuna 13B ≈ 0,1021 US$ pr. kørsel. Kontekstvinduet indeholder 4.096 tokens, og et svar kan være op til 1.024 tokens langt.
Priser
| Typisk kørsel (≈ 87 s på L40S) | 0,1021 US$ pr. kørsel |
|---|---|
| GPU-tid (L40S) | 0,00117 US$ pr. GPU-sekund |
- Faktureres efter den GPU-tid, som kørslen faktisk tager. Når kørslen starter, reserveres 3× den typiske pris fra din saldo og afregnes efterfølgende.
- 1 kredit = 0,01 US$
Omkostningsberegner
Prisberegner
Typisk ifølge udbyderen: ca. 87,2 s
I alt
10,21 US$
1.021 credits
Pr. kørsel
0,1021 US$ · 10,21 credits
Fakturering efter faktisk GPU-tid; dette er et estimat.
API
Intet bekræftet API-eksempel
Den offentlige API sender et andet inputformat end det, som denne model har brug for. Brug playground ovenfor.
Specifikationer
- Model-ID
llava-1-6-vicuna-13b- Udvikler
- Community
- Kategori
- Multimodal
- Input
- Tekst, Billede
- Output
- Tekst
- Kontekstvindue
- 4.096 tokens
- Maks. output
- 1.024 tokens
- Fakturering
- Efter forbrug (tokens eller GPU-tid)
- Katalogelement opdateret
- 23. september 2026
Inputparametre
Inputs og indstillinger fra modellens inputskema. Eksemplet i API-afsnittet viser, hvilke af dem API'en accepterer.
imagepåkrævetImage to analyze
Type: TekstStandard: –Tilladte værdier: –promptpåkrævetQuestion or instruction about the image
Type: TekstStandard:Describe this image in detail.Tilladte værdier: op til 4.000 tegntop_pType: TalStandard:1Tilladte værdier: 0 til 1max_tokensType: HeltalStandard:512Tilladte værdier: 1 til 1.024temperatureType: TalStandard:0.2Tilladte værdier: 0 til 2
Tags
- replicate
- llava
- captioning
- vqa
- vision-understanding
- open-weights
- image
Ofte stillede spørgsmål
Hvad er LLaVA 1.6 Vicuna 13B?
LLaVA 1.6 Vicuna 13B er en model fra Community i kategorien Multimodal.
Hvad koster LLaVA 1.6 Vicuna 13B på Railwail?
På Railwail koster LLaVA 1.6 Vicuna 13B ≈ 0,1021 US$ pr. kørsel. Du betaler for det, som hver anmodning faktisk bruger. Forbrug betales fra forudbetalte credits; 1 credit svarer til 0,01 US$.
Hvad er kontekstvinduet for LLaVA 1.6 Vicuna 13B?
Kontekstvinduet for LLaVA 1.6 Vicuna 13B indeholder 4.096 tokens. Et svar kan være op til 1.024 tokens langt.
Hvor hurtig er LLaVA 1.6 Vicuna 13B?
Der er endnu ikke nok målte kørsler af LLaVA 1.6 Vicuna 13B på Railwail til at angive en udførelsestid. Det afhænger af inputtet, indstillingerne og belastningen hos provideren.
Er LLaVA 1.6 Vicuna 13B bedre end BLIP?
Det afhænger af opgaven. LLaVA 1.6 Vicuna 13B (Community) og BLIP (Salesforce) er begge modeller i kategorien Multimodal. Sammenligningssiden viser deres priser og specifikationer side om side.
Sammenlign LLaVA 1.6 Vicuna 13B og BLIPKan LLaVA 1.6 Vicuna 13B behandle billeder?
Ja. LLaVA 1.6 Vicuna 13B accepterer billeder som input ud over tekst.
Sammenlignelige modeller
Alle i denne kategori- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
Alle modeller via én API
En API-nøgle til alle modeller på Railwail. Forbrug debiteres fra forudbetalte credits, 1 credit = 0,01 US$.