
LLaVA 1.6 Vicuna 13B
llava-1-6-vicuna-13bLLaVA 1.6 (LLaVA-NeXT) with a Vicuna-13B language backbone. Open vision-language chat model that describes images, answers questions, reads charts and reasons about scenes. Version 1.6 adds higher input resolution and better OCR and reasoning than LLaVA 1.5.
- السعر
- ≈ 0.1021 US$/تشغيل
- السياق
- 4,096 رمز
- الحد الأقصى للإخراج
- 1,024 رمز
- Input → output
- نص + صورة → نص
- مطور
- Community
- تم التحديث
- ٢٣ سبتمبر ٢٠٢٦
Playground
جرّب LLaVA 1.6 Vicuna 13B
الإدخال والإخراج
هذا التشغيل
حوالي 0.1021 US$ · 10.21 رصيد
يتم حجز 0.3061 US$ (30.61 رصيد) عند البدء؛ يتم فواتير وقت GPU الفعلي.
للحسابات بدون عملية شراء سابقة: التشغيلات التي تتجاوز 2 رصيد تحتاج إلى إعادة تعبئة.
جديد هنا؟
10 رصيد مجاني (0.10 US$) عند التسجيل باستخدام Google
قابل للاستخدام 24 ساعة بعد التسجيل، حتى 5 تشغيل يومياً وبحد أقصى 2 رصيد لكل تشغيل. طرق تسجيل الدخول الأخرى تبدأ بدون رصيد.
Examples
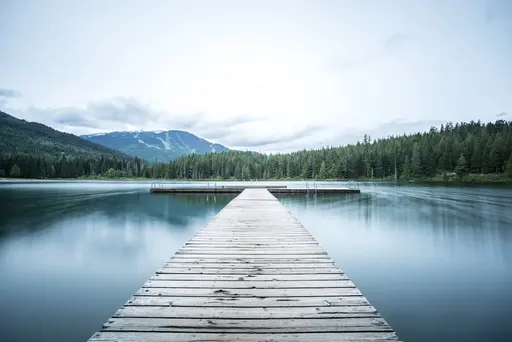 Input
Prompt
What should I take into account when visiting this place?
Response
When visiting a place like the one shown in the image, which appears to be a serene lake with a dock and surrounded by mountains and forests, you should consider the following: 1. **Weather Conditions**: Be prepared for the local weather. It can change rapidly, especially in mountainous areas, so check the forecast and dress in layers. 2. **Safety**: If you plan to go on the water, make sure you have a life jacket and know how to swim. If you're not a strong swimmer, consider wearing a life jacket even if you're just walking along the shore. 3. **Wildlife**: Be aware of the local wildlife and maintain a safe distance. Do not feed the animals, as this can disrupt their natural behavior and diet. 4. **Leave No Trace**: Respect the environment by not littering and by staying on designated paths or trails. 5. **Emergency Preparedness**: Have a first aid kit and know basic first aid. It's also a good idea to have a way to contact emergency services if needed. 6. **Navigation**: If you're going into the woods or on the water, have a map or GPS device and know how to use it. 7. **Hydration and Nutrition**: Bring enough water and food for your visit, especially if you'll be active. 8. **Clothing and Gear**: Wear appropriate clothing for the weather and activities you plan to do. Bring sturdy footwear if you plan to hike or walk on uneven terrain. 9. **Local Regulations**: Follow any posted rules or regulations, which might include fishing regulations, fire restrictions, or…
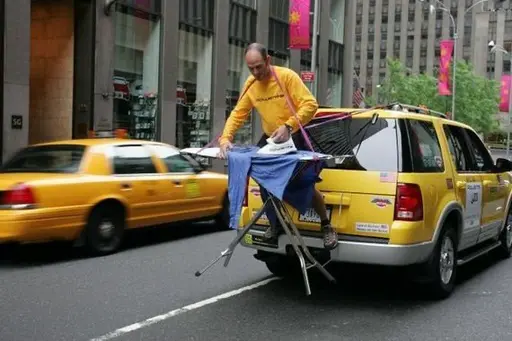 Input
Prompt
What is unusual about this image?
Response
The image shows a person ironing clothes on the back of a moving vehicle, which is an unusual and potentially dangerous activity. Ironing clothes while a vehicle is in motion can be hazardous for the person doing the ironing as well as for other road users. The person is at risk of losing balance and falling off the vehicle, which could result in serious injury. Additionally, the iron could potentially cause a fire or damage to the vehicle or its surroundings if it overheats or malfunctions. This scene is not a safe or typical way to iron clothes and is likely staged for comedic or dramatic effect.
حول LLaVA 1.6 Vicuna 13B
LLaVA 1.6 Vicuna 13B هو نموذج من Community في فئة متعدد الأنماط. على Railwail، يكلف LLaVA 1.6 Vicuna 13B ≈ 0.1021 US$ لكل تشغيل. نافذة السياق تحتوي على 4,096 رموز، والرد الواحد يمكن أن يصل إلى 1,024 رموز.
التسعير
| التشغيل النموذجي (≈ 87 ث على L40S) | 0.1021 US$ لكل تشغيل |
|---|---|
| وقت GPU (L40S) | 0.00117 US$ لكل ثانية GPU |
- يتم الفرز بناءً على وقت GPU الذي يستغرقه التشغيل فعلياً. عند بدء التشغيل، يتم حجز 3× السعر النموذجي من رصيدك ويتم تسويته لاحقاً.
- 1 رصيد = ٠٫٠١ US$
حاسبة التكلفة
حاسبة الأسعار
نموذجي وفقاً للمزود: حوالي 87.2 ث
الإجمالي
10.21 US$
1,021 رصيد
لكل تشغيل
0.1021 US$ · 10.21 رصيد
يتم الفرض بناءً على وقت GPU الفعلي؛ هذا تقدير.
API
لا يوجد مثال API موثق
API العام يمرر صيغة إدخال مختلفة عما يحتاجه هذا النموذج. استخدم ساحة الاختبار أعلاه.
المواصفات
- معرّف النموذج
llava-1-6-vicuna-13b- مطور
- Community
- الفئة
- متعدد الأنماط
- الإدخال
- نص, صورة
- الإخراج
- نص
- نافذة السياق
- 4,096 رمز
- الحد الأقصى للإخراج
- 1,024 رمز
- الفواتير
- حسب الاستخدام (الرموز أو وقت GPU)
- تم تحديث إدخال الكتالوج
- ٢٣ سبتمبر ٢٠٢٦
معاملات الإدخال
المدخلات والإعدادات من مخطط إدخال النموذج. يوضح المثال في قسم API أيها تقبل API.
imageمطلوبImage to analyze
النوع: نصالافتراضي: –القيم المسموحة: –promptمطلوبQuestion or instruction about the image
النوع: نصالافتراضي:Describe this image in detail.القيم المسموحة: حتى 4,000 حرفtop_pالنوع: رقمالافتراضي:1القيم المسموحة: 0 إلى 1max_tokensالنوع: عدد صحيحالافتراضي:512القيم المسموحة: 1 إلى 1,024temperatureالنوع: رقمالافتراضي:0.2القيم المسموحة: 0 إلى 2
الوسوم
- replicate
- llava
- captioning
- vqa
- vision-understanding
- open-weights
- image
الأسئلة الشائعة
ما هو LLaVA 1.6 Vicuna 13B؟
LLaVA 1.6 Vicuna 13B هو نموذج من Community في فئة متعدد الأنماط.
كم تكلفة LLaVA 1.6 Vicuna 13B على Railwail؟
على Railwail، يكلف LLaVA 1.6 Vicuna 13B ≈ 0.1021 US$ لكل تشغيل. يتم فرض رسوم عليك مقابل ما تستخدمه كل طلب فعلياً. الاستخدام يُدفع من أرصدة مدفوعة مقدماً؛ 1 رصيد يساوي ٠٫٠١ US$.
ما حجم نافذة السياق في LLaVA 1.6 Vicuna 13B؟
نافذة السياق في LLaVA 1.6 Vicuna 13B تحتوي على 4,096 رموز. الرد الواحد يمكن أن يصل إلى 1,024 رموز.
ما سرعة LLaVA 1.6 Vicuna 13B؟
لا توجد عمليات تشغيل مقاسة كافية لـ LLaVA 1.6 Vicuna 13B على Railwail حتى الآن لتحديد وقت التشغيل. يعتمد على الإدخال والإعدادات والحمل لدى المزود.
هل LLaVA 1.6 Vicuna 13B أفضل من BLIP؟
هذا يعتمد على المهمة. LLaVA 1.6 Vicuna 13B (Community) و BLIP (Salesforce) كلاهما نموذج في فئة متعدد الأنماط. تعرض صفحة المقارنة أسعارهما والمواصفات جنباً إلى جنب.
قارن LLaVA 1.6 Vicuna 13B و BLIPهل يمكن لـ LLaVA 1.6 Vicuna 13B معالجة الصور؟
نعم. LLaVA 1.6 Vicuna 13B يقبل الصور كإدخال بالإضافة إلى النص.
نماذج قابلة للمقارنة
الكل في هذه الفئة- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
جميع النماذج عبر API واحدة
مفتاح API واحد لكل نموذج على Railwail. يتم احتساب الاستخدام من الأرصدة المدفوعة مقدماً، 1 رصيد = ٠٫٠١ US$.