
LLaVA 1.6 Vicuna 13B
llava-1-6-vicuna-13bLLaVA 1.6 (LLaVA-NeXT) with a Vicuna-13B language backbone. Open vision-language chat model that describes images, answers questions, reads charts and reasons about scenes. Version 1.6 adds higher input resolution and better OCR and reasoning than LLaVA 1.5.
- Hinta
- ≈ 0,1021 $/suoritus
- Konteksti
- 4 096 tokenia
- Enint. tuloste
- 1 024 tokenia
- Syöte → tulos
- Teksti + Kuva → Teksti
- Kehittäjä
- Community
- Päivitetty
- 23. syyskuuta 2026
Leikkikenttä
Kokeile LLaVA 1.6 Vicuna 13B
Syöte ja tulos
Tämä suoritus
noin 0,1021 $ · 10,21 creditiä
Alussa varataan 0,3061 $ (30,61 creditiä); todellinen GPU-aika laskutetaan.
Tileille ilman ostoja: yli 2 creditin suoritukset vaativat latauksen.
Uusi täällä?
10 ilmaista creditiä (0,10 $) kun rekisteröidyt Googlella
Käytettävissä 24 tuntia rekisteröinnin jälkeen, enintään 5 suoritusta päivässä ja enintään 2 creditiä suoritusta kohti. Muut kirjautumismenetelmät alkavat ilman creditejä.
Examples
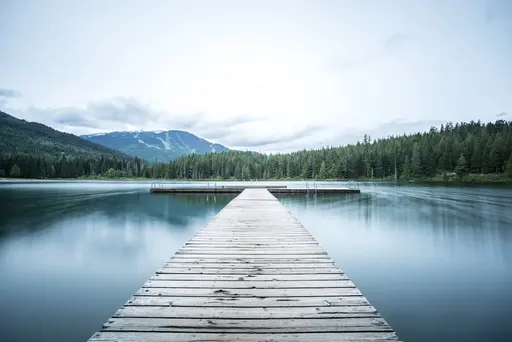 Input
Prompt
What should I take into account when visiting this place?
Response
When visiting a place like the one shown in the image, which appears to be a serene lake with a dock and surrounded by mountains and forests, you should consider the following: 1. **Weather Conditions**: Be prepared for the local weather. It can change rapidly, especially in mountainous areas, so check the forecast and dress in layers. 2. **Safety**: If you plan to go on the water, make sure you have a life jacket and know how to swim. If you're not a strong swimmer, consider wearing a life jacket even if you're just walking along the shore. 3. **Wildlife**: Be aware of the local wildlife and maintain a safe distance. Do not feed the animals, as this can disrupt their natural behavior and diet. 4. **Leave No Trace**: Respect the environment by not littering and by staying on designated paths or trails. 5. **Emergency Preparedness**: Have a first aid kit and know basic first aid. It's also a good idea to have a way to contact emergency services if needed. 6. **Navigation**: If you're going into the woods or on the water, have a map or GPS device and know how to use it. 7. **Hydration and Nutrition**: Bring enough water and food for your visit, especially if you'll be active. 8. **Clothing and Gear**: Wear appropriate clothing for the weather and activities you plan to do. Bring sturdy footwear if you plan to hike or walk on uneven terrain. 9. **Local Regulations**: Follow any posted rules or regulations, which might include fishing regulations, fire restrictions, or…
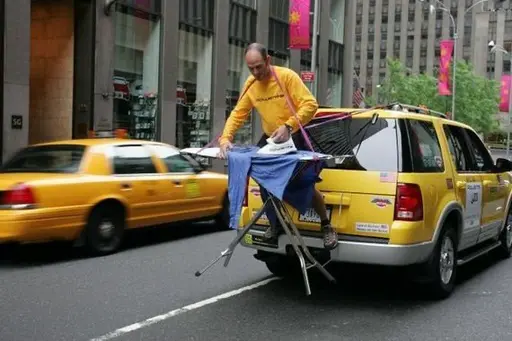 Input
Prompt
What is unusual about this image?
Response
The image shows a person ironing clothes on the back of a moving vehicle, which is an unusual and potentially dangerous activity. Ironing clothes while a vehicle is in motion can be hazardous for the person doing the ironing as well as for other road users. The person is at risk of losing balance and falling off the vehicle, which could result in serious injury. Additionally, the iron could potentially cause a fire or damage to the vehicle or its surroundings if it overheats or malfunctions. This scene is not a safe or typical way to iron clothes and is likely staged for comedic or dramatic effect.
Tietoja: LLaVA 1.6 Vicuna 13B
LLaVA 1.6 Vicuna 13B on Community-kehittäjän malli kategoriasta Multimodaali. Railwailissa LLaVA 1.6 Vicuna 13B maksaa ≈ 0,1021 $ per suoritus. Kontekstiikkuna sisältää 4 096 tokenia, ja vastaus voi olla enintään 1 024 tokenia pitkä.
Hinnat
| Tyypillinen suoritus (≈ 87 s L40S:lla) | 0,1021 $ per suoritus |
|---|---|
| GPU-aika (L40S) | 0,00117 $ per GPU-sekunti |
- Laskutus perustuu suorituksen todelliseen GPU-aikaan. Kun suoritus alkaa, 3-kertainen tyypillinen hinta varataan saldostasi ja selvitetään jälkikäteen.
- 1 krediitti = 0,01 $
Kustannuslaskin
Hintalaskin
Palveluntarjoajan mukaan tyypillinen: noin 87,2 s
Yhteensä
10,21 $
1 021 krediittiä
Suoritusta kohti
0,1021 $ · 10,21 krediittiä
Laskutus perustuu todelliseen GPU-aikaan; tämä on arvio.
API
Ei vahvistettua API-esimerkkiä
Julkinen API välittää eri syötemuotoa kuin tämä malli tarvitsee. Käytä yllä olevaa leikkikenttää.
Tekniset tiedot
- Mallin tunnus
llava-1-6-vicuna-13b- Kehittäjä
- Community
- Kategoria
- Multimodaali
- Syöte
- Teksti, Kuva
- Tuloste
- Teksti
- Konteksti-ikkuna
- 4 096 tokenia
- Enimmäistuloste
- 1 024 tokenia
- Laskutus
- Käytön mukaan (tokeneja tai GPU-aikaa)
- Luettelokirjaus päivitetty
- 23. syyskuuta 2026
Syöteparametrit
Mallin syötökaavion syötteet ja asetukset. API-osion esimerkki näyttää, mitkä niistä API hyväksyy.
imagepakollinenImage to analyze
Tyyppi: TekstiOletus: –Sallitut arvot: –promptpakollinenQuestion or instruction about the image
Tyyppi: TekstiOletus:Describe this image in detail.Sallitut arvot: enintään 4 000 merkkiätop_pTyyppi: LukuOletus:1Sallitut arvot: 0–1max_tokensTyyppi: KokonaislukuOletus:512Sallitut arvot: 1–1 024temperatureTyyppi: LukuOletus:0.2Sallitut arvot: 0–2
Tunnisteet
- replicate
- llava
- captioning
- vqa
- vision-understanding
- open-weights
- image
Usein kysytyt kysymykset
Mikä on LLaVA 1.6 Vicuna 13B?
LLaVA 1.6 Vicuna 13B on Communityn kehittämä malli Multimodaali-kategoriassa.
Paljonko LLaVA 1.6 Vicuna 13B maksaa Railwailissa?
Railwailissa LLaVA 1.6 Vicuna 13B maksaa ≈ 0,1021 $ per suoritus. Sinua veloitetaan siitä, mitä kukin pyyntö todella käyttää. Käyttö maksetaan ennakkoon ostettujen krediittien avulla; 1 krediitti vastaa 0,01 $.
Mikä on LLaVA 1.6 Vicuna 13Bn kontekstiikkuna?
LLaVA 1.6 Vicuna 13Bn kontekstiikkuna sisältää 4 096 tokenia. Vastaus voi olla enintään 1 024 tokenia pitkä.
Kuinka nopea LLaVA 1.6 Vicuna 13B on?
LLaVA 1.6 Vicuna 13Blla ei ole vielä tarpeeksi mitattuja suorituksia Railwailissa suoritusajan ilmoittamiseksi. Se riippuu syötteestä, asetuksista ja palveluntarjoajan kuormituksesta.
Onko LLaVA 1.6 Vicuna 13B parempi kuin BLIP?
Se riippuu tehtävästä. LLaVA 1.6 Vicuna 13B (Community) ja BLIP (Salesforce) ovat molemmat malleja Multimodaali-kategoriassa. Vertailussa näkyvät niiden hinnat ja tekniset tiedot rinnakkain.
Vertaa LLaVA 1.6 Vicuna 13B ja BLIPVoiko LLaVA 1.6 Vicuna 13B käsitellä kuvia?
Kyllä. LLaVA 1.6 Vicuna 13B hyväksyy kuvia syötteenä tekstin lisäksi.
Vertailukelpoiset mallit
Kaikki tässä kategoriassa- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
Kaikki mallit yhden API:n kautta
Yksi API-avain kaikille Railwailin malleille. Käyttö laskutetaan prepaid-krediiteistä, 1 krediitti = 0,01 $.