
LLaVA 1.6 Vicuna 13B
llava-1-6-vicuna-13bLLaVA 1.6 (LLaVA-NeXT) with a Vicuna-13B language backbone. Open vision-language chat model that describes images, answers questions, reads charts and reasons about scenes. Version 1.6 adds higher input resolution and better OCR and reasoning than LLaVA 1.5.
- Τιμή
- ≈ 0,1021 $/εκτέλεση
- Περιεχόμενο
- 4.096 tokens
- Μέγ. έξοδος
- 1.024 tokens
- Είσοδος → Έξοδος
- Κείμενο + Εικόνα → Κείμενο
- Προγραμματιστής
- Community
- Ενημερώθηκε
- 23 Σεπτεμβρίου 2026
Playground
Δοκιμάστε LLaVA 1.6 Vicuna 13B
Είσοδος & Έξοδος
Αυτή η εκτέλεση
περίπου 0,1021 $ · 10,21 πιστωτικές μονάδες
0,3061 $ (30,61 πιστωτικές μονάδες) προεπιλέγονται κατά την έναρξη· ο πραγματικός χρόνος GPU χρεώνεται.
Για λογαριασμούς χωρίς αγορά: εκτελέσεις πάνω από 2 πιστωτικές μονάδες χρειάζονται ανεβάσματος.
Νέος εδώ;
10 δωρεάν πιστωτικές μονάδες (0,10 $) όταν εγγραφείς με Google
Χρησιμοποιήσιμο 24 ώρες μετά την εγγραφή, έως 5 εκτελέσεις ανά ημέρα και το πολύ 2 πιστωτικές μονάδες ανά εκτέλεση. Άλλες μέθοδοι σύνδεσης ξεκινούν χωρίς πιστωτικές μονάδες.
Examples
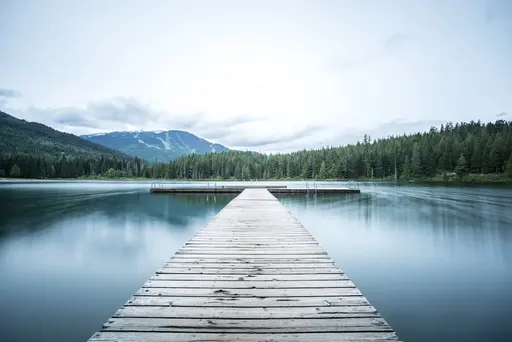 Input
Prompt
What should I take into account when visiting this place?
Response
When visiting a place like the one shown in the image, which appears to be a serene lake with a dock and surrounded by mountains and forests, you should consider the following: 1. **Weather Conditions**: Be prepared for the local weather. It can change rapidly, especially in mountainous areas, so check the forecast and dress in layers. 2. **Safety**: If you plan to go on the water, make sure you have a life jacket and know how to swim. If you're not a strong swimmer, consider wearing a life jacket even if you're just walking along the shore. 3. **Wildlife**: Be aware of the local wildlife and maintain a safe distance. Do not feed the animals, as this can disrupt their natural behavior and diet. 4. **Leave No Trace**: Respect the environment by not littering and by staying on designated paths or trails. 5. **Emergency Preparedness**: Have a first aid kit and know basic first aid. It's also a good idea to have a way to contact emergency services if needed. 6. **Navigation**: If you're going into the woods or on the water, have a map or GPS device and know how to use it. 7. **Hydration and Nutrition**: Bring enough water and food for your visit, especially if you'll be active. 8. **Clothing and Gear**: Wear appropriate clothing for the weather and activities you plan to do. Bring sturdy footwear if you plan to hike or walk on uneven terrain. 9. **Local Regulations**: Follow any posted rules or regulations, which might include fishing regulations, fire restrictions, or…
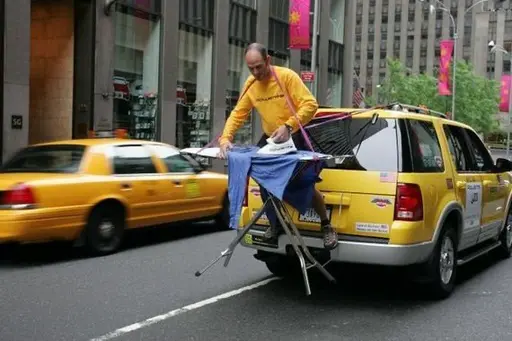 Input
Prompt
What is unusual about this image?
Response
The image shows a person ironing clothes on the back of a moving vehicle, which is an unusual and potentially dangerous activity. Ironing clothes while a vehicle is in motion can be hazardous for the person doing the ironing as well as for other road users. The person is at risk of losing balance and falling off the vehicle, which could result in serious injury. Additionally, the iron could potentially cause a fire or damage to the vehicle or its surroundings if it overheats or malfunctions. This scene is not a safe or typical way to iron clothes and is likely staged for comedic or dramatic effect.
Σχετικά με το LLaVA 1.6 Vicuna 13B
Το LLaVA 1.6 Vicuna 13B είναι ένα μοντέλο του Community στην κατηγορία Multimodal. Στο Railwail, το LLaVA 1.6 Vicuna 13B κοστίζει ≈ 0,1021 $ ανά εκτέλεση. Το παράθυρο περιεχομένου περιέχει 4.096 tokens, και μια απάντηση μπορεί να είναι έως 1.024 tokens.
Τιμολόγηση
| Συνήθης εκτέλεση (≈ 87 s σε L40S) | 0,1021 $ ανά εκτέλεση |
|---|---|
| Χρόνος GPU (L40S) | 0,00117 $ ανά δευτερόλεπτο GPU |
- Χρέωση με βάση τον χρόνο GPU που χρειάζεται πραγματικά η εκτέλεση. Κατά την έναρξη, το 3× της τυπικής τιμής δεσμεύεται από το υπόλοιπό σας και διακανονίζεται αργότερα.
- 1 πιστωτική μονάδα = 0,01 $
Αριθμομηχανή κόστους
Αριθμομηχανή τιμών
Τυπικά σύμφωνα με τον πάροχο: περίπου 87,2 s
Σύνολο
10,21 $
1.021 πιστωτικές μονάδες
Ανά εκτέλεση
0,1021 $ · 10,21 πιστωτικές μονάδες
Χρέωση με βάση τον πραγματικό χρόνο GPU· αυτή είναι μια εκτίμηση.
API
Κανένα επαληθευμένο παράδειγμα API
Το δημόσιο API περνά μια διαφορετική μορφή εισόδου από αυτή που χρειάζεται αυτό το μοντέλο. Χρησιμοποιήστε το playground παραπάνω.
Προδιαγραφές
- ID μοντέλου
llava-1-6-vicuna-13b- Ανάπτυξη
- Community
- Κατηγορία
- Multimodal
- Είσοδος
- Κείμενο, Εικόνα
- Έξοδος
- Κείμενο
- Παράθυρο περιεχομένου
- 4.096 tokens
- Μέγ. έξοδος
- 1.024 tokens
- Χρέωση
- Κατά χρήση (tokens ή χρόνος GPU)
- Καταχώρηση καταλόγου ενημερώθηκε
- 23 Σεπτεμβρίου 2026
Παράμετροι εισόδου
Εισόδους και ρυθμίσεις από το σχήμα εισόδου του μοντέλου. Το παράδειγμα στην ενότητα API δείχνει ποιες από αυτές δέχεται το API.
imageΥποχρεωτικόImage to analyze
Τύπος: ΚείμενοΠροεπιλογή: –Επιτρεπόμενες τιμές: –promptΥποχρεωτικόQuestion or instruction about the image
Τύπος: ΚείμενοΠροεπιλογή:Describe this image in detail.Επιτρεπόμενες τιμές: Έως 4.000 χαρακτήρεςtop_pΤύπος: ΑριθμόςΠροεπιλογή:1Επιτρεπόμενες τιμές: 0 έως 1max_tokensΤύπος: Ακέραιος αριθμόςΠροεπιλογή:512Επιτρεπόμενες τιμές: 1 έως 1.024temperatureΤύπος: ΑριθμόςΠροεπιλογή:0.2Επιτρεπόμενες τιμές: 0 έως 2
Ετικέτες
- replicate
- llava
- captioning
- vqa
- vision-understanding
- open-weights
- image
Συχνές ερωτήσεις
Τι είναι LLaVA 1.6 Vicuna 13B;
Το LLaVA 1.6 Vicuna 13B είναι ένα μοντέλο του Community στην κατηγορία Multimodal.
Πόσο κοστίζει το LLaVA 1.6 Vicuna 13B στο Railwail;
Στο Railwail, το LLaVA 1.6 Vicuna 13B κοστίζει ≈ 0,1021 $ ανά εκτέλεση. Χρεώνεστε για αυτό που χρησιμοποιεί πραγματικά κάθε αίτημα. Η χρήση πληρώνεται από προπληρωμένες πιστωτικές μονάδες· 1 πιστωτική μονάδα ισούται με 0,01 $.
Ποιο είναι το παράθυρο περιεχομένου του LLaVA 1.6 Vicuna 13B;
Το παράθυρο περιεχομένου του LLaVA 1.6 Vicuna 13B περιέχει 4.096 tokens. Μια απάντηση μπορεί να είναι έως 1.024 tokens.
Πόσο γρήγορο είναι το LLaVA 1.6 Vicuna 13B;
Δεν υπάρχουν αρκετές μετρημένες εκτελέσεις του LLaVA 1.6 Vicuna 13B στο Railwail ακόμα για να δηλωθεί ένας χρόνος εκτέλεσης. Εξαρτάται από την είσοδο, τις ρυθμίσεις και το φορτίο στον πάροχο.
Είναι το LLaVA 1.6 Vicuna 13B καλύτερο από το BLIP;
Αυτό εξαρτάται από την εργασία. Το LLaVA 1.6 Vicuna 13B (Community) και το BLIP (Salesforce) είναι και τα δύο μοντέλα στην κατηγορία Multimodal. Η σελίδα σύγκρισης δείχνει τις τιμές και τις προδιαγραφές τους παράλληλα.
Σύγκριση LLaVA 1.6 Vicuna 13B και BLIPΜπορεί το LLaVA 1.6 Vicuna 13B να επεξεργαστεί εικόνες;
Ναι. Το LLaVA 1.6 Vicuna 13B δέχεται εικόνες ως είσοδο εκτός από κείμενο.
Συγκρίσιμα μοντέλα
Όλα σε αυτήν την κατηγορία- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
Όλα τα μοντέλα μέσω ενός API
Ένα κλειδί API για κάθε μοντέλο στο Railwail. Η χρήση χρεώνεται από προπληρωμένα πιστωτικά, 1 πιστωτικό = 0,01 $.