
EasyOCR
easyocrJaidedAI EasyOCR. Simple Python OCR wrapper supporting 80+ languages with deep-learning text detection and recognition.
- Price
- ≈ US$0.0014/run
- Input → output
- Text + Image → Text
- Developer
- Community
- Updated
- 23 September 2026
Playground
Try EasyOCR
No input form
No input form for this model yet
Its inputs are not documented yet. So that no run fails on a wrong input, we don't offer a form here. Pick a comparable model instead.
Examples
 Input
No text prompt: the model only takes the input shown.
Response
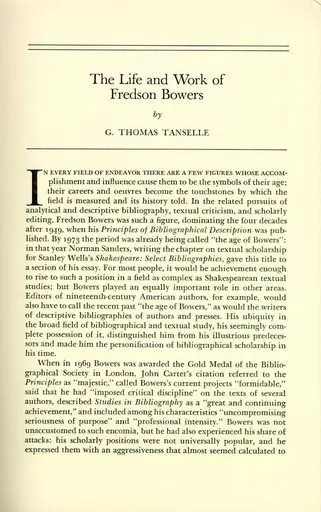
The Life and Work of Fredson Bowers by G. THOMAS TANSELLE N EVERY FIELD OF ENDEAVOR THERE ARE A FEW FIGURES WHOSE AGCOM- plishment and influence cause them to be the symbols of their age; their careers and oeuvres become the touchstones by which the field is measured and its history told. In the related pursuits of analytical and descriptive bibliography, textual criticism, and scholarly editing, Fredson Bowers was such a figure, dominating the four decades after 1949, when his Principles of Bibliographical Description was pub- lished. By 1973 the period was already being called “the age of Bowers”: in that year Norman Sanders, writing the chapter on textual scholarship for Stanley Wells's Shakespeare: Select Bibliographies, gave this title to a section of his essay. For most people, it would be achievement enough to rise to such a position in a field as complex as Shakespearean textual studies; but Bowers played an equally important role in other areas. Editors of nineteenth-century American authors, for example, would also have to call the recent past “the age of Bowers,” as would the writers of descriptive bibliographies of authors and presses. His ubiquity in the broad field of bibliographical and textual study, his seemingly com- plete possession of it, distinguished him from his illustrious predeces- sors and made him the personification of bibliographical scholarship in his time. When in 1969 Bowers was awarded the Gold Medal of the Biblio- graphical Society in Lo…
 Input
No text prompt: the model only takes the input shown.
Response
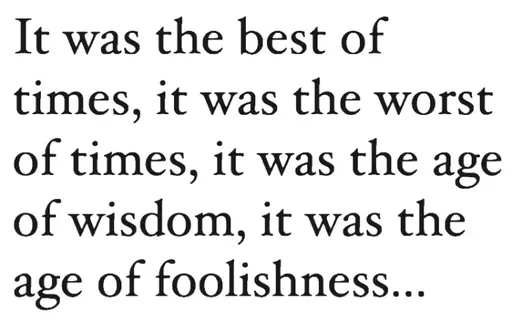
It was the best of times, it was the worst of times, it was the age of wisdom, it was the age of foolishness...
About EasyOCR
EasyOCR is a model by Community in the Multimodal category. On Railwail, EasyOCR costs ≈ US$0.0014 per run.
Pricing
| Typical run (≈ 11 s on CPU) | US$0.0014 per run |
|---|---|
| GPU time (CPU) | US$0.00012 per GPU second |
- Billed by the GPU time the run actually takes. When the run starts, 3× the typical price is reserved from your balance and settled afterwards.
- 1 credit = US$0.01
Cost calculator
Price calculator
Typical according to the provider: about 11 s
Total
US$0.14
14 credits
Per run
US$0.0014 · 0.14 credits
Billed by the actual GPU time; this is an estimate.
API
No verified API example
The public API passes a different input format than this model needs. Use the playground above.
Specifications
- Model ID
easyocr- Developer
- Community
- Category
- Multimodal
- Input
- Text, Image
- Output
- Text
- Billing
- By usage (tokens or GPU time)
- Catalog entry updated
- 23 September 2026
Tags
- replicate
- ocr
- vision-understanding
- multilingual
- open-source
Frequently asked questions
What is EasyOCR?
EasyOCR is a model by Community in the Multimodal category.
How much does EasyOCR cost on Railwail?
On Railwail, EasyOCR costs ≈ US$0.0014 per run. You are charged for what each request actually uses. Usage is paid from prepaid credits; 1 credit equals US$0.01.
How fast is EasyOCR?
There are not enough measured runs of EasyOCR on Railwail yet to state a run time. It depends on the input, the settings and the load at the provider.
Is EasyOCR better than BLIP?
That depends on the task. EasyOCR (Community) and BLIP (Salesforce) are both models in the Multimodal category. The comparison page shows their prices and specifications side by side.
Compare EasyOCR and BLIPCan EasyOCR process images?
Yes. EasyOCR accepts images as input in addition to text.
Comparable models
All in this category- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
All models through one API
One API key for every model on Railwail. Usage is charged from prepaid credits, 1 credit = US$0.01.