
LLaVA 1.6 Vicuna 13B
llava-1-6-vicuna-13bLLaVA 1.6 (LLaVA-NeXT) with a Vicuna-13B language backbone. Open vision-language chat model that describes images, answers questions, reads charts and reasons about scenes. Version 1.6 adds higher input resolution and better OCR and reasoning than LLaVA 1.5.
- Prijs
- ≈ US$ 0,1021/uitvoering
- Context
- 4.096 tokens
- Max. uitvoer
- 1.024 tokens
- Invoer → Uitvoer
- Tekst + Afbeelding → Tekst
- Ontwikkelaar
- Community
- Bijgewerkt
- 23 september 2026
Playground
LLaVA 1.6 Vicuna 13B proberen
Invoer & resultaat
Deze uitvoering
ongeveer US$ 0,1021 · 10,21 credits
US$ 0,3061 (30,61 credits) worden gereserveerd bij het starten; de werkelijke GPU-tijd wordt gefactureerd.
Voor accounts zonder aankoop: uitvoeringen boven 2 credits hebben een opwaardering nodig.
Nieuw hier?
10 gratis credits (US$ 0,10) wanneer je je aanmeldt met Google
Bruikbaar 24 uur na aanmelding, tot 5 uitvoeringen per dag en maximaal 2 credits per uitvoering. Andere aanmeldmethoden starten zonder credits.
Examples
 Input
Prompt
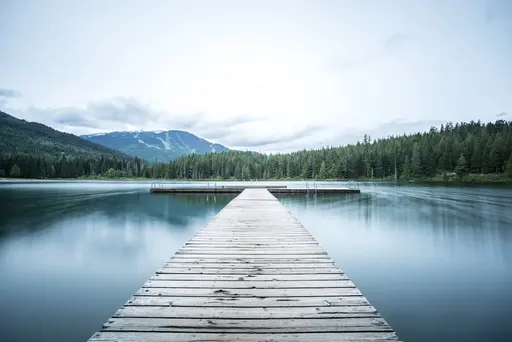
What should I take into account when visiting this place?
Response
When visiting a place like the one shown in the image, which appears to be a serene lake with a dock and surrounded by mountains and forests, you should consider the following: 1. **Weather Conditions**: Be prepared for the local weather. It can change rapidly, especially in mountainous areas, so check the forecast and dress in layers. 2. **Safety**: If you plan to go on the water, make sure you have a life jacket and know how to swim. If you're not a strong swimmer, consider wearing a life jacket even if you're just walking along the shore. 3. **Wildlife**: Be aware of the local wildlife and maintain a safe distance. Do not feed the animals, as this can disrupt their natural behavior and diet. 4. **Leave No Trace**: Respect the environment by not littering and by staying on designated paths or trails. 5. **Emergency Preparedness**: Have a first aid kit and know basic first aid. It's also a good idea to have a way to contact emergency services if needed. 6. **Navigation**: If you're going into the woods or on the water, have a map or GPS device and know how to use it. 7. **Hydration and Nutrition**: Bring enough water and food for your visit, especially if you'll be active. 8. **Clothing and Gear**: Wear appropriate clothing for the weather and activities you plan to do. Bring sturdy footwear if you plan to hike or walk on uneven terrain. 9. **Local Regulations**: Follow any posted rules or regulations, which might include fishing regulations, fire restrictions, or…
 Input
Prompt
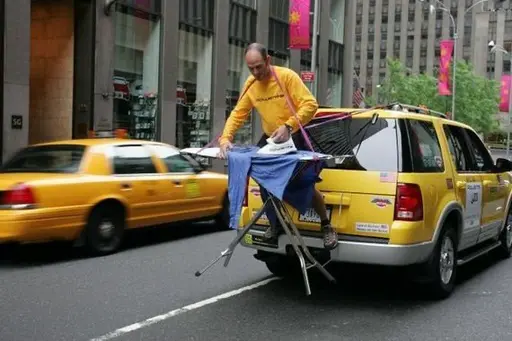
What is unusual about this image?
Response
The image shows a person ironing clothes on the back of a moving vehicle, which is an unusual and potentially dangerous activity. Ironing clothes while a vehicle is in motion can be hazardous for the person doing the ironing as well as for other road users. The person is at risk of losing balance and falling off the vehicle, which could result in serious injury. Additionally, the iron could potentially cause a fire or damage to the vehicle or its surroundings if it overheats or malfunctions. This scene is not a safe or typical way to iron clothes and is likely staged for comedic or dramatic effect.
Over LLaVA 1.6 Vicuna 13B
LLaVA 1.6 Vicuna 13B is een model van Community in de categorie Multimodaal. Op Railwail kost LLaVA 1.6 Vicuna 13B ≈ US$ 0,1021 per uitvoering. Het contextvenster bevat 4.096 tokens, en een antwoord kan tot 1.024 tokens lang zijn.
Prijzen
| Typische uitvoering (≈ 87 s op L40S) | US$ 0,1021 per uitvoering |
|---|---|
| GPU-tijd (L40S) | US$ 0,00117 per GPU-seconde |
- Afgerekend wordt de GPU-tijd die de run werkelijk gebruikt. Wanneer de run start, wordt het 3-voudige van de typische prijs van uw saldo gereserveerd en later verrekend.
- 1 credit = US$ 0,01
Kostencalculator
Prijscalculator
Typisch volgens de provider: ongeveer 87,2 s
Totaal
US$ 10,21
1.021 credits
Per run
US$ 0,1021 · 10,21 credits
Afgerekend wordt de werkelijke GPU-tijd; dit is een schatting.
API
Geen geverifieerd API-voorbeeld
De openbare API geeft een ander invoerformaat door dan dit model nodig heeft. Gebruik de playground hierboven.
Specificaties
- Model-ID
llava-1-6-vicuna-13b- Ontwikkelaar
- Community
- Categorie
- Multimodaal
- Invoer
- Tekst, Afbeelding
- Uitvoer
- Tekst
- Contextvenster
- 4.096 tokens
- Max. uitvoer
- 1.024 tokens
- Facturering
- Op basis van gebruik (tokens of GPU-tijd)
- Catalogusitem bijgewerkt
- 23 september 2026
Invoerparameters
Invoeren en instellingen uit het invoerschema van het model. Het voorbeeld in de API-sectie toont welke daarvan de API accepteert.
imageVerplichtImage to analyze
Type: TekstStandaard: –Toegestane waarden: –promptVerplichtQuestion or instruction about the image
Type: TekstStandaard:Describe this image in detail.Toegestane waarden: tot 4.000 tekenstop_pType: GetalStandaard:1Toegestane waarden: 0 tot 1max_tokensType: Geheel getalStandaard:512Toegestane waarden: 1 tot 1.024temperatureType: GetalStandaard:0.2Toegestane waarden: 0 tot 2
Tags
- replicate
- llava
- captioning
- vqa
- vision-understanding
- open-weights
- image
Veelgestelde vragen
Wat is LLaVA 1.6 Vicuna 13B?
LLaVA 1.6 Vicuna 13B is een model van Community in de categorie Multimodaal.
Hoeveel kost LLaVA 1.6 Vicuna 13B op Railwail?
Op Railwail kost LLaVA 1.6 Vicuna 13B ≈ US$ 0,1021 per uitvoering. U betaalt voor wat elke aanvraag daadwerkelijk verbruikt. Gebruik wordt betaald met vooraf gekochte credits; 1 credit is gelijk aan US$ 0,01.
Wat is het contextvenster van LLaVA 1.6 Vicuna 13B?
Het contextvenster van LLaVA 1.6 Vicuna 13B bevat 4.096 tokens. Een antwoord kan tot 1.024 tokens lang zijn.
Hoe snel is LLaVA 1.6 Vicuna 13B?
Er zijn nog niet genoeg gemeten runs van LLaVA 1.6 Vicuna 13B op Railwail om een uitvoeringstijd op te geven. Dit hangt af van de invoer, de instellingen en de belasting bij de provider.
Is LLaVA 1.6 Vicuna 13B beter dan BLIP?
Dat hangt van de taak af. LLaVA 1.6 Vicuna 13B (Community) en BLIP (Salesforce) zijn beide modellen in de categorie Multimodaal. De vergelijkingspagina toont hun prijzen en specificaties naast elkaar.
LLaVA 1.6 Vicuna 13B en BLIP vergelijkenKan LLaVA 1.6 Vicuna 13B afbeeldingen verwerken?
Ja. LLaVA 1.6 Vicuna 13B accepteert afbeeldingen als invoer naast tekst.
Vergelijkbare modellen
Alle in deze categorie- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
≈ US$ 0,0457/uitvoering
55 % goedkoper per eenheid
LLaVA 1.6 Vicuna 13B en CLIP Interrogator vergelijken - Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
≈ US$ 0,0050/uitvoering
95 % goedkoper per eenheid
LLaVA 1.6 Vicuna 13B en Depth Anything v2 vergelijken
Alle modellen via één API
Één API-sleutel voor elk model op Railwail. Gebruik wordt afgerekend via vooraf gekochte credits, 1 credit = US$ 0,01.