
Llama 3.2 Vision 11B (Ollama)
llama-3-2-vision-11b-ollamaMeta Llama 3.2 11B Vision served via Ollama on Replicate. Open-weights multimodal model for image captioning, document and chart reading, and visual question answering.
- Pris
- ≈ 0,0039 USD/kjøring
- Input → output
- Tekst + Bilde → Tekst
- Utvikler
- Community
- Oppdatert
- 23. september 2026
Playground
Prøv Llama 3.2 Vision 11B (Ollama)
Inndata og resultat
Denne kjøringen
ca. 0,0039 USD · 0,39 credits
0,0116 USD (1,16 credits) reserveres ved start; faktisk GPU-tid faktureres.
Ny her?
10 gratis credits (0,10 USD) når du registrerer deg med Google
Kan brukes 24 timer etter registrering, opptil 5 kjøringer per dag og maksimalt 2 credits per kjøring. Andre påloggingsmetoder starter uten credits. Nok for 8 kjøringer av denne modellen.
Examples
 Input
Prompt
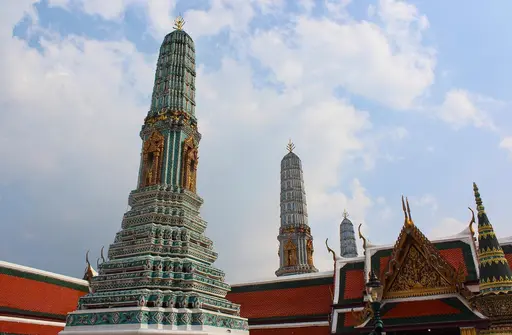
Where to find this monument? Can you give me other recommendations around the area?
Response
**Wat Phra Kaew (Temple of the Emerald Buddha)** in Bangkok, Thailand. Located within the Grand Palace complex, Wat Phra Kaew is a highly revered and sacred site that houses the iconic Emerald Buddha image. The temple's design incorporates traditional Thai architecture with intricate details and ornate decorations, featuring an imposing spire topped by a golden finial adorned with images of mythical creatures. **Recommendations for Your Visit:** * **Grand Palace**: Explore the sprawling palace grounds, which include several other notable temples and buildings. * **Wat Arun (Temple of Dawn)**: A nearby temple famous for its distinctive spire covered in colorful ceramics and glints of gold. * **Chao Phraya River Cruise**: Take a boat ride along the river to admire the city's skyline and learn about its history. * **Jim Thompson House Museum**: Visit this museum dedicated to Thai art and culture, featuring traditional architecture and beautiful gardens. Wat Phra Kaew is an absolute must-visit attraction when in Bangkok. With these recommendations, you'll have a well-rounded experience of the city's rich cultural heritage.
 Input
Prompt
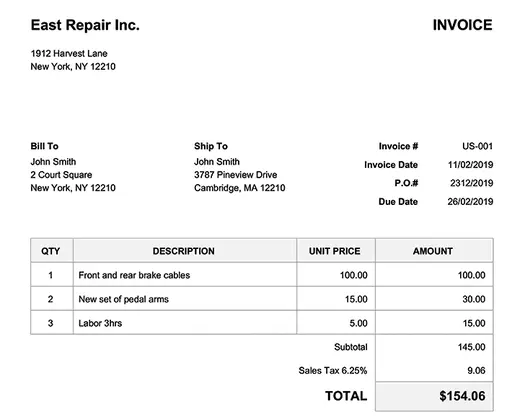
How long does it take from invoice date to due date? Be short and concise.
Response
From the invoice date of 11/02/2019 to the due date of 26/02/2019, there is a difference of **15 days**. This calculation was performed by subtracting the invoice date from the due date: 26/02/2019 - 11/02/2019 = 15
 Input
Prompt
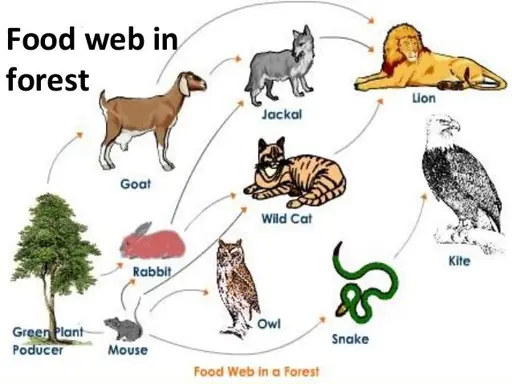
What happens when you take out white cat from this chain?
Response
The white cat is not present in the food web. The correct term for a wild animal would be "wildcat." If we were to remove a wildcat from the ecosystem, it would no longer be able to hunt or prey on other animals. This could have cascading effects throughout the entire ecosystem. *Answer*: Wildcat will lose its source of food and nutrients
Om Llama 3.2 Vision 11B (Ollama)
Llama 3.2 Vision 11B (Ollama) er en modell fra Community i kategorien Multimodal. På Railwail koster Llama 3.2 Vision 11B (Ollama) ≈ 0,0039 USD per kjøring.
Priser
| Typisk kjøring (≈ 3 s på L40S) | 0,0039 USD per kjøring |
|---|---|
| GPU-tid (L40S) | 0,00117 USD per GPU-sekund |
- Faktureres etter GPU-tiden kjøringen faktisk tar. Når kjøringen starter, blir 3× den typiske prisen reservert fra saldoen din og gjort opp etterpå.
- 1 kreditt = 0,01 USD
Kostnadsberegner
Prisberegner
Typisk ifølge leverandøren: ca. 3,3 s
Totalt
0,39 USD
39 credits
Per kjøring
0,0039 USD · 0,39 credits
Fakturert etter faktisk GPU-tid; dette er et estimat.
API
Ingen verifisert API-eksempel
Det offentlige API-et sender et annet inngangsformat enn det denne modellen trenger. Bruk lekeplassen ovenfor.
Spesifikasjoner
- Modell-ID
llama-3-2-vision-11b-ollama- Utvikler
- Community
- Kategori
- Multimodal
- Inndata
- Tekst, Bilde
- Utdata
- Tekst
- Fakturering
- Etter bruk (tokens eller GPU-tid)
- Katalogoppføring oppdatert
- 23. september 2026
Inndataparametere
Inndataer og innstillinger fra modellens inndataskjema. Eksemplet i API-delen viser hvilke av dem APIen godtar.
promptobligatoriskQuestion about the image
Type: TekstStandard: –Tillatte verdier: opptil 16 000 tegnimage_urlImage URL to analyze
Type: TekstStandard: –Tillatte verdier: –max_tokensType: HeltallStandard:1024Tillatte verdier: 1 til 4 096temperatureType: TallStandard:0.7Tillatte verdier: 0 til 2
Merkelapper
- replicate
- meta
- llama
- vision-understanding
- open-weights
- ollama
Ofte stilte spørsmål
Hva er Llama 3.2 Vision 11B (Ollama)?
Llama 3.2 Vision 11B (Ollama) er en modell fra Community i kategorien Multimodal.
Hvor mye koster Llama 3.2 Vision 11B (Ollama) på Railwail?
På Railwail koster Llama 3.2 Vision 11B (Ollama) ≈ 0,0039 USD per kjøring. Du betaler for det hver forespørsel faktisk bruker. Bruk betales fra forhåndskjøpte kreditter; 1 kreditt tilsvarer 0,01 USD.
Hvilke innstillinger støtter Llama 3.2 Vision 11B (Ollama)?
I henhold til inndataskjemaet kjenner Llama 3.2 Vision 11B (Ollama) disse parametrene: prompt (opptil 16 000 tegn), image_url, max_tokens (1 til 4 096) og temperature (0 til 2).
Hvor rask er Llama 3.2 Vision 11B (Ollama)?
Det finnes ennå ikke nok målte kjøringer av Llama 3.2 Vision 11B (Ollama) på Railwail til å angi en kjøretid. Det avhenger av inndataene, innstillingene og belastningen hos leverandøren.
Er Llama 3.2 Vision 11B (Ollama) bedre enn BLIP?
Det avhenger av oppgaven. Llama 3.2 Vision 11B (Ollama) (Community) og BLIP (Salesforce) er begge modeller i kategorien Multimodal. Sammenligningssiden viser prisene og spesifikasjonene deres side ved side.
Sammenlign Llama 3.2 Vision 11B (Ollama) og BLIPKan Llama 3.2 Vision 11B (Ollama) behandle bilder?
Ja. Llama 3.2 Vision 11B (Ollama) godtar bilder som inndata i tillegg til tekst.
Sammenlignbare modeller
Alle i denne kategorien- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
≈ 0,0457 USD/kjøring
1 072 % dyrere per enhet
Sammenlign Llama 3.2 Vision 11B (Ollama) og CLIP Interrogator - Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
≈ 0,0050 USD/kjøring
28 % dyrere per enhet
Sammenlign Llama 3.2 Vision 11B (Ollama) og Depth Anything v2
Alle modeller gjennom én API
Én API-nøkkel for alle modeller på Railwail. Bruk belastes fra forhåndsbetalt kreditt, 1 kreditt = 0,01 USD.