
DeepSeek-VL 7B
deepseek-vl-7bDeepSeek-VL 7B chat model. Vision-language model with hybrid vision encoder and strong real-world visual question answering performance.
- Pris
- ≈ 0,0086 US$/körning
- Kontext
- 4 096 tokens
- Max. utdata
- 2 048 tokens
- Inmatning → utmatning
- Text + Bild → Text
- Utvecklare
- DeepSeek
- Uppdaterad
- 23 september 2026
Playground
Prova DeepSeek-VL 7B
Ingen inmatningsformulär
Ingen inmatningsformulär för denna modell än
Dess inmatningar är ännu inte dokumenterade. För att ingen körning ska misslyckas på grund av felaktig inmatning erbjuder vi ingen formulär här. Välj istället en jämförbar modell.
Examples
 Input
Prompt
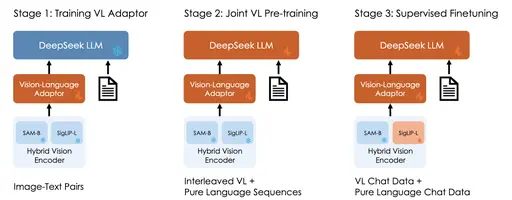
Describe each stage of this image
Response
The image depicts a three-stage process for training a vision-language model. 1. Stage 1: Training VL Adapter: In this stage, a vision-language adapter is trained using supervised fine-tuning. The adapter is trained on image-text pairs and pure language sequences. 2. Stage 2: Joint VL Pre-training: In this stage, a joint vision-language model is pre-trained using self-supervised learning. The model is trained on image-text pairs and pure language sequences. 3. Stage 3: Supervised Fine-tuning: In this stage, the model is fine-tuned on supervised tasks using image-text pairs and pure language sequences. The model is trained using a hybrid vision-language adapter, which combines a vision-language adapter with a language model. The model is trained on a variety of tasks, including image captioning, visual question answering, and visual reasoning. The model is able to understand the visual content of an image and generate a natural language description or answer.
 Input
Prompt
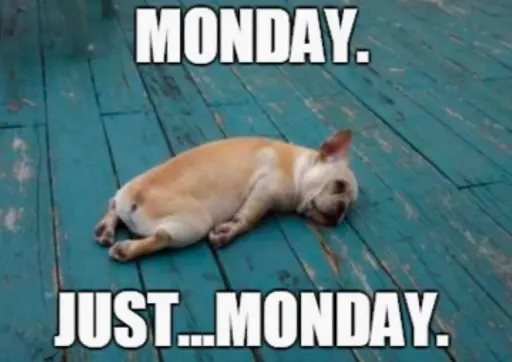
Describe this image
Response
The image you've provided is a meme featuring a French Bulldog lying on its side on a blue wooden floor. The dog's head is resting on its paws, and it appears to be sleeping. The meme has a text overlay that reads "MONDAY. JUST...MONDAY." This suggests that the meme is making a humorous comment about the start of the work week. The dog's relaxed posture and the text overlay together create a light-hearted and relatable message.
Om DeepSeek-VL 7B
DeepSeek-VL 7B är en modell av DeepSeek i kategorin Multimodal. På Railwail kostar DeepSeek-VL 7B ≈ 0,0086 US$ per körning. Kontextfönstret innehåller 4 096 tokens, och ett svar kan vara upp till 2 048 tokens långt.
Priser
| Typisk körning (≈ 7 s på L40S) | 0,0086 US$ per körning |
|---|---|
| GPU-tid (L40S) | 0,00117 US$ per GPU-sekund |
- Faktureras enligt den GPU-tid som körningen faktiskt tar. När körningen startar reserveras 3× det typiska priset från ditt saldo och regleras efteråt.
- 1 kredit = 0,01 US$
Kostnadsräknare
Prisräknare
Typisk enligt leverantören: ca 7,3 s
Totalt
0,86 US$
86 krediter
Per körning
0,0086 US$ · 0,86 krediter
Faktureras enligt faktisk GPU-tid; detta är en uppskattning.
API
Inget verifierat API-exempel
Det offentliga API:et skickar ett annat inmatningsformat än vad denna modell behöver. Använd lekplatsen ovan.
Specifikationer
- Modell-ID
deepseek-vl-7b- Utvecklare
- DeepSeek
- Kategori
- Multimodal
- Inmatning
- Text, Bild
- Utmatning
- Text
- Kontextfönster
- 4 096 tokens
- Max. utmatning
- 2 048 tokens
- Fakturering
- Efter användning (tokens eller GPU-tid)
- Kataloginlägg uppdaterat
- 23 september 2026
Taggar
- replicate
- multimodal
- vision-understanding
- deepseek
- open-weights
Vanliga frågor
Vad är DeepSeek-VL 7B?
DeepSeek-VL 7B är en modell av DeepSeek i kategorin Multimodal.
Vad kostar DeepSeek-VL 7B på Railwail?
På Railwail kostar DeepSeek-VL 7B ≈ 0,0086 US$ per körning. Du debiteras för det som varje begäran faktiskt använder. Användningen betalas från förbetald kredit; 1 kredit motsvarar 0,01 US$.
Hur stort är kontextfönstret för DeepSeek-VL 7B?
Kontextfönstret för DeepSeek-VL 7B innehåller 4 096 tokens. Ett svar kan vara upp till 2 048 tokens långt.
Hur snabb är DeepSeek-VL 7B?
Det finns ännu inte tillräckligt många uppmätta körningar av DeepSeek-VL 7B på Railwail för att ange en körningstid. Det beror på inmatningen, inställningarna och belastningen hos leverantören.
Är DeepSeek-VL 7B bättre än BLIP?
Det beror på uppgiften. DeepSeek-VL 7B (DeepSeek) och BLIP (Salesforce) är båda modeller i kategorin Multimodal. Jämförelsesidan visar deras priser och specifikationer sida vid sida.
Jämför DeepSeek-VL 7B och BLIPKan DeepSeek-VL 7B bearbeta bilder?
Ja. DeepSeek-VL 7B accepterar bilder som inmatning utöver text.
Jämförbara modeller
Alla i denna kategori- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
Alla modeller via ett API
En API-nyckel för alla modeller på Railwail. Användningen debiteras från förbetald kredit, 1 kredit = 0,01 US$.