
Llama 3.2 Vision 11B (Ollama)
llama-3-2-vision-11b-ollamaMeta Llama 3.2 11B Vision served via Ollama on Replicate. Open-weights multimodal model for image captioning, document and chart reading, and visual question answering.
- Pris
- ≈ 0,0039 US$/körning
- Inmatning → utmatning
- Text + Bild → Text
- Utvecklare
- Community
- Uppdaterad
- 23 september 2026
Playground
Prova Llama 3.2 Vision 11B (Ollama)
Inmatning & resultat
Denna körning
ca. 0,0039 US$ · 0,39 credits
0,0116 US$ (1,16 credits) reserveras vid start; den faktiska GPU-tiden faktureras.
Ny här?
10 gratis credits (0,10 US$) när du registrerar dig med Google
Användbar 24 timmar efter registrering, upp till 5 körningar per dag och högst 2 credits per körning. Andra inloggningsmetoder startar utan credits. Räcker för 8 körningar av denna modell.
Examples
 Input
Prompt
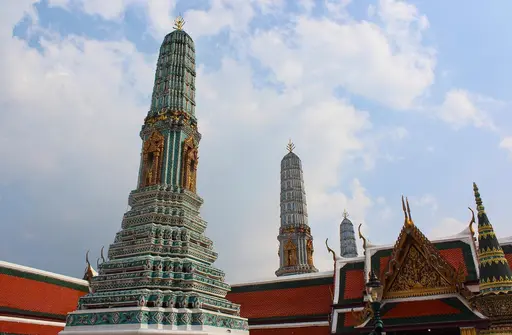
Where to find this monument? Can you give me other recommendations around the area?
Response
**Wat Phra Kaew (Temple of the Emerald Buddha)** in Bangkok, Thailand. Located within the Grand Palace complex, Wat Phra Kaew is a highly revered and sacred site that houses the iconic Emerald Buddha image. The temple's design incorporates traditional Thai architecture with intricate details and ornate decorations, featuring an imposing spire topped by a golden finial adorned with images of mythical creatures. **Recommendations for Your Visit:** * **Grand Palace**: Explore the sprawling palace grounds, which include several other notable temples and buildings. * **Wat Arun (Temple of Dawn)**: A nearby temple famous for its distinctive spire covered in colorful ceramics and glints of gold. * **Chao Phraya River Cruise**: Take a boat ride along the river to admire the city's skyline and learn about its history. * **Jim Thompson House Museum**: Visit this museum dedicated to Thai art and culture, featuring traditional architecture and beautiful gardens. Wat Phra Kaew is an absolute must-visit attraction when in Bangkok. With these recommendations, you'll have a well-rounded experience of the city's rich cultural heritage.
 Input
Prompt
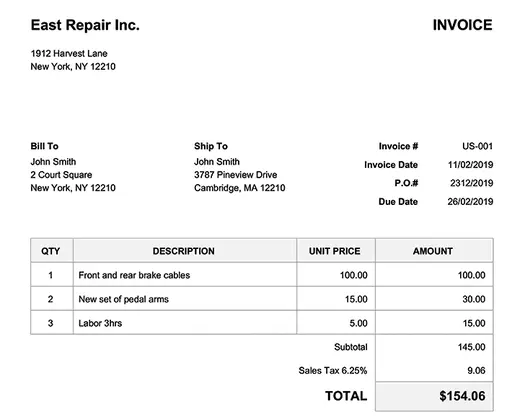
How long does it take from invoice date to due date? Be short and concise.
Response
From the invoice date of 11/02/2019 to the due date of 26/02/2019, there is a difference of **15 days**. This calculation was performed by subtracting the invoice date from the due date: 26/02/2019 - 11/02/2019 = 15
 Input
Prompt
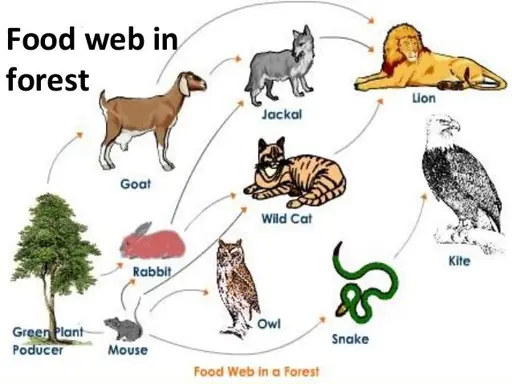
What happens when you take out white cat from this chain?
Response
The white cat is not present in the food web. The correct term for a wild animal would be "wildcat." If we were to remove a wildcat from the ecosystem, it would no longer be able to hunt or prey on other animals. This could have cascading effects throughout the entire ecosystem. *Answer*: Wildcat will lose its source of food and nutrients
Om Llama 3.2 Vision 11B (Ollama)
Llama 3.2 Vision 11B (Ollama) är en modell av Community i kategorin Multimodal. På Railwail kostar Llama 3.2 Vision 11B (Ollama) ≈ 0,0039 US$ per körning.
Priser
| Typisk körning (≈ 3 s på L40S) | 0,0039 US$ per körning |
|---|---|
| GPU-tid (L40S) | 0,00117 US$ per GPU-sekund |
- Faktureras enligt den GPU-tid som körningen faktiskt tar. När körningen startar reserveras 3× det typiska priset från ditt saldo och regleras efteråt.
- 1 kredit = 0,01 US$
Kostnadsräknare
Prisräknare
Typisk enligt leverantören: ca 3,3 s
Totalt
0,39 US$
39 krediter
Per körning
0,0039 US$ · 0,39 krediter
Faktureras enligt faktisk GPU-tid; detta är en uppskattning.
API
Inget verifierat API-exempel
Det offentliga API:et skickar ett annat inmatningsformat än vad denna modell behöver. Använd lekplatsen ovan.
Specifikationer
- Modell-ID
llama-3-2-vision-11b-ollama- Utvecklare
- Community
- Kategori
- Multimodal
- Inmatning
- Text, Bild
- Utmatning
- Text
- Fakturering
- Efter användning (tokens eller GPU-tid)
- Kataloginlägg uppdaterat
- 23 september 2026
Indataparametrar
Inmatningar och inställningar från modellens indataschema. Exemplet i API-avsnittet visar vilka som API:et accepterar.
promptobligatoriskQuestion about the image
Typ: TextStandard: –Tillåtna värden: upp till 16 000 teckenimage_urlImage URL to analyze
Typ: TextStandard: –Tillåtna värden: –max_tokensTyp: HeltalStandard:1024Tillåtna värden: 1 till 4 096temperatureTyp: TalStandard:0.7Tillåtna värden: 0 till 2
Taggar
- replicate
- meta
- llama
- vision-understanding
- open-weights
- ollama
Vanliga frågor
Vad är Llama 3.2 Vision 11B (Ollama)?
Llama 3.2 Vision 11B (Ollama) är en modell av Community i kategorin Multimodal.
Vad kostar Llama 3.2 Vision 11B (Ollama) på Railwail?
På Railwail kostar Llama 3.2 Vision 11B (Ollama) ≈ 0,0039 US$ per körning. Du debiteras för det som varje begäran faktiskt använder. Användningen betalas från förbetald kredit; 1 kredit motsvarar 0,01 US$.
Vilka inställningar stöder Llama 3.2 Vision 11B (Ollama)?
Enligt sitt inmatningsschema känner Llama 3.2 Vision 11B (Ollama) till dessa parametrar: prompt (upp till 16 000 tecken), image_url, max_tokens (1 till 4 096) och temperature (0 till 2).
Hur snabb är Llama 3.2 Vision 11B (Ollama)?
Det finns ännu inte tillräckligt många uppmätta körningar av Llama 3.2 Vision 11B (Ollama) på Railwail för att ange en körningstid. Det beror på inmatningen, inställningarna och belastningen hos leverantören.
Är Llama 3.2 Vision 11B (Ollama) bättre än BLIP?
Det beror på uppgiften. Llama 3.2 Vision 11B (Ollama) (Community) och BLIP (Salesforce) är båda modeller i kategorin Multimodal. Jämförelsesidan visar deras priser och specifikationer sida vid sida.
Jämför Llama 3.2 Vision 11B (Ollama) och BLIPKan Llama 3.2 Vision 11B (Ollama) bearbeta bilder?
Ja. Llama 3.2 Vision 11B (Ollama) accepterar bilder som inmatning utöver text.
Jämförbara modeller
Alla i denna kategori- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
≈ 0,0457 US$/körning
1 072 % dyrare per enhet
Jämför Llama 3.2 Vision 11B (Ollama) och CLIP Interrogator - Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
Alla modeller via ett API
En API-nyckel för alla modeller på Railwail. Användningen debiteras från förbetald kredit, 1 kredit = 0,01 US$.