
LLaVA 1.6 Vicuna 13B
llava-1-6-vicuna-13bLLaVA 1.6 (LLaVA-NeXT) with a Vicuna-13B language backbone. Open vision-language chat model that describes images, answers questions, reads charts and reasons about scenes. Version 1.6 adds higher input resolution and better OCR and reasoning than LLaVA 1.5.
- Pris
- ≈ 0,1021 US$/körning
- Kontext
- 4 096 tokens
- Max. utdata
- 1 024 tokens
- Inmatning → utmatning
- Text + Bild → Text
- Utvecklare
- Community
- Uppdaterad
- 23 september 2026
Playground
Prova LLaVA 1.6 Vicuna 13B
Inmatning & resultat
Denna körning
ca. 0,1021 US$ · 10,21 credits
0,3061 US$ (30,61 credits) reserveras vid start; den faktiska GPU-tiden faktureras.
För konton utan tidigare köp: körningar över 2 credits kräver en påfyllning.
Ny här?
10 gratis credits (0,10 US$) när du registrerar dig med Google
Användbar 24 timmar efter registrering, upp till 5 körningar per dag och högst 2 credits per körning. Andra inloggningsmetoder startar utan credits.
Examples
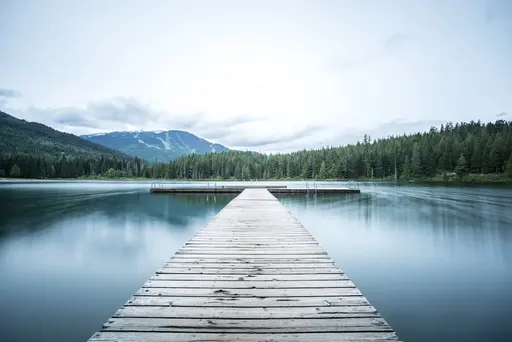 Input
Prompt
What should I take into account when visiting this place?
Response
When visiting a place like the one shown in the image, which appears to be a serene lake with a dock and surrounded by mountains and forests, you should consider the following: 1. **Weather Conditions**: Be prepared for the local weather. It can change rapidly, especially in mountainous areas, so check the forecast and dress in layers. 2. **Safety**: If you plan to go on the water, make sure you have a life jacket and know how to swim. If you're not a strong swimmer, consider wearing a life jacket even if you're just walking along the shore. 3. **Wildlife**: Be aware of the local wildlife and maintain a safe distance. Do not feed the animals, as this can disrupt their natural behavior and diet. 4. **Leave No Trace**: Respect the environment by not littering and by staying on designated paths or trails. 5. **Emergency Preparedness**: Have a first aid kit and know basic first aid. It's also a good idea to have a way to contact emergency services if needed. 6. **Navigation**: If you're going into the woods or on the water, have a map or GPS device and know how to use it. 7. **Hydration and Nutrition**: Bring enough water and food for your visit, especially if you'll be active. 8. **Clothing and Gear**: Wear appropriate clothing for the weather and activities you plan to do. Bring sturdy footwear if you plan to hike or walk on uneven terrain. 9. **Local Regulations**: Follow any posted rules or regulations, which might include fishing regulations, fire restrictions, or…
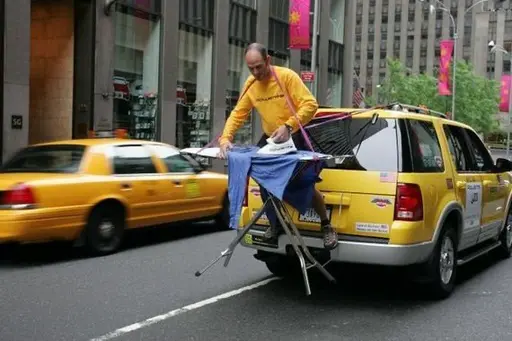 Input
Prompt
What is unusual about this image?
Response
The image shows a person ironing clothes on the back of a moving vehicle, which is an unusual and potentially dangerous activity. Ironing clothes while a vehicle is in motion can be hazardous for the person doing the ironing as well as for other road users. The person is at risk of losing balance and falling off the vehicle, which could result in serious injury. Additionally, the iron could potentially cause a fire or damage to the vehicle or its surroundings if it overheats or malfunctions. This scene is not a safe or typical way to iron clothes and is likely staged for comedic or dramatic effect.
Om LLaVA 1.6 Vicuna 13B
LLaVA 1.6 Vicuna 13B är en modell av Community i kategorin Multimodal. På Railwail kostar LLaVA 1.6 Vicuna 13B ≈ 0,1021 US$ per körning. Kontextfönstret innehåller 4 096 tokens, och ett svar kan vara upp till 1 024 tokens långt.
Priser
| Typisk körning (≈ 87 s på L40S) | 0,1021 US$ per körning |
|---|---|
| GPU-tid (L40S) | 0,00117 US$ per GPU-sekund |
- Faktureras enligt den GPU-tid som körningen faktiskt tar. När körningen startar reserveras 3× det typiska priset från ditt saldo och regleras efteråt.
- 1 kredit = 0,01 US$
Kostnadsräknare
Prisräknare
Typisk enligt leverantören: ca 87,2 s
Totalt
10,21 US$
1 021 krediter
Per körning
0,1021 US$ · 10,21 krediter
Faktureras enligt faktisk GPU-tid; detta är en uppskattning.
API
Inget verifierat API-exempel
Det offentliga API:et skickar ett annat inmatningsformat än vad denna modell behöver. Använd lekplatsen ovan.
Specifikationer
- Modell-ID
llava-1-6-vicuna-13b- Utvecklare
- Community
- Kategori
- Multimodal
- Inmatning
- Text, Bild
- Utmatning
- Text
- Kontextfönster
- 4 096 tokens
- Max. utmatning
- 1 024 tokens
- Fakturering
- Efter användning (tokens eller GPU-tid)
- Kataloginlägg uppdaterat
- 23 september 2026
Indataparametrar
Inmatningar och inställningar från modellens indataschema. Exemplet i API-avsnittet visar vilka som API:et accepterar.
imageobligatoriskImage to analyze
Typ: TextStandard: –Tillåtna värden: –promptobligatoriskQuestion or instruction about the image
Typ: TextStandard:Describe this image in detail.Tillåtna värden: upp till 4 000 teckentop_pTyp: TalStandard:1Tillåtna värden: 0 till 1max_tokensTyp: HeltalStandard:512Tillåtna värden: 1 till 1 024temperatureTyp: TalStandard:0.2Tillåtna värden: 0 till 2
Taggar
- replicate
- llava
- captioning
- vqa
- vision-understanding
- open-weights
- image
Vanliga frågor
Vad är LLaVA 1.6 Vicuna 13B?
LLaVA 1.6 Vicuna 13B är en modell av Community i kategorin Multimodal.
Vad kostar LLaVA 1.6 Vicuna 13B på Railwail?
På Railwail kostar LLaVA 1.6 Vicuna 13B ≈ 0,1021 US$ per körning. Du debiteras för det som varje begäran faktiskt använder. Användningen betalas från förbetald kredit; 1 kredit motsvarar 0,01 US$.
Hur stort är kontextfönstret för LLaVA 1.6 Vicuna 13B?
Kontextfönstret för LLaVA 1.6 Vicuna 13B innehåller 4 096 tokens. Ett svar kan vara upp till 1 024 tokens långt.
Hur snabb är LLaVA 1.6 Vicuna 13B?
Det finns ännu inte tillräckligt många uppmätta körningar av LLaVA 1.6 Vicuna 13B på Railwail för att ange en körningstid. Det beror på inmatningen, inställningarna och belastningen hos leverantören.
Är LLaVA 1.6 Vicuna 13B bättre än BLIP?
Det beror på uppgiften. LLaVA 1.6 Vicuna 13B (Community) och BLIP (Salesforce) är båda modeller i kategorin Multimodal. Jämförelsesidan visar deras priser och specifikationer sida vid sida.
Jämför LLaVA 1.6 Vicuna 13B och BLIPKan LLaVA 1.6 Vicuna 13B bearbeta bilder?
Ja. LLaVA 1.6 Vicuna 13B accepterar bilder som inmatning utöver text.
Jämförbara modeller
Alla i denna kategori- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
Alla modeller via ett API
En API-nyckel för alla modeller på Railwail. Användningen debiteras från förbetald kredit, 1 kredit = 0,01 US$.