
LLaVA 1.6 Vicuna 13B
llava-1-6-vicuna-13bLLaVA 1.6 (LLaVA-NeXT) with a Vicuna-13B language backbone. Open vision-language chat model that describes images, answers questions, reads charts and reasons about scenes. Version 1.6 adds higher input resolution and better OCR and reasoning than LLaVA 1.5.
- Fiyat
- ≈ $0,1021/çalıştırma
- Bağlam
- 4.096 token
- Maks. Çıkış
- 1.024 token
- Giriş → Çıkış
- Metin + Görüntü → Metin
- Geliştirici
- Community
- Güncellendi
- 23 Eylül 2026
Playground
LLaVA 1.6 Vicuna 13B'ı deneyin
Giriş & Sonuç
Bu çalıştırma
yaklaşık $0,1021 · 10,21 kredi
Başlangıçta $0,3061 (30,61 kredi) ayrılır; gerçek GPU süresi faturalandırılır.
Satın alma olmayan hesaplar için: 2 kredinin üzerindeki çalıştırmalar bir yükleme gerektirir.
Yeni misiniz?
Google ile kaydolduğunuzda 10 ücretsiz kredi ($0,10)
Kaydolduktan 24 saat sonra kullanılabilir, günde 5 çalıştırmaya kadar ve çalıştırma başına en fazla 2 kredi. Diğer oturum açma yöntemleri kredi olmadan başlar.
Examples
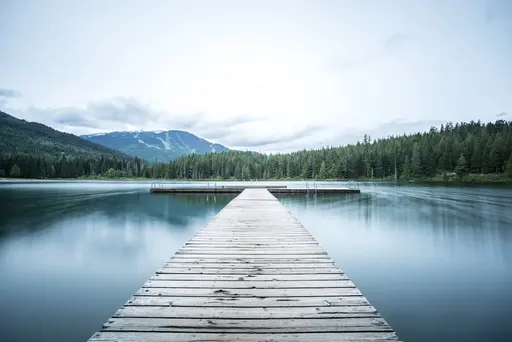 Input
Prompt
What should I take into account when visiting this place?
Response
When visiting a place like the one shown in the image, which appears to be a serene lake with a dock and surrounded by mountains and forests, you should consider the following: 1. **Weather Conditions**: Be prepared for the local weather. It can change rapidly, especially in mountainous areas, so check the forecast and dress in layers. 2. **Safety**: If you plan to go on the water, make sure you have a life jacket and know how to swim. If you're not a strong swimmer, consider wearing a life jacket even if you're just walking along the shore. 3. **Wildlife**: Be aware of the local wildlife and maintain a safe distance. Do not feed the animals, as this can disrupt their natural behavior and diet. 4. **Leave No Trace**: Respect the environment by not littering and by staying on designated paths or trails. 5. **Emergency Preparedness**: Have a first aid kit and know basic first aid. It's also a good idea to have a way to contact emergency services if needed. 6. **Navigation**: If you're going into the woods or on the water, have a map or GPS device and know how to use it. 7. **Hydration and Nutrition**: Bring enough water and food for your visit, especially if you'll be active. 8. **Clothing and Gear**: Wear appropriate clothing for the weather and activities you plan to do. Bring sturdy footwear if you plan to hike or walk on uneven terrain. 9. **Local Regulations**: Follow any posted rules or regulations, which might include fishing regulations, fire restrictions, or…
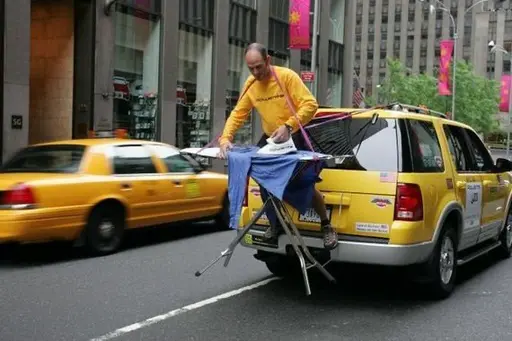 Input
Prompt
What is unusual about this image?
Response
The image shows a person ironing clothes on the back of a moving vehicle, which is an unusual and potentially dangerous activity. Ironing clothes while a vehicle is in motion can be hazardous for the person doing the ironing as well as for other road users. The person is at risk of losing balance and falling off the vehicle, which could result in serious injury. Additionally, the iron could potentially cause a fire or damage to the vehicle or its surroundings if it overheats or malfunctions. This scene is not a safe or typical way to iron clothes and is likely staged for comedic or dramatic effect.
LLaVA 1.6 Vicuna 13B Hakkında
LLaVA 1.6 Vicuna 13B, Community tarafından Multimodal kategorisinde geliştirilen bir modeldir. Railwail üzerinde LLaVA 1.6 Vicuna 13B maliyeti ≈ $0,1021 çalıştırma başına. Kontekst penceresi 4.096 token içerir ve bir yanıt en fazla 1.024 token uzunluğunda olabilir.
Fiyatlandırma
| Tipik çalıştırma (≈ 87 s, L40S üzerinde) | $0,1021 çalıştırma başına |
|---|---|
| GPU Süresi (L40S) | $0,00117 GPU saniyesi başına |
- Çalıştırmanın gerçekten aldığı GPU süresi için faturalandırılır. Çalıştırma başladığında, bakiyenizden tipik fiyatın 3 katı ayrılır ve daha sonra kapatılır.
- 1 kredi = $0,01
Maliyet Hesaplayıcı
Fiyat hesaplayıcı
Sağlayıcıya göre tipik: yaklaşık 87,2 s
Toplam
$10,21
1.021 kredi
Çalışma başına
$0,1021 · 10,21 kredi
Gerçek GPU süresi faturalandırılır; bu bir tahmindir.
API
Doğrulanmış API örneği yok
Genel API, bu modelin ihtiyaç duyduğundan farklı bir giriş biçimi iletir. Yukarıdaki oyun alanını kullanın.
Özellikler
- Model Kimliği
llava-1-6-vicuna-13b- Geliştirici
- Community
- Kategori
- Multimodal
- Giriş
- Metin, Görüntü
- Çıkış
- Metin
- Bağlam penceresi
- 4.096 token
- Maks. çıkış
- 1.024 token
- Faturalandırma
- Kullanıma göre (token veya GPU süresi)
- Katalog girişi güncellendi
- 23 Eylül 2026
Giriş Parametreleri
Modelin giriş şemasından giriş ve ayarlar. API bölümündeki örnek, API'nin hangilerini kabul ettiğini gösterir.
imagegerekliImage to analyze
Tür: MetinVarsayılan: –İzin verilen değerler: –promptgerekliQuestion or instruction about the image
Tür: MetinVarsayılan:Describe this image in detail.İzin verilen değerler: en fazla 4.000 karaktertop_pTür: SayıVarsayılan:1İzin verilen değerler: 0 ile 1 arasındamax_tokensTür: Tam sayıVarsayılan:512İzin verilen değerler: 1 ile 1.024 arasındatemperatureTür: SayıVarsayılan:0.2İzin verilen değerler: 0 ile 2 arasında
Etiketler
- replicate
- llava
- captioning
- vqa
- vision-understanding
- open-weights
- image
Sık Sorulan Sorular
LLaVA 1.6 Vicuna 13B nedir?
LLaVA 1.6 Vicuna 13B, Community tarafından Multimodal kategorisinde oluşturulan bir modeldir.
LLaVA 1.6 Vicuna 13B Railwail'de ne kadar maliyetlidir?
Railwail üzerinde LLaVA 1.6 Vicuna 13B maliyeti ≈ $0,1021 çalıştırma başına. Her istek gerçekten ne kadar kullanırsa o kadar ücretlendirilirsiniz. Kullanım ön ödemeli kredilerden ödenir; 1 kredi $0,01 değerindedir.
LLaVA 1.6 Vicuna 13B'nin kontekst penceresi ne kadardır?
LLaVA 1.6 Vicuna 13B'nin kontekst penceresi 4.096 token içerir. Bir yanıt en fazla 1.024 token uzunluğunda olabilir.
LLaVA 1.6 Vicuna 13B ne kadar hızlıdır?
Railwail'de LLaVA 1.6 Vicuna 13B için henüz çalıştırma süresi belirtmek için yeterli ölçülen çalıştırma yoktur. Bu, giriş, ayarlar ve sağlayıcıdaki yüke bağlıdır.
LLaVA 1.6 Vicuna 13B, BLIP'dan daha iyi midir?
Bu göreve bağlıdır. LLaVA 1.6 Vicuna 13B (Community) ve BLIP (Salesforce) her ikisi de Multimodal kategorisinde modellerdir. Karşılaştırma sayfası fiyatlarını ve özelliklerini yan yana gösterir.
LLaVA 1.6 Vicuna 13B ve BLIP'ı karşılaştırLLaVA 1.6 Vicuna 13B görüntüleri işleyebilir mi?
Evet. LLaVA 1.6 Vicuna 13B metne ek olarak giriş olarak görüntüleri kabul eder.
Karşılaştırılabilir modeller
Bu kategorideki tümü- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
≈ $0,0457/çalıştırma
Birim başına 55 % daha ucuz
LLaVA 1.6 Vicuna 13B ve CLIP Interrogator karşılaştır - Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
≈ $0,0050/çalıştırma
Birim başına 95 % daha ucuz
LLaVA 1.6 Vicuna 13B ve Depth Anything v2 karşılaştır
Tüm Modeller Tek Bir API Aracılığıyla
Railwail'deki her model için bir API anahtarı. Kullanım, ön ödemeli kredilerden tahsil edilir, 1 kredi = $0,01.