
LLaVA v1.6 34B
llava-v1-6-34bLLaVA v1.6 on a Nous-Hermes-2 34B base, served on Replicate. Open-source vision-language assistant for image question answering, description and visual reasoning at higher resolution.
- Status
- Nicht verfügbar
- Eingabe → Ausgabe
- Text + Bild → Text
- Entwickler
- Community
- Aktualisiert
- 23. September 2026
LLaVA v1.6 34B ist derzeit nicht verfügbar
Derzeit nicht verfügbar: Dieses Modell ist deaktiviert.
Die Angaben auf dieser Seite kannst du weiter nachlesen. Mit einer der verfügbaren Alternativen unten kannst du sofort ein vergleichbares Modell nutzen.
Zu den AlternativenVergleichbare Modelle
Alle dieser Kategorie- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
ca. 0,00030 $/Lauf
- Claude Opus 4.7Anthropic
Anthropic's April 2026 flagship. 87.6% on SWE-bench Verified, 3x higher image resolution, output self-verification, vision + reasoning.
6,00 $/1 Mio. In
- Claude Sonnet 4.6Anthropic
Anthropic's balanced mid-tier model from February 2026. Best price/performance for production workloads: 5x cheaper than Opus, near-flagship quality.
3,60 $/1 Mio. In
Playground
LLaVA v1.6 34B ausprobieren
Eingabe & Ergebnis
Derzeit nicht verfügbar: Dieses Modell ist deaktiviert.
Der Playground ist deaktiviert. Vergleichbare Modelle findest du in derselben Kategorie: Alternativen ansehen
Dieser Lauf
Kein Preis – derzeit nicht verfügbar.
Neu hier?
10 Gratis-Credits (0,10 $) bei Anmeldung mit Google
Nutzbar 24 Stunden nach der Anmeldung, bis zu 5 Läufe pro Tag und höchstens 2 Credits je Lauf. Andere Anmeldearten starten ohne Guthaben.
Beispiele
 Eingabe
Prompt
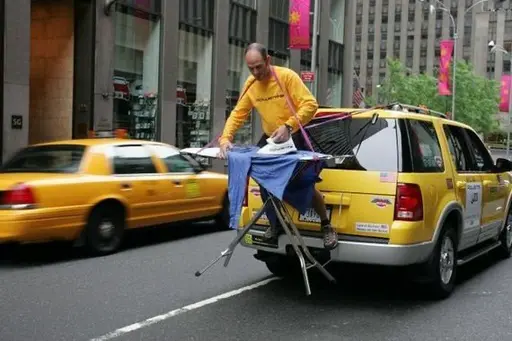
What's unusual about this image?
Antwort
The image shows a person ironing clothes on an ironing board that is placed on the back of a moving vehicle, specifically a yellow taxi. This is an unusual and unsafe situation for several reasons: 1. The person is performing a task that requires concentration and stability, which is difficult to maintain while on a moving vehicle. 2. The ironing board is not secured in place, which increases the risk of it falling off the vehicle, potentially causing injury to the person or others on the road. 3. The person is not wearing any protective gear, such as a harness or safety belt, which would be necessary to secure them in place while the vehicle is in motion. 4. The act of ironing clothes in such a location is impractical and not a typical setting for this activity. 5. The presence of the iron and the ironing board on the back of a moving vehicle poses a hazard to other road users, as it could fall off and cause accidents. Overall, the image depicts a dangerous and unusual situation that is not safe for the person involved or for others on the road.
 Eingabe
Prompt
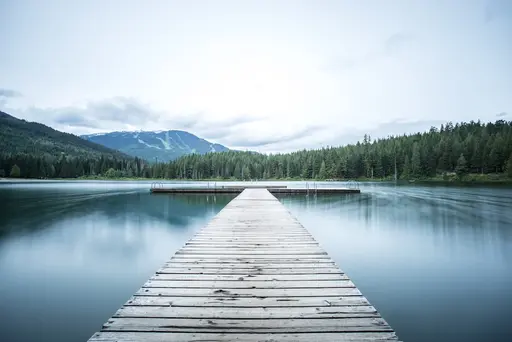
What are the things I should be cautious about when I visit here?
Antwort
When visiting a location like the one shown in the image, which appears to be a serene lake with a dock and surrounded by forested hills, there are several things you should be cautious about: 1. Water Safety: If you plan to swim, make sure you're aware of the water conditions and any potential hazards such as currents, underwater rocks, or cold water temperatures. 2. Dock Sturdiness: Check the dock for any signs of damage or instability before stepping on it. Wooden docks can sometimes be slippery, especially if they're wet. 3. Wildlife: Be aware of the local wildlife and maintain a safe distance. Do not feed or approach animals, as this can disrupt their natural behavior and pose a risk to both you and the animals. 4. Weather Conditions: Be prepared for changes in weather. Sudden storms can occur, especially in mountainous areas, so have appropriate clothing and be ready to seek shelter if necessary. 5. Personal Safety: If you're alone, let someone know where you're going and when you expect to return. It's also a good idea to carry a charged phone in case of emergencies. 6. Leave No Trace: Respect the environment by not littering, not disturbing the natural habitat, and staying on designated paths or areas. 7. Navigation: If you're venturing into the forest or hiking, make sure you have a map or GPS device and know how to use them. It's easy to get lost in unfamiliar terrain. 8. Insects and Plants: Be cautious of insects like mosquitoes and ticks, and be aware of…
Über LLaVA v1.6 34B
LLaVA v1.6 34B ist ein Modell von Community aus der Kategorie Multimodal. Über Railwail ist LLaVA v1.6 34B derzeit nicht verfügbar.
Preise
Derzeit nicht verfügbar: Dieses Modell ist deaktiviert. Für dieses Modell gibt es derzeit keinen Preis, deshalb lässt es sich nicht ausführen.
API
Kein geprüftes API-Beispiel
Die öffentliche API übergibt ein anderes Eingabeformat, als dieses Modell braucht. Nutze den Playground oben.
Spezifikationen
- Modell-ID
llava-v1-6-34b- Entwickler
- Community
- Kategorie
- Multimodal
- Eingabe
- Text, Bild
- Ausgabe
- Text
- Katalogeintrag aktualisiert
- 23. September 2026
Eingabeparameter
Eingaben und Einstellungen laut Eingabeschema des Modells. Welche davon die API annimmt, zeigt das Beispiel im Abschnitt API.
promptPflichtQuestion about the image
Typ: TextStandard: –Erlaubte Werte: bis 16.000 Zeichenimage_urlImage URL to analyze
Typ: TextStandard: –Erlaubte Werte: –max_tokensTyp: GanzzahlStandard:1024Erlaubte Werte: 1 bis 4.096temperatureTyp: ZahlStandard:0.2Erlaubte Werte: 0 bis 2
Schlagwörter
- replicate
- llava
- vision-understanding
- open-source
- vqa
Häufige Fragen
Was ist LLaVA v1.6 34B?
LLaVA v1.6 34B ist ein Modell von Community aus der Kategorie Multimodal. Es steht im Railwail-Katalog, lässt sich derzeit aber nicht ausführen.
Was kostet LLaVA v1.6 34B bei Railwail?
LLaVA v1.6 34B lässt sich über Railwail derzeit nicht ausführen, deshalb gibt es keinen aktuellen Preis. Verfügbare Alternativen mit Preisen stehen weiter unten auf dieser Seite.
Welche Einstellungen unterstützt LLaVA v1.6 34B?
Laut Eingabeschema kennt LLaVA v1.6 34B diese Parameter: prompt (bis 16.000 Zeichen), image_url, max_tokens (1 bis 4.096) und temperature (0 bis 2).
Wie schnell ist LLaVA v1.6 34B?
Für LLaVA v1.6 34B gibt es bei Railwail noch zu wenige gemessene Läufe, um eine Laufzeit anzugeben. Sie hängt von der Eingabe, den Einstellungen und der Auslastung beim Anbieter ab.
Ist LLaVA v1.6 34B besser als BLIP?
Das hängt von der Aufgabe ab. LLaVA v1.6 34B (Community) und BLIP (Salesforce) sind beide Modelle aus der Kategorie Multimodal. Die Vergleichsseite zeigt Preise und Spezifikationen nebeneinander.
LLaVA v1.6 34B und BLIP vergleichenKann LLaVA v1.6 34B Bilder verarbeiten?
Ja. LLaVA v1.6 34B nimmt neben Text auch Bilder als Eingabe an.
Kann ich LLaVA v1.6 34B gerade nutzen?
Derzeit nicht verfügbar: Dieses Modell ist deaktiviert. Die Seite bleibt online; verfügbare Alternativen aus derselben Kategorie stehen weiter unten.
Alle Modelle über eine API
Ein API-Schlüssel für alle Modelle auf Railwail. Abgerechnet wird über vorab gekaufte Credits, 1 Credit = 0,01 $.