
Florence-2 Large
florence-2-largeMicrosoft Florence-2 Large. Unified prompt-based vision foundation model for captioning, detection, segmentation and OCR with a single 770M-param backbone.
- Price
- ≈ $0.0012/run
- Input → output
- Text + Image → Text
- Developer
- Community
- Updated
- September 23, 2026
Playground
Try Florence-2 Large
Input & output
This run
about $0.0012 · 0.12 credits
$0.0036 (0.36 credits) are reserved at the start; the actual GPU time is billed.
New here?
10 free credits ($0.10) when you sign up with Google
Usable 24 hours after sign-up, up to 5 runs per day and at most 2 credits per run. Other sign-in methods start without credits. Enough for 27 runs of this model.
Examples
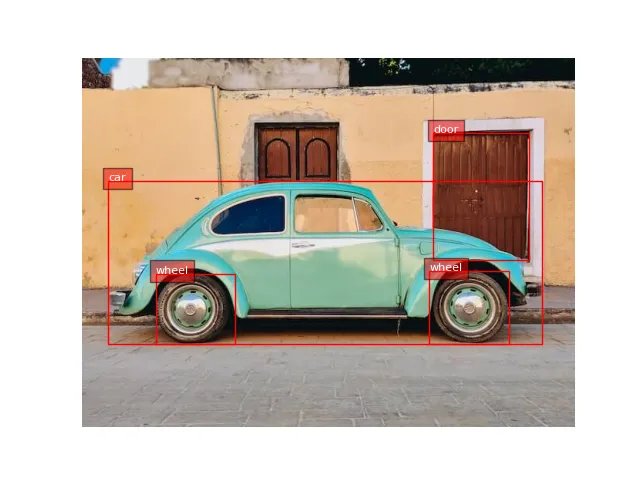 Open full size
 Input
No text prompt: the model only takes the input shown.
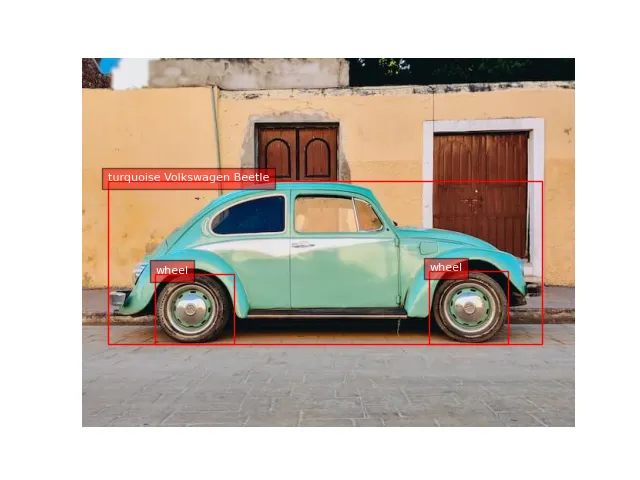 Open full size
 Input
No text prompt: the model only takes the input shown.
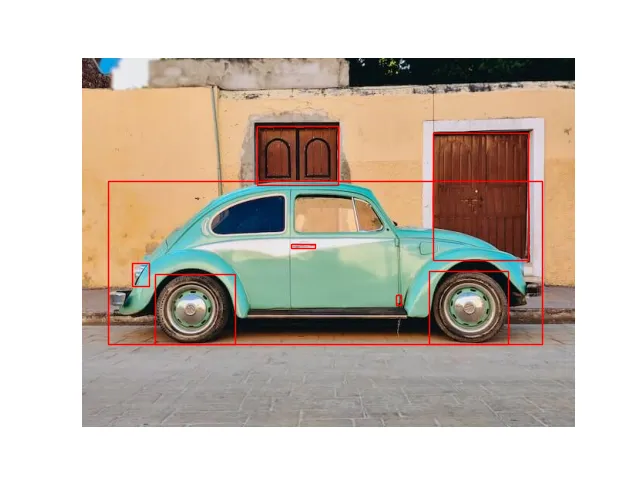 Open full size
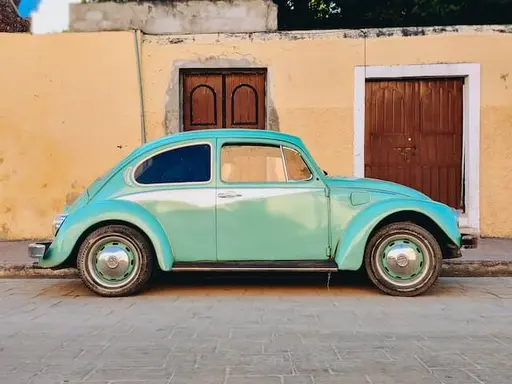 Input
No text prompt: the model only takes the input shown.
About Florence-2 Large
Florence-2 Large is a model by Community in the Multimodal category. On Railwail, Florence-2 Large costs ≈ $0.0012 per run.
Pricing
| Typical run (≈ 1 s on L40S) | $0.0012 per run |
|---|---|
| GPU time (L40S) | $0.00117 per GPU second |
- Billed by the GPU time the run actually takes. When the run starts, 3× the typical price is reserved from your balance and settled afterwards.
- 1 credit = $0.01
Cost calculator
Price calculator
Typical according to the provider: about 1 s
Total
$0.12
12 credits
Per run
$0.0012 · 0.12 credits
Billed by the actual GPU time; this is an estimate.
API
No verified API example
The public API passes a different input format than this model needs. Use the playground above.
Specifications
- Model ID
florence-2-large- Developer
- Community
- Category
- Multimodal
- Input
- Text, Image
- Output
- Text
- Billing
- By usage (tokens or GPU time)
- Catalog entry updated
- September 23, 2026
Input parameters
Inputs and settings from the model's input schema. The example in the API section shows which of them the API accepts.
promptrequiredUser message or task instruction
Type: TextDefault: –Allowed values: up to 4,000 characterstaskType: ChoiceDefault:captionAllowed values: caption, detailed_caption, ocr, object_detection, or segmentationimage_urlImage URL to analyze
Type: TextDefault: –Allowed values: –max_tokensType: IntegerDefault:1024Allowed values: 1 to 4,096temperatureType: NumberDefault:0.7Allowed values: 0 to 2
Tags
- replicate
- multimodal
- vision-understanding
- microsoft
- open-weights
Frequently asked questions
What is Florence-2 Large?
Florence-2 Large is a model by Community in the Multimodal category.
How much does Florence-2 Large cost on Railwail?
On Railwail, Florence-2 Large costs ≈ $0.0012 per run. You are charged for what each request actually uses. Usage is paid from prepaid credits; 1 credit equals $0.01.
Which settings does Florence-2 Large support?
According to its input schema, Florence-2 Large knows these parameters: prompt (up to 4,000 characters), task (caption, detailed_caption, ocr, object_detection, or segmentation), image_url, max_tokens (1 to 4,096), and temperature (0 to 2).
How fast is Florence-2 Large?
There are not enough measured runs of Florence-2 Large on Railwail yet to state a run time. It depends on the input, the settings and the load at the provider.
Is Florence-2 Large better than BLIP?
That depends on the task. Florence-2 Large (Community) and BLIP (Salesforce) are both models in the Multimodal category. The comparison page shows their prices and specifications side by side.
Compare Florence-2 Large and BLIPCan Florence-2 Large process images?
Yes. Florence-2 Large accepts images as input in addition to text.
Comparable models
All in this category- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
All models through one API
One API key for every model on Railwail. Usage is charged from prepaid credits, 1 credit = $0.01.