
LLaVA 1.6 Vicuna 13B
llava-1-6-vicuna-13bLLaVA 1.6 (LLaVA-NeXT) with a Vicuna-13B language backbone. Open vision-language chat model that describes images, answers questions, reads charts and reasons about scenes. Version 1.6 adds higher input resolution and better OCR and reasoning than LLaVA 1.5.
- Precio
- ≈ 0,1021 US$/ejecución
- Contexto
- 4096 tokens
- Salida máxima
- 1024 tokens
- Entrada → Salida
- Texto + Imagen → Texto
- Desarrollador
- Community
- Actualizado
- 23 de septiembre de 2026
Playground
Probar LLaVA 1.6 Vicuna 13B
Entrada y salida
Esta ejecución
aprox. 0,1021 US$ · 10,21 créditos
Se reservan 0,3061 US$ (30,61 créditos) al inicio; se factura el tiempo real de GPU.
Para cuentas sin compra previa: las ejecuciones superiores a 2 créditos necesitan una recarga.
¿Eres nuevo aquí?
10 créditos gratis (0,10 US$) cuando te registres con Google
Disponible 24 horas después del registro, hasta 5 ejecuciones por día y como máximo 2 créditos por ejecución. Otros métodos de inicio de sesión comienzan sin créditos.
Examples
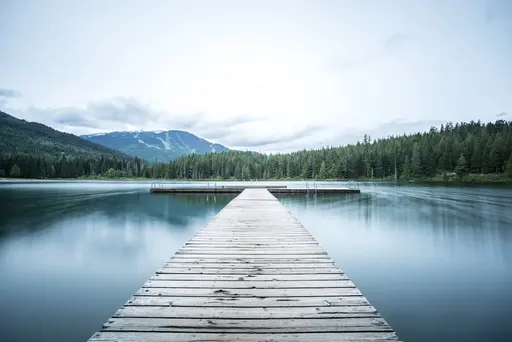 Input
Prompt
What should I take into account when visiting this place?
Response
When visiting a place like the one shown in the image, which appears to be a serene lake with a dock and surrounded by mountains and forests, you should consider the following: 1. **Weather Conditions**: Be prepared for the local weather. It can change rapidly, especially in mountainous areas, so check the forecast and dress in layers. 2. **Safety**: If you plan to go on the water, make sure you have a life jacket and know how to swim. If you're not a strong swimmer, consider wearing a life jacket even if you're just walking along the shore. 3. **Wildlife**: Be aware of the local wildlife and maintain a safe distance. Do not feed the animals, as this can disrupt their natural behavior and diet. 4. **Leave No Trace**: Respect the environment by not littering and by staying on designated paths or trails. 5. **Emergency Preparedness**: Have a first aid kit and know basic first aid. It's also a good idea to have a way to contact emergency services if needed. 6. **Navigation**: If you're going into the woods or on the water, have a map or GPS device and know how to use it. 7. **Hydration and Nutrition**: Bring enough water and food for your visit, especially if you'll be active. 8. **Clothing and Gear**: Wear appropriate clothing for the weather and activities you plan to do. Bring sturdy footwear if you plan to hike or walk on uneven terrain. 9. **Local Regulations**: Follow any posted rules or regulations, which might include fishing regulations, fire restrictions, or…
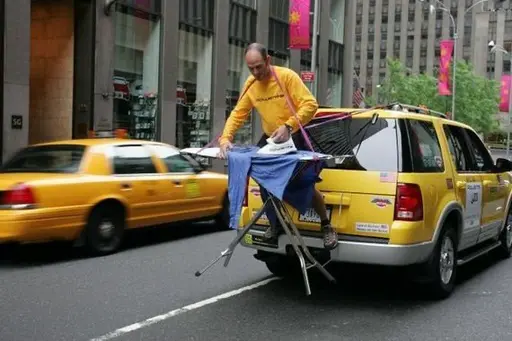 Input
Prompt
What is unusual about this image?
Response
The image shows a person ironing clothes on the back of a moving vehicle, which is an unusual and potentially dangerous activity. Ironing clothes while a vehicle is in motion can be hazardous for the person doing the ironing as well as for other road users. The person is at risk of losing balance and falling off the vehicle, which could result in serious injury. Additionally, the iron could potentially cause a fire or damage to the vehicle or its surroundings if it overheats or malfunctions. This scene is not a safe or typical way to iron clothes and is likely staged for comedic or dramatic effect.
Acerca de LLaVA 1.6 Vicuna 13B
LLaVA 1.6 Vicuna 13B es un modelo de Community en la categoría Multimodal. En Railwail, LLaVA 1.6 Vicuna 13B cuesta ≈ 0,1021 US$ por ejecución. La ventana de contexto contiene 4096 tokens, y una respuesta puede tener hasta 1024 tokens.
Precios
| Ejecución típica (≈ 87 s en L40S) | 0,1021 US$ por ejecución |
|---|---|
| Tiempo de GPU (L40S) | 0,00117 US$ por segundo de GPU |
- Se factura por el tiempo de GPU que realmente tarda la ejecución. Cuando comienza la ejecución, se reserva 3× el precio típico de tu saldo y se liquida después.
- 1 crédito = 0,01 US$
Calculadora de costes
Calculadora de precios
Típico según el proveedor: aprox. 87,2 s
Total
10,21 US$
1021 créditos
Por ejecución
0,1021 US$ · 10,21 créditos
Se factura el tiempo real de GPU; este es un estimado.
API
Sin ejemplo de API verificado
La API pública pasa un formato de entrada diferente al que necesita este modelo. Usa el playground anterior.
Especificaciones
- ID del modelo
llava-1-6-vicuna-13b- Desarrollador
- Community
- Categoría
- Multimodal
- Entrada
- Texto, Imagen
- Salida
- Texto
- Ventana de contexto
- 4096 tokens
- Salida máxima
- 1024 tokens
- Facturación
- Por uso (tokens o tiempo de GPU)
- Entrada del catálogo actualizada
- 23 de septiembre de 2026
Parámetros de entrada
Entradas y configuración del esquema de entrada del modelo. El ejemplo en la sección API muestra cuáles de ellas acepta la API.
imageObligatorioImage to analyze
Tipo: TextoPredeterminado: –Valores permitidos: –promptObligatorioQuestion or instruction about the image
Tipo: TextoPredeterminado:Describe this image in detail.Valores permitidos: Hasta 4000 caracterestop_pTipo: NúmeroPredeterminado:1Valores permitidos: 0 a 1max_tokensTipo: Número enteroPredeterminado:512Valores permitidos: 1 a 1024temperatureTipo: NúmeroPredeterminado:0.2Valores permitidos: 0 a 2
Etiquetas
- replicate
- llava
- captioning
- vqa
- vision-understanding
- open-weights
- image
Preguntas frecuentes
¿Qué es LLaVA 1.6 Vicuna 13B?
LLaVA 1.6 Vicuna 13B es un modelo de Community en la categoría Multimodal.
¿Cuánto cuesta LLaVA 1.6 Vicuna 13B en Railwail?
En Railwail, LLaVA 1.6 Vicuna 13B cuesta ≈ 0,1021 US$ por ejecución. Se te cobra por lo que cada solicitud realmente consume. El uso se paga con créditos prepagados; 1 crédito equivale a 0,01 US$.
¿Cuál es la ventana de contexto de LLaVA 1.6 Vicuna 13B?
La ventana de contexto de LLaVA 1.6 Vicuna 13B contiene 4096 tokens. Una respuesta puede tener hasta 1024 tokens.
¿Qué velocidad tiene LLaVA 1.6 Vicuna 13B?
Aún no hay suficientes ejecuciones medidas de LLaVA 1.6 Vicuna 13B en Railwail para indicar un tiempo de ejecución. Depende de la entrada, la configuración y la carga en el proveedor.
¿Es LLaVA 1.6 Vicuna 13B mejor que BLIP?
Depende de la tarea. LLaVA 1.6 Vicuna 13B (Community) y BLIP (Salesforce) son ambos modelos en la categoría Multimodal. La página de comparación muestra sus precios y especificaciones lado a lado.
Comparar LLaVA 1.6 Vicuna 13B y BLIP¿Puede LLaVA 1.6 Vicuna 13B procesar imágenes?
Sí. LLaVA 1.6 Vicuna 13B acepta imágenes como entrada además de texto.
Modelos comparables
Todos en esta categoría- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
Todos los modelos a través de una API
Una clave API para todos los modelos en Railwail. El uso se cobra desde créditos prepagados, 1 crédito = 0,01 US$.