
CogVLM2 19B
cogvlm2-19bTsinghua CogVLM2 19B with Llama-3 8B base plus 11B vision expert. Strong document understanding and visual reasoning, 8k context.
- Prezzo
- ≈ 0,0114 USD/esecuzione
- Contesto
- 8192 token
- Max. output
- 2048 token
- Input → output
- Testo + Immagine → Testo
- Sviluppatore
- Community
- Aggiornato
- 23 settembre 2026
Playground
Prova CogVLM2 19B
Nessuna maschera di input
Nessun modulo di input per questo modello
I suoi input non sono ancora documentati. Per evitare errori di esecuzione, non offriamo un modulo qui. Scegli invece un modello comparabile.
Examples
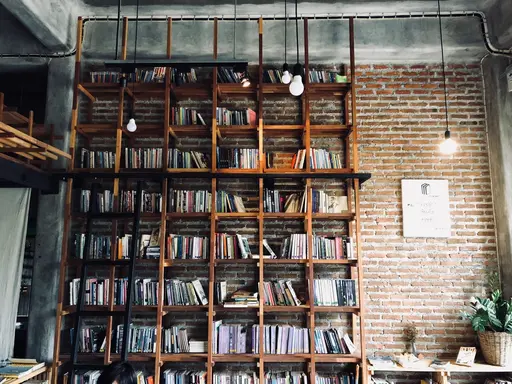 Input
Prompt
Describe this image.
Response
The image captures a well-lit, modern library or bookstore with a distinct industrial aesthetic. The main focus is a large, wooden bookshelf filled with an assortment of books, creating a warm and inviting atmosphere. The bookshelf is positioned against a rustic brick wall, which adds a touch of vintage charm to the space. The room is illuminated by hanging light bulbs, which dangle from the ceiling in a casual manner. There are also decorative elements such as a potted plant, a small framed sign, and a table with various items on it, enhancing the cozy ambiance. A person is seated at a desk in the foreground, suggesting the space is functional for reading or studying.
Informazioni su CogVLM2 19B
CogVLM2 19B è un modello di Community nella categoria Multimodale. Su Railwail, CogVLM2 19B costa ≈ 0,0114 USD per esecuzione. La finestra di contesto contiene 8192 token e una risposta può essere lunga fino a 2048 token.
Prezzi
| Esecuzione tipica (≈ 10 s su L40S) | 0,0114 USD per esecuzione |
|---|---|
| Tempo GPU (L40S) | 0,00117 USD per secondo GPU |
- Fatturato in base al tempo GPU effettivamente utilizzato. All'avvio, 3× il prezzo tipico viene riservato dal tuo saldo e regolato successivamente.
- 1 credito = 0,01 USD
Calcolatore di costi
Calcolatore prezzi
Tipico secondo il provider: circa 9,7 s
Totale
1,14 USD
114 crediti
Per esecuzione
0,0114 USD · 1,14 crediti
Fatturato in base al tempo GPU effettivo; questo è una stima.
API
Nessun esempio API verificato
L'API pubblica passa un formato di input diverso da quello richiesto da questo modello. Usa il playground sopra.
Specifiche
- ID modello
cogvlm2-19b- Sviluppatore
- Community
- Categoria
- Multimodale
- Input
- Testo, Immagine
- Output
- Testo
- Finestra di contesto
- 8192 token
- Output massimo
- 2048 token
- Fatturazione
- In base all'utilizzo (token o tempo GPU)
- Voce di catalogo aggiornata
- 23 settembre 2026
Etichette
- replicate
- multimodal
- vision-understanding
- tsinghua
- open-weights
Domande frequenti
Cos'è CogVLM2 19B?
CogVLM2 19B è un modello di Community nella categoria Multimodale.
Quanto costa CogVLM2 19B su Railwail?
Su Railwail, CogVLM2 19B costa ≈ 0,0114 USD per esecuzione. Ti viene addebitato ciò che ogni richiesta utilizza effettivamente. L'utilizzo viene pagato con crediti prepagati; 1 credito equivale a 0,01 USD.
Qual è la finestra di contesto di CogVLM2 19B?
La finestra di contesto di CogVLM2 19B contiene 8192 token. Una risposta può essere lunga fino a 2048 token.
Quanto è veloce CogVLM2 19B?
Non ci sono ancora abbastanza esecuzioni misurate di CogVLM2 19B su Railwail per indicare un tempo di esecuzione. Dipende dall'input, dalle impostazioni e dal carico presso il provider.
CogVLM2 19B è migliore di BLIP?
Dipende dall'attività. CogVLM2 19B (Community) e BLIP (Salesforce) sono entrambi modelli nella categoria Multimodale. La pagina di confronto mostra i loro prezzi e le specifiche affiancati.
Confronta CogVLM2 19B e BLIPCogVLM2 19B può elaborare immagini?
Sì. CogVLM2 19B accetta immagini come input oltre al testo.
Modelli comparabili
Tutti in questa categoria- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
Tutti i modelli tramite un'API
Una chiave API per tutti i modelli su Railwail. L'utilizzo viene addebitato da crediti prepagati, 1 credito = 0,01 USD.