
DeepSeek-VL 7B
deepseek-vl-7bDeepSeek-VL 7B chat model. Vision-language model with hybrid vision encoder and strong real-world visual question answering performance.
- Prezzo
- ≈ 0,0086 USD/esecuzione
- Contesto
- 4096 token
- Max. output
- 2048 token
- Input → output
- Testo + Immagine → Testo
- Sviluppatore
- DeepSeek
- Aggiornato
- 23 settembre 2026
Playground
Prova DeepSeek-VL 7B
Nessuna maschera di input
Nessun modulo di input per questo modello
I suoi input non sono ancora documentati. Per evitare errori di esecuzione, non offriamo un modulo qui. Scegli invece un modello comparabile.
Examples
 Input
Prompt
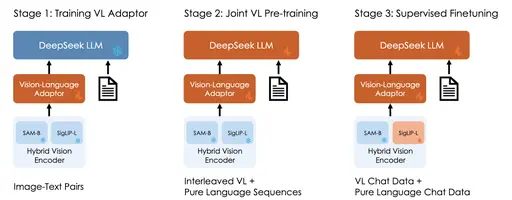
Describe each stage of this image
Response
The image depicts a three-stage process for training a vision-language model. 1. Stage 1: Training VL Adapter: In this stage, a vision-language adapter is trained using supervised fine-tuning. The adapter is trained on image-text pairs and pure language sequences. 2. Stage 2: Joint VL Pre-training: In this stage, a joint vision-language model is pre-trained using self-supervised learning. The model is trained on image-text pairs and pure language sequences. 3. Stage 3: Supervised Fine-tuning: In this stage, the model is fine-tuned on supervised tasks using image-text pairs and pure language sequences. The model is trained using a hybrid vision-language adapter, which combines a vision-language adapter with a language model. The model is trained on a variety of tasks, including image captioning, visual question answering, and visual reasoning. The model is able to understand the visual content of an image and generate a natural language description or answer.
 Input
Prompt
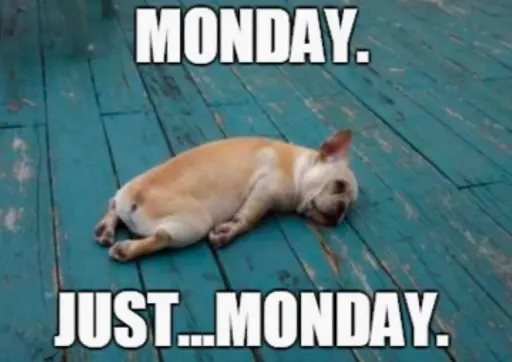
Describe this image
Response
The image you've provided is a meme featuring a French Bulldog lying on its side on a blue wooden floor. The dog's head is resting on its paws, and it appears to be sleeping. The meme has a text overlay that reads "MONDAY. JUST...MONDAY." This suggests that the meme is making a humorous comment about the start of the work week. The dog's relaxed posture and the text overlay together create a light-hearted and relatable message.
Informazioni su DeepSeek-VL 7B
DeepSeek-VL 7B è un modello di DeepSeek nella categoria Multimodale. Su Railwail, DeepSeek-VL 7B costa ≈ 0,0086 USD per esecuzione. La finestra di contesto contiene 4096 token e una risposta può essere lunga fino a 2048 token.
Prezzi
| Esecuzione tipica (≈ 7 s su L40S) | 0,0086 USD per esecuzione |
|---|---|
| Tempo GPU (L40S) | 0,00117 USD per secondo GPU |
- Fatturato in base al tempo GPU effettivamente utilizzato. All'avvio, 3× il prezzo tipico viene riservato dal tuo saldo e regolato successivamente.
- 1 credito = 0,01 USD
Calcolatore di costi
Calcolatore prezzi
Tipico secondo il provider: circa 7,3 s
Totale
0,86 USD
86 crediti
Per esecuzione
0,0086 USD · 0,86 crediti
Fatturato in base al tempo GPU effettivo; questo è una stima.
API
Nessun esempio API verificato
L'API pubblica passa un formato di input diverso da quello richiesto da questo modello. Usa il playground sopra.
Specifiche
- ID modello
deepseek-vl-7b- Sviluppatore
- DeepSeek
- Categoria
- Multimodale
- Input
- Testo, Immagine
- Output
- Testo
- Finestra di contesto
- 4096 token
- Output massimo
- 2048 token
- Fatturazione
- In base all'utilizzo (token o tempo GPU)
- Voce di catalogo aggiornata
- 23 settembre 2026
Etichette
- replicate
- multimodal
- vision-understanding
- deepseek
- open-weights
Domande frequenti
Cos'è DeepSeek-VL 7B?
DeepSeek-VL 7B è un modello di DeepSeek nella categoria Multimodale.
Quanto costa DeepSeek-VL 7B su Railwail?
Su Railwail, DeepSeek-VL 7B costa ≈ 0,0086 USD per esecuzione. Ti viene addebitato ciò che ogni richiesta utilizza effettivamente. L'utilizzo viene pagato con crediti prepagati; 1 credito equivale a 0,01 USD.
Qual è la finestra di contesto di DeepSeek-VL 7B?
La finestra di contesto di DeepSeek-VL 7B contiene 4096 token. Una risposta può essere lunga fino a 2048 token.
Quanto è veloce DeepSeek-VL 7B?
Non ci sono ancora abbastanza esecuzioni misurate di DeepSeek-VL 7B su Railwail per indicare un tempo di esecuzione. Dipende dall'input, dalle impostazioni e dal carico presso il provider.
DeepSeek-VL 7B è migliore di BLIP?
Dipende dall'attività. DeepSeek-VL 7B (DeepSeek) e BLIP (Salesforce) sono entrambi modelli nella categoria Multimodale. La pagina di confronto mostra i loro prezzi e le specifiche affiancati.
Confronta DeepSeek-VL 7B e BLIPDeepSeek-VL 7B può elaborare immagini?
Sì. DeepSeek-VL 7B accetta immagini come input oltre al testo.
Modelli comparabili
Tutti in questa categoria- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
Tutti i modelli tramite un'API
Una chiave API per tutti i modelli su Railwail. L'utilizzo viene addebitato da crediti prepagati, 1 credito = 0,01 USD.