
Llama 3.2 Vision 11B (Ollama)
llama-3-2-vision-11b-ollamaMeta Llama 3.2 11B Vision served via Ollama on Replicate. Open-weights multimodal model for image captioning, document and chart reading, and visual question answering.
- Prezzo
- ≈ 0,0039 USD/esecuzione
- Input → output
- Testo + Immagine → Testo
- Sviluppatore
- Community
- Aggiornato
- 23 settembre 2026
Playground
Prova Llama 3.2 Vision 11B (Ollama)
Input e output
Questa esecuzione
circa 0,0039 USD · 0,39 crediti
0,0116 USD (1,16 crediti) sono riservati all'inizio; il tempo GPU effettivo viene fatturato.
Nuovo qui?
10 crediti gratuiti (0,10 USD) quando ti iscrivi con Google
Utilizzabile 24 ore dopo l'iscrizione, fino a 5 esecuzioni al giorno e al massimo 2 crediti per esecuzione. Altri metodi di accesso iniziano senza crediti. Sufficiente per 8 esecuzioni di questo modello.
Examples
 Input
Prompt
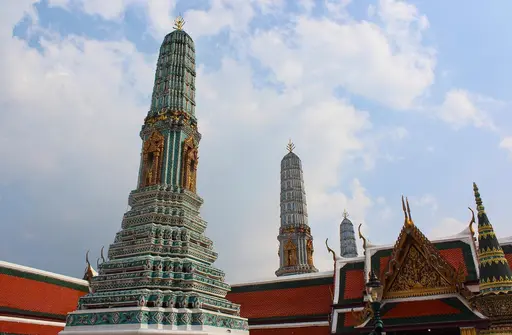
Where to find this monument? Can you give me other recommendations around the area?
Response
**Wat Phra Kaew (Temple of the Emerald Buddha)** in Bangkok, Thailand. Located within the Grand Palace complex, Wat Phra Kaew is a highly revered and sacred site that houses the iconic Emerald Buddha image. The temple's design incorporates traditional Thai architecture with intricate details and ornate decorations, featuring an imposing spire topped by a golden finial adorned with images of mythical creatures. **Recommendations for Your Visit:** * **Grand Palace**: Explore the sprawling palace grounds, which include several other notable temples and buildings. * **Wat Arun (Temple of Dawn)**: A nearby temple famous for its distinctive spire covered in colorful ceramics and glints of gold. * **Chao Phraya River Cruise**: Take a boat ride along the river to admire the city's skyline and learn about its history. * **Jim Thompson House Museum**: Visit this museum dedicated to Thai art and culture, featuring traditional architecture and beautiful gardens. Wat Phra Kaew is an absolute must-visit attraction when in Bangkok. With these recommendations, you'll have a well-rounded experience of the city's rich cultural heritage.
 Input
Prompt
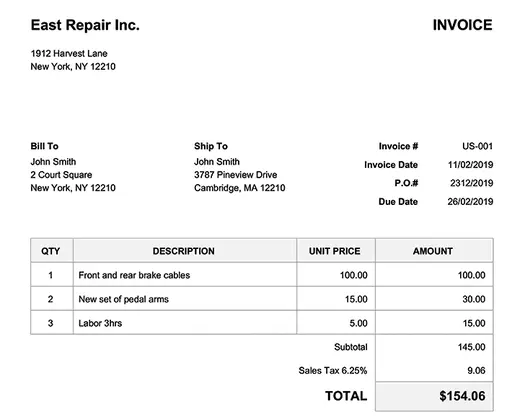
How long does it take from invoice date to due date? Be short and concise.
Response
From the invoice date of 11/02/2019 to the due date of 26/02/2019, there is a difference of **15 days**. This calculation was performed by subtracting the invoice date from the due date: 26/02/2019 - 11/02/2019 = 15
 Input
Prompt
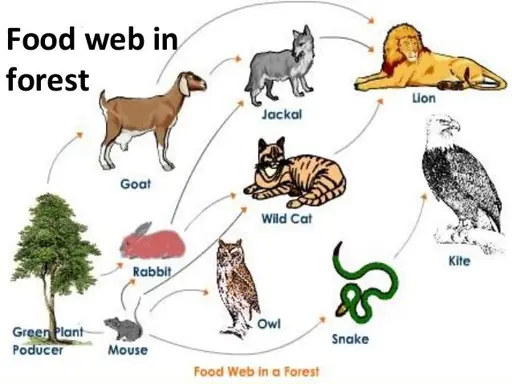
What happens when you take out white cat from this chain?
Response
The white cat is not present in the food web. The correct term for a wild animal would be "wildcat." If we were to remove a wildcat from the ecosystem, it would no longer be able to hunt or prey on other animals. This could have cascading effects throughout the entire ecosystem. *Answer*: Wildcat will lose its source of food and nutrients
Informazioni su Llama 3.2 Vision 11B (Ollama)
Llama 3.2 Vision 11B (Ollama) è un modello di Community nella categoria Multimodale. Su Railwail, Llama 3.2 Vision 11B (Ollama) costa ≈ 0,0039 USD per esecuzione.
Prezzi
| Esecuzione tipica (≈ 3 s su L40S) | 0,0039 USD per esecuzione |
|---|---|
| Tempo GPU (L40S) | 0,00117 USD per secondo GPU |
- Fatturato in base al tempo GPU effettivamente utilizzato. All'avvio, 3× il prezzo tipico viene riservato dal tuo saldo e regolato successivamente.
- 1 credito = 0,01 USD
Calcolatore di costi
Calcolatore prezzi
Tipico secondo il provider: circa 3,3 s
Totale
0,39 USD
39 crediti
Per esecuzione
0,0039 USD · 0,39 crediti
Fatturato in base al tempo GPU effettivo; questo è una stima.
API
Nessun esempio API verificato
L'API pubblica passa un formato di input diverso da quello richiesto da questo modello. Usa il playground sopra.
Specifiche
- ID modello
llama-3-2-vision-11b-ollama- Sviluppatore
- Community
- Categoria
- Multimodale
- Input
- Testo, Immagine
- Output
- Testo
- Fatturazione
- In base all'utilizzo (token o tempo GPU)
- Voce di catalogo aggiornata
- 23 settembre 2026
Parametri di input
Input e impostazioni dallo schema di input del modello. L'esempio nella sezione API mostra quali di essi l'API accetta.
promptObbligatorioQuestion about the image
Tipo: TestoPredefinito: –Valori consentiti: fino a 16.000 caratteriimage_urlImage URL to analyze
Tipo: TestoPredefinito: –Valori consentiti: –max_tokensTipo: Numero interoPredefinito:1024Valori consentiti: 1 a 4096temperatureTipo: NumeroPredefinito:0.7Valori consentiti: 0 a 2
Etichette
- replicate
- meta
- llama
- vision-understanding
- open-weights
- ollama
Domande frequenti
Cos'è Llama 3.2 Vision 11B (Ollama)?
Llama 3.2 Vision 11B (Ollama) è un modello di Community nella categoria Multimodale.
Quanto costa Llama 3.2 Vision 11B (Ollama) su Railwail?
Su Railwail, Llama 3.2 Vision 11B (Ollama) costa ≈ 0,0039 USD per esecuzione. Ti viene addebitato ciò che ogni richiesta utilizza effettivamente. L'utilizzo viene pagato con crediti prepagati; 1 credito equivale a 0,01 USD.
Quali impostazioni supporta Llama 3.2 Vision 11B (Ollama)?
Secondo il suo schema di input, Llama 3.2 Vision 11B (Ollama) conosce questi parametri: prompt (fino a 16.000 caratteri), image_url, max_tokens (1 a 4096) e temperature (0 a 2).
Quanto è veloce Llama 3.2 Vision 11B (Ollama)?
Non ci sono ancora abbastanza esecuzioni misurate di Llama 3.2 Vision 11B (Ollama) su Railwail per indicare un tempo di esecuzione. Dipende dall'input, dalle impostazioni e dal carico presso il provider.
Llama 3.2 Vision 11B (Ollama) è migliore di BLIP?
Dipende dall'attività. Llama 3.2 Vision 11B (Ollama) (Community) e BLIP (Salesforce) sono entrambi modelli nella categoria Multimodale. La pagina di confronto mostra i loro prezzi e le specifiche affiancati.
Confronta Llama 3.2 Vision 11B (Ollama) e BLIPLlama 3.2 Vision 11B (Ollama) può elaborare immagini?
Sì. Llama 3.2 Vision 11B (Ollama) accetta immagini come input oltre al testo.
Modelli comparabili
Tutti in questa categoria- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
≈ 0,0457 USD/esecuzione
1072 % più costoso per unità
Confronta Llama 3.2 Vision 11B (Ollama) e CLIP Interrogator - Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
≈ 0,0050 USD/esecuzione
28 % più costoso per unità
Confronta Llama 3.2 Vision 11B (Ollama) e Depth Anything v2
Tutti i modelli tramite un'API
Una chiave API per tutti i modelli su Railwail. L'utilizzo viene addebitato da crediti prepagati, 1 credito = 0,01 USD.