
LLaVA 1.6 Vicuna 13B
llava-1-6-vicuna-13bLLaVA 1.6 (LLaVA-NeXT) with a Vicuna-13B language backbone. Open vision-language chat model that describes images, answers questions, reads charts and reasons about scenes. Version 1.6 adds higher input resolution and better OCR and reasoning than LLaVA 1.5.
- Prezzo
- ≈ 0,1021 USD/esecuzione
- Contesto
- 4096 token
- Max. output
- 1024 token
- Input → output
- Testo + Immagine → Testo
- Sviluppatore
- Community
- Aggiornato
- 23 settembre 2026
Playground
Prova LLaVA 1.6 Vicuna 13B
Input e output
Questa esecuzione
circa 0,1021 USD · 10,21 crediti
0,3061 USD (30,61 crediti) sono riservati all'inizio; il tempo GPU effettivo viene fatturato.
Per account senza acquisti precedenti: le esecuzioni oltre 2 crediti richiedono una ricarica.
Nuovo qui?
10 crediti gratuiti (0,10 USD) quando ti iscrivi con Google
Utilizzabile 24 ore dopo l'iscrizione, fino a 5 esecuzioni al giorno e al massimo 2 crediti per esecuzione. Altri metodi di accesso iniziano senza crediti.
Examples
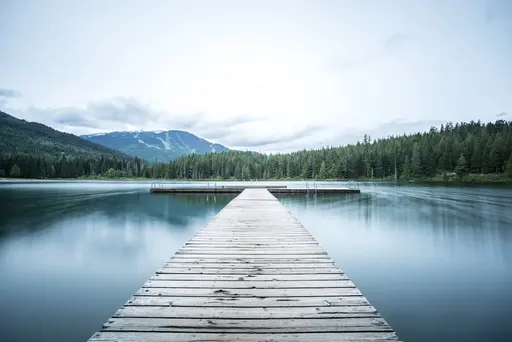 Input
Prompt
What should I take into account when visiting this place?
Response
When visiting a place like the one shown in the image, which appears to be a serene lake with a dock and surrounded by mountains and forests, you should consider the following: 1. **Weather Conditions**: Be prepared for the local weather. It can change rapidly, especially in mountainous areas, so check the forecast and dress in layers. 2. **Safety**: If you plan to go on the water, make sure you have a life jacket and know how to swim. If you're not a strong swimmer, consider wearing a life jacket even if you're just walking along the shore. 3. **Wildlife**: Be aware of the local wildlife and maintain a safe distance. Do not feed the animals, as this can disrupt their natural behavior and diet. 4. **Leave No Trace**: Respect the environment by not littering and by staying on designated paths or trails. 5. **Emergency Preparedness**: Have a first aid kit and know basic first aid. It's also a good idea to have a way to contact emergency services if needed. 6. **Navigation**: If you're going into the woods or on the water, have a map or GPS device and know how to use it. 7. **Hydration and Nutrition**: Bring enough water and food for your visit, especially if you'll be active. 8. **Clothing and Gear**: Wear appropriate clothing for the weather and activities you plan to do. Bring sturdy footwear if you plan to hike or walk on uneven terrain. 9. **Local Regulations**: Follow any posted rules or regulations, which might include fishing regulations, fire restrictions, or…
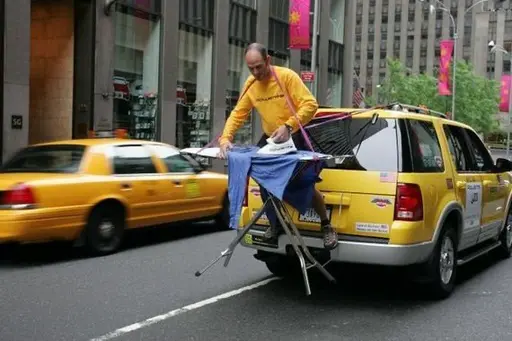 Input
Prompt
What is unusual about this image?
Response
The image shows a person ironing clothes on the back of a moving vehicle, which is an unusual and potentially dangerous activity. Ironing clothes while a vehicle is in motion can be hazardous for the person doing the ironing as well as for other road users. The person is at risk of losing balance and falling off the vehicle, which could result in serious injury. Additionally, the iron could potentially cause a fire or damage to the vehicle or its surroundings if it overheats or malfunctions. This scene is not a safe or typical way to iron clothes and is likely staged for comedic or dramatic effect.
Informazioni su LLaVA 1.6 Vicuna 13B
LLaVA 1.6 Vicuna 13B è un modello di Community nella categoria Multimodale. Su Railwail, LLaVA 1.6 Vicuna 13B costa ≈ 0,1021 USD per esecuzione. La finestra di contesto contiene 4096 token e una risposta può essere lunga fino a 1024 token.
Prezzi
| Esecuzione tipica (≈ 87 s su L40S) | 0,1021 USD per esecuzione |
|---|---|
| Tempo GPU (L40S) | 0,00117 USD per secondo GPU |
- Fatturato in base al tempo GPU effettivamente utilizzato. All'avvio, 3× il prezzo tipico viene riservato dal tuo saldo e regolato successivamente.
- 1 credito = 0,01 USD
Calcolatore di costi
Calcolatore prezzi
Tipico secondo il provider: circa 87,2 s
Totale
10,21 USD
1021 crediti
Per esecuzione
0,1021 USD · 10,21 crediti
Fatturato in base al tempo GPU effettivo; questo è una stima.
API
Nessun esempio API verificato
L'API pubblica passa un formato di input diverso da quello richiesto da questo modello. Usa il playground sopra.
Specifiche
- ID modello
llava-1-6-vicuna-13b- Sviluppatore
- Community
- Categoria
- Multimodale
- Input
- Testo, Immagine
- Output
- Testo
- Finestra di contesto
- 4096 token
- Output massimo
- 1024 token
- Fatturazione
- In base all'utilizzo (token o tempo GPU)
- Voce di catalogo aggiornata
- 23 settembre 2026
Parametri di input
Input e impostazioni dallo schema di input del modello. L'esempio nella sezione API mostra quali di essi l'API accetta.
imageObbligatorioImage to analyze
Tipo: TestoPredefinito: –Valori consentiti: –promptObbligatorioQuestion or instruction about the image
Tipo: TestoPredefinito:Describe this image in detail.Valori consentiti: fino a 4000 caratteritop_pTipo: NumeroPredefinito:1Valori consentiti: 0 a 1max_tokensTipo: Numero interoPredefinito:512Valori consentiti: 1 a 1024temperatureTipo: NumeroPredefinito:0.2Valori consentiti: 0 a 2
Etichette
- replicate
- llava
- captioning
- vqa
- vision-understanding
- open-weights
- image
Domande frequenti
Cos'è LLaVA 1.6 Vicuna 13B?
LLaVA 1.6 Vicuna 13B è un modello di Community nella categoria Multimodale.
Quanto costa LLaVA 1.6 Vicuna 13B su Railwail?
Su Railwail, LLaVA 1.6 Vicuna 13B costa ≈ 0,1021 USD per esecuzione. Ti viene addebitato ciò che ogni richiesta utilizza effettivamente. L'utilizzo viene pagato con crediti prepagati; 1 credito equivale a 0,01 USD.
Qual è la finestra di contesto di LLaVA 1.6 Vicuna 13B?
La finestra di contesto di LLaVA 1.6 Vicuna 13B contiene 4096 token. Una risposta può essere lunga fino a 1024 token.
Quanto è veloce LLaVA 1.6 Vicuna 13B?
Non ci sono ancora abbastanza esecuzioni misurate di LLaVA 1.6 Vicuna 13B su Railwail per indicare un tempo di esecuzione. Dipende dall'input, dalle impostazioni e dal carico presso il provider.
LLaVA 1.6 Vicuna 13B è migliore di BLIP?
Dipende dall'attività. LLaVA 1.6 Vicuna 13B (Community) e BLIP (Salesforce) sono entrambi modelli nella categoria Multimodale. La pagina di confronto mostra i loro prezzi e le specifiche affiancati.
Confronta LLaVA 1.6 Vicuna 13B e BLIPLLaVA 1.6 Vicuna 13B può elaborare immagini?
Sì. LLaVA 1.6 Vicuna 13B accetta immagini come input oltre al testo.
Modelli comparabili
Tutti in questa categoria- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
≈ 0,0457 USD/esecuzione
55 % più economico per unità
Confronta LLaVA 1.6 Vicuna 13B e CLIP Interrogator - Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
≈ 0,0050 USD/esecuzione
95 % più economico per unità
Confronta LLaVA 1.6 Vicuna 13B e Depth Anything v2
Tutti i modelli tramite un'API
Una chiave API per tutti i modelli su Railwail. L'utilizzo viene addebitato da crediti prepagati, 1 credito = 0,01 USD.