
DeepSeek-VL 7B
deepseek-vl-7bDeepSeek-VL 7B chat model. Vision-language model with hybrid vision encoder and strong real-world visual question answering performance.
- Cena
- ≈ 0,0086 USD/uruchomienie
- Kontekst
- 4096 tokenów
- Maks. wyjście
- 2048 tokenów
- Wejście → Wyjście
- Tekst + Obraz → Tekst
- Deweloper
- DeepSeek
- Zaktualizowano
- 23 września 2026
Playground
Spróbuj DeepSeek-VL 7B
Brak formularza wejściowego
Dla tego modelu nie ma jeszcze formularza wejściowego
Jego wejścia nie są jeszcze udokumentowane. Aby żaden przebieg nie zakończył się niepowodzeniem z powodu błędnego wejścia, nie oferujemy tutaj formularza. Zamiast tego wybierz porównywalny model.
Examples
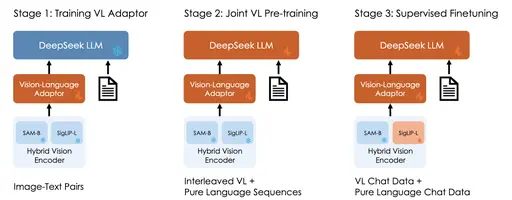 Input
Prompt
Describe each stage of this image
Response
The image depicts a three-stage process for training a vision-language model. 1. Stage 1: Training VL Adapter: In this stage, a vision-language adapter is trained using supervised fine-tuning. The adapter is trained on image-text pairs and pure language sequences. 2. Stage 2: Joint VL Pre-training: In this stage, a joint vision-language model is pre-trained using self-supervised learning. The model is trained on image-text pairs and pure language sequences. 3. Stage 3: Supervised Fine-tuning: In this stage, the model is fine-tuned on supervised tasks using image-text pairs and pure language sequences. The model is trained using a hybrid vision-language adapter, which combines a vision-language adapter with a language model. The model is trained on a variety of tasks, including image captioning, visual question answering, and visual reasoning. The model is able to understand the visual content of an image and generate a natural language description or answer.
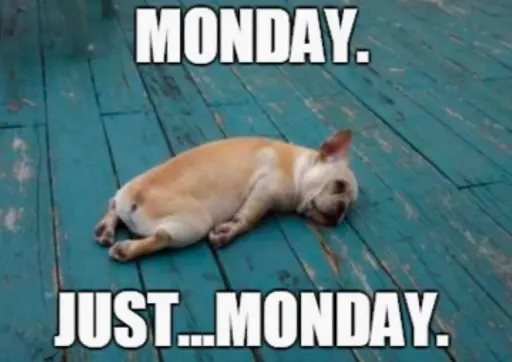 Input
Prompt
Describe this image
Response
The image you've provided is a meme featuring a French Bulldog lying on its side on a blue wooden floor. The dog's head is resting on its paws, and it appears to be sleeping. The meme has a text overlay that reads "MONDAY. JUST...MONDAY." This suggests that the meme is making a humorous comment about the start of the work week. The dog's relaxed posture and the text overlay together create a light-hearted and relatable message.
O DeepSeek-VL 7B
DeepSeek-VL 7B to model opracowany przez DeepSeek w kategorii Multimodalne. W serwisie Railwail DeepSeek-VL 7B kosztuje ≈ 0,0086 USD za uruchomienie. Okno kontekstu zawiera 4096 tokenów, a jedna odpowiedź może mieć do 2048 tokenów.
Ceny
| Typowe uruchomienie (≈ 7 s na L40S) | 0,0086 USD za uruchomienie |
|---|---|
| Czas GPU (L40S) | 0,00117 USD za sekundę GPU |
- Rozliczane są czasy GPU, które przebieg faktycznie zajmuje. Po uruchomieniu przebiegu 3× typowej ceny jest rezerwowane z Twojego salda i rozliczane później.
- 1 kredyt = 0,01 USD
Kalkulator kosztów
Kalkulator cen
Typowo według dostawcy: ok. 7,3 s
Razem
0,86 USD
86 kredytów
Za uruchomienie
0,0086 USD · 0,86 kredytów
Rozliczane są rzeczywiste sekundy GPU; wartość jest szacunkiem.
API
Brak zweryfikowanego przykładu API
Publiczny API przekazuje inny format wejściowy niż wymaga ten model. Użyj placu zabaw powyżej.
Specyfikacje
- ID modelu
deepseek-vl-7b- Deweloper
- DeepSeek
- Kategoria
- Multimodalne
- Wejście
- Tekst, Obraz
- Wyjście
- Tekst
- Okno kontekstu
- 4096 tokenów
- Maks. wyjście
- 2048 tokenów
- Rozliczenie
- Według użycia (tokeny lub czas GPU)
- Wpis w katalogu zaktualizowany
- 23 września 2026
Tagi
- replicate
- multimodal
- vision-understanding
- deepseek
- open-weights
Często zadawane pytania
Co to jest DeepSeek-VL 7B?
DeepSeek-VL 7B to model opracowany przez DeepSeek w kategorii Multimodalne.
Ile kosztuje DeepSeek-VL 7B w serwisie Railwail?
W serwisie Railwail DeepSeek-VL 7B kosztuje ≈ 0,0086 USD za uruchomienie. Opłata jest pobierana za to, co faktycznie zużywa każde żądanie. Użycie jest opłacane z przedpłaconych kredytów; 1 kredyt równa się 0,01 USD.
Jakie jest okno kontekstu DeepSeek-VL 7B?
Okno kontekstu DeepSeek-VL 7B zawiera 4096 tokenów. Jedna odpowiedź może mieć do 2048 tokenów.
Jak szybki jest DeepSeek-VL 7B?
Dla DeepSeek-VL 7B jest jeszcze zbyt mało zmierzonych przebiegów w serwisie Railwail, aby podać czas przebiegu. Zależy to od wejścia, ustawień i obciążenia u dostawcy.
Czy DeepSeek-VL 7B jest lepszy niż BLIP?
To zależy od zadania. DeepSeek-VL 7B (DeepSeek) i BLIP (Salesforce) to oba modele z kategorii Multimodalne. Strona porównania pokazuje ich ceny i specyfikacje obok siebie.
Porównaj DeepSeek-VL 7B i BLIPCzy DeepSeek-VL 7B może przetwarzać obrazy?
Tak. DeepSeek-VL 7B akceptuje obrazy jako wejście oprócz tekstu.
Porównywalne modele
Wszystkie w tej kategorii- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
Wszystkie modele przez jedno API
Jeden klucz API dla każdego modelu na Railwail. Opłaty pobierane są z przedpłaconych kredytów, 1 kredyt = 0,01 USD.