
LLaVA 1.6 Vicuna 13B
llava-1-6-vicuna-13bLLaVA 1.6 (LLaVA-NeXT) with a Vicuna-13B language backbone. Open vision-language chat model that describes images, answers questions, reads charts and reasons about scenes. Version 1.6 adds higher input resolution and better OCR and reasoning than LLaVA 1.5.
- Cena
- ≈ 0,1021 USD/uruchomienie
- Kontekst
- 4096 tokenów
- Maks. wyjście
- 1024 tokenów
- Wejście → Wyjście
- Tekst + Obraz → Tekst
- Deweloper
- Community
- Zaktualizowano
- 23 września 2026
Playground
Spróbuj LLaVA 1.6 Vicuna 13B
Wejście i wyjście
To uruchomienie
ok. 0,1021 USD · 10,21 kredytów
Na początek rezerwowane jest 0,3061 USD (30,61 kredytów); rozliczana jest rzeczywista czas GPU.
Dla kont bez wcześniejszego zakupu: uruchomienia powyżej 2 kredytów wymagają doładowania.
Nowy tutaj?
10 darmowych kredytów (0,10 USD) po zarejestrowaniu się przez Google
Dostępne 24 godzin po rejestracji, do 5 uruchomień dziennie i maksymalnie 2 kredytów na uruchomienie. Inne metody logowania uruchamiają się bez kredytów.
Examples
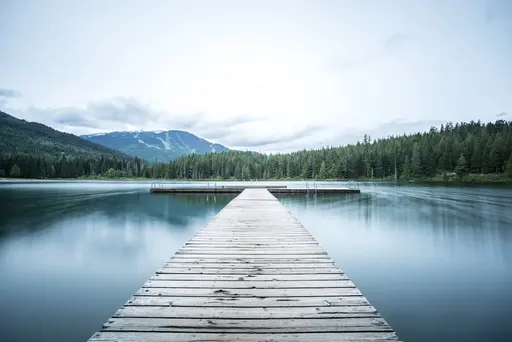 Input
Prompt
What should I take into account when visiting this place?
Response
When visiting a place like the one shown in the image, which appears to be a serene lake with a dock and surrounded by mountains and forests, you should consider the following: 1. **Weather Conditions**: Be prepared for the local weather. It can change rapidly, especially in mountainous areas, so check the forecast and dress in layers. 2. **Safety**: If you plan to go on the water, make sure you have a life jacket and know how to swim. If you're not a strong swimmer, consider wearing a life jacket even if you're just walking along the shore. 3. **Wildlife**: Be aware of the local wildlife and maintain a safe distance. Do not feed the animals, as this can disrupt their natural behavior and diet. 4. **Leave No Trace**: Respect the environment by not littering and by staying on designated paths or trails. 5. **Emergency Preparedness**: Have a first aid kit and know basic first aid. It's also a good idea to have a way to contact emergency services if needed. 6. **Navigation**: If you're going into the woods or on the water, have a map or GPS device and know how to use it. 7. **Hydration and Nutrition**: Bring enough water and food for your visit, especially if you'll be active. 8. **Clothing and Gear**: Wear appropriate clothing for the weather and activities you plan to do. Bring sturdy footwear if you plan to hike or walk on uneven terrain. 9. **Local Regulations**: Follow any posted rules or regulations, which might include fishing regulations, fire restrictions, or…
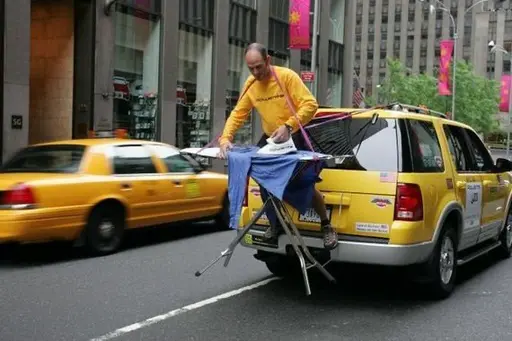 Input
Prompt
What is unusual about this image?
Response
The image shows a person ironing clothes on the back of a moving vehicle, which is an unusual and potentially dangerous activity. Ironing clothes while a vehicle is in motion can be hazardous for the person doing the ironing as well as for other road users. The person is at risk of losing balance and falling off the vehicle, which could result in serious injury. Additionally, the iron could potentially cause a fire or damage to the vehicle or its surroundings if it overheats or malfunctions. This scene is not a safe or typical way to iron clothes and is likely staged for comedic or dramatic effect.
O LLaVA 1.6 Vicuna 13B
LLaVA 1.6 Vicuna 13B to model opracowany przez Community w kategorii Multimodalne. W serwisie Railwail LLaVA 1.6 Vicuna 13B kosztuje ≈ 0,1021 USD za uruchomienie. Okno kontekstu zawiera 4096 tokenów, a jedna odpowiedź może mieć do 1024 tokenów.
Ceny
| Typowe uruchomienie (≈ 87 s na L40S) | 0,1021 USD za uruchomienie |
|---|---|
| Czas GPU (L40S) | 0,00117 USD za sekundę GPU |
- Rozliczane są czasy GPU, które przebieg faktycznie zajmuje. Po uruchomieniu przebiegu 3× typowej ceny jest rezerwowane z Twojego salda i rozliczane później.
- 1 kredyt = 0,01 USD
Kalkulator kosztów
Kalkulator cen
Typowo według dostawcy: ok. 87,2 s
Razem
10,21 USD
1021 kredytów
Za uruchomienie
0,1021 USD · 10,21 kredytów
Rozliczane są rzeczywiste sekundy GPU; wartość jest szacunkiem.
API
Brak zweryfikowanego przykładu API
Publiczny API przekazuje inny format wejściowy niż wymaga ten model. Użyj placu zabaw powyżej.
Specyfikacje
- ID modelu
llava-1-6-vicuna-13b- Deweloper
- Community
- Kategoria
- Multimodalne
- Wejście
- Tekst, Obraz
- Wyjście
- Tekst
- Okno kontekstu
- 4096 tokenów
- Maks. wyjście
- 1024 tokenów
- Rozliczenie
- Według użycia (tokeny lub czas GPU)
- Wpis w katalogu zaktualizowany
- 23 września 2026
Parametry wejściowe
Dane wejściowe i ustawienia ze schematu wejściowego modelu. Przykład w sekcji API pokazuje, które z nich API akceptuje.
imagewymaganeImage to analyze
Typ: TekstDomyślnie: –Dozwolone wartości: –promptwymaganeQuestion or instruction about the image
Typ: TekstDomyślnie:Describe this image in detail.Dozwolone wartości: do 4000 znakówtop_pTyp: LiczbaDomyślnie:1Dozwolone wartości: 0 do 1max_tokensTyp: Liczba całkowitaDomyślnie:512Dozwolone wartości: 1 do 1024temperatureTyp: LiczbaDomyślnie:0.2Dozwolone wartości: 0 do 2
Tagi
- replicate
- llava
- captioning
- vqa
- vision-understanding
- open-weights
- image
Często zadawane pytania
Co to jest LLaVA 1.6 Vicuna 13B?
LLaVA 1.6 Vicuna 13B to model opracowany przez Community w kategorii Multimodalne.
Ile kosztuje LLaVA 1.6 Vicuna 13B w serwisie Railwail?
W serwisie Railwail LLaVA 1.6 Vicuna 13B kosztuje ≈ 0,1021 USD za uruchomienie. Opłata jest pobierana za to, co faktycznie zużywa każde żądanie. Użycie jest opłacane z przedpłaconych kredytów; 1 kredyt równa się 0,01 USD.
Jakie jest okno kontekstu LLaVA 1.6 Vicuna 13B?
Okno kontekstu LLaVA 1.6 Vicuna 13B zawiera 4096 tokenów. Jedna odpowiedź może mieć do 1024 tokenów.
Jak szybki jest LLaVA 1.6 Vicuna 13B?
Dla LLaVA 1.6 Vicuna 13B jest jeszcze zbyt mało zmierzonych przebiegów w serwisie Railwail, aby podać czas przebiegu. Zależy to od wejścia, ustawień i obciążenia u dostawcy.
Czy LLaVA 1.6 Vicuna 13B jest lepszy niż BLIP?
To zależy od zadania. LLaVA 1.6 Vicuna 13B (Community) i BLIP (Salesforce) to oba modele z kategorii Multimodalne. Strona porównania pokazuje ich ceny i specyfikacje obok siebie.
Porównaj LLaVA 1.6 Vicuna 13B i BLIPCzy LLaVA 1.6 Vicuna 13B może przetwarzać obrazy?
Tak. LLaVA 1.6 Vicuna 13B akceptuje obrazy jako wejście oprócz tekstu.
Porównywalne modele
Wszystkie w tej kategorii- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
- CLIP InterrogatorCommunity
pharmapsychotic's CLIP Interrogator. Takes an image and produces a Stable-Diffusion-style text prompt by combining BLIP captioning with CLIP to rank likely subjects, artists, mediums and styles. Commonly used to reverse-engineer a prompt from an existing picture.
- Depth Anything v2Community
Monocular depth-estimation model trained on 595k labeled and 62M unlabeled images. Strong zero-shot generalization in indoor and outdoor scenes.
Wszystkie modele przez jedno API
Jeden klucz API dla każdego modelu na Railwail. Opłaty pobierane są z przedpłaconych kredytów, 1 kredyt = 0,01 USD.