
LLaVA v1.6 34B
llava-v1-6-34bLLaVA v1.6 on a Nous-Hermes-2 34B base, served on Replicate. Open-source vision-language assistant for image question answering, description and visual reasoning at higher resolution.
- Status
- Unavailable
- Input → output
- Text + Image → Text
- Developer
- Community
- Updated
- September 23, 2026
LLaVA v1.6 34B is currently unavailable
Currently unavailable: this model has been deactivated.
You can still read the details on this page. Pick one of the available alternatives below to run a comparable model right away.
Go to alternativesComparable models
All in this category- BLIPSalesforce
Salesforce BLIP. Vision-language model for image captioning and visual question answering. Given an image it writes a short natural-language caption, or answers a question about the image when one is supplied. A widely used baseline for automatic captioning.
≈ $0.00030/run
- Claude Opus 4.7Anthropic
Anthropic's April 2026 flagship. 87.6% on SWE-bench Verified, 3x higher image resolution, output self-verification, vision + reasoning.
$6.00/1M in
- Claude Sonnet 4.6Anthropic
Anthropic's balanced mid-tier model from February 2026. Best price/performance for production workloads: 5x cheaper than Opus, near-flagship quality.
$3.60/1M in
Playground
Try LLaVA v1.6 34B
Input & output
Currently unavailable: this model has been deactivated.
The playground is disabled. You can find comparable models in the same category: Browse alternatives
This run
No price – currently unavailable.
New here?
10 free credits ($0.10) when you sign up with Google
Usable 24 hours after sign-up, up to 5 runs per day and at most 2 credits per run. Other sign-in methods start without credits.
Examples
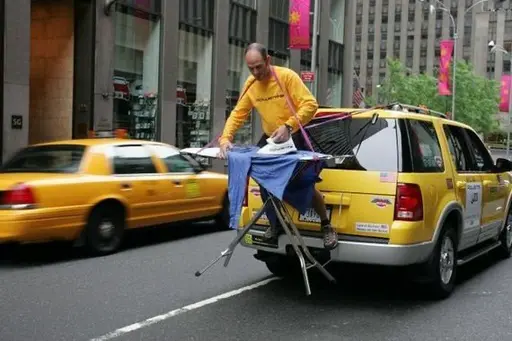 Input
Prompt
What's unusual about this image?
Response
The image shows a person ironing clothes on an ironing board that is placed on the back of a moving vehicle, specifically a yellow taxi. This is an unusual and unsafe situation for several reasons: 1. The person is performing a task that requires concentration and stability, which is difficult to maintain while on a moving vehicle. 2. The ironing board is not secured in place, which increases the risk of it falling off the vehicle, potentially causing injury to the person or others on the road. 3. The person is not wearing any protective gear, such as a harness or safety belt, which would be necessary to secure them in place while the vehicle is in motion. 4. The act of ironing clothes in such a location is impractical and not a typical setting for this activity. 5. The presence of the iron and the ironing board on the back of a moving vehicle poses a hazard to other road users, as it could fall off and cause accidents. Overall, the image depicts a dangerous and unusual situation that is not safe for the person involved or for others on the road.
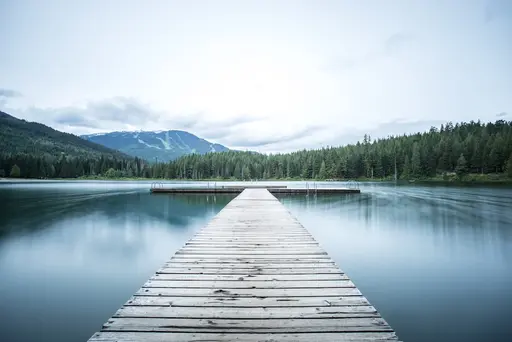 Input
Prompt
What are the things I should be cautious about when I visit here?
Response
When visiting a location like the one shown in the image, which appears to be a serene lake with a dock and surrounded by forested hills, there are several things you should be cautious about: 1. Water Safety: If you plan to swim, make sure you're aware of the water conditions and any potential hazards such as currents, underwater rocks, or cold water temperatures. 2. Dock Sturdiness: Check the dock for any signs of damage or instability before stepping on it. Wooden docks can sometimes be slippery, especially if they're wet. 3. Wildlife: Be aware of the local wildlife and maintain a safe distance. Do not feed or approach animals, as this can disrupt their natural behavior and pose a risk to both you and the animals. 4. Weather Conditions: Be prepared for changes in weather. Sudden storms can occur, especially in mountainous areas, so have appropriate clothing and be ready to seek shelter if necessary. 5. Personal Safety: If you're alone, let someone know where you're going and when you expect to return. It's also a good idea to carry a charged phone in case of emergencies. 6. Leave No Trace: Respect the environment by not littering, not disturbing the natural habitat, and staying on designated paths or areas. 7. Navigation: If you're venturing into the forest or hiking, make sure you have a map or GPS device and know how to use them. It's easy to get lost in unfamiliar terrain. 8. Insects and Plants: Be cautious of insects like mosquitoes and ticks, and be aware of…
About LLaVA v1.6 34B
LLaVA v1.6 34B is a model by Community in the Multimodal category. LLaVA v1.6 34B is currently not available on Railwail.
Pricing
Currently unavailable: this model has been deactivated. There is no price for this model at the moment, so it cannot be run.
API
No verified API example
The public API passes a different input format than this model needs. Use the playground above.
Specifications
- Model ID
llava-v1-6-34b- Developer
- Community
- Category
- Multimodal
- Input
- Text, Image
- Output
- Text
- Catalog entry updated
- September 23, 2026
Input parameters
Inputs and settings from the model's input schema. The example in the API section shows which of them the API accepts.
promptrequiredQuestion about the image
Type: TextDefault: –Allowed values: up to 16,000 charactersimage_urlImage URL to analyze
Type: TextDefault: –Allowed values: –max_tokensType: IntegerDefault:1024Allowed values: 1 to 4,096temperatureType: NumberDefault:0.2Allowed values: 0 to 2
Tags
- replicate
- llava
- vision-understanding
- open-source
- vqa
Frequently asked questions
What is LLaVA v1.6 34B?
LLaVA v1.6 34B is a model by Community in the Multimodal category. It is listed on Railwail but cannot be run at the moment.
How much does LLaVA v1.6 34B cost on Railwail?
LLaVA v1.6 34B cannot be run on Railwail at the moment, so there is no current price. Available alternatives with prices are listed further down this page.
Which settings does LLaVA v1.6 34B support?
According to its input schema, LLaVA v1.6 34B knows these parameters: prompt (up to 16,000 characters), image_url, max_tokens (1 to 4,096), and temperature (0 to 2).
How fast is LLaVA v1.6 34B?
There are not enough measured runs of LLaVA v1.6 34B on Railwail yet to state a run time. It depends on the input, the settings and the load at the provider.
Is LLaVA v1.6 34B better than BLIP?
That depends on the task. LLaVA v1.6 34B (Community) and BLIP (Salesforce) are both models in the Multimodal category. The comparison page shows their prices and specifications side by side.
Compare LLaVA v1.6 34B and BLIPCan LLaVA v1.6 34B process images?
Yes. LLaVA v1.6 34B accepts images as input in addition to text.
Can I use LLaVA v1.6 34B right now?
Currently unavailable: this model has been deactivated. The page stays online; available alternatives from the same category are listed further down.
All models through one API
One API key for every model on Railwail. Usage is charged from prepaid credits, 1 credit = $0.01.